
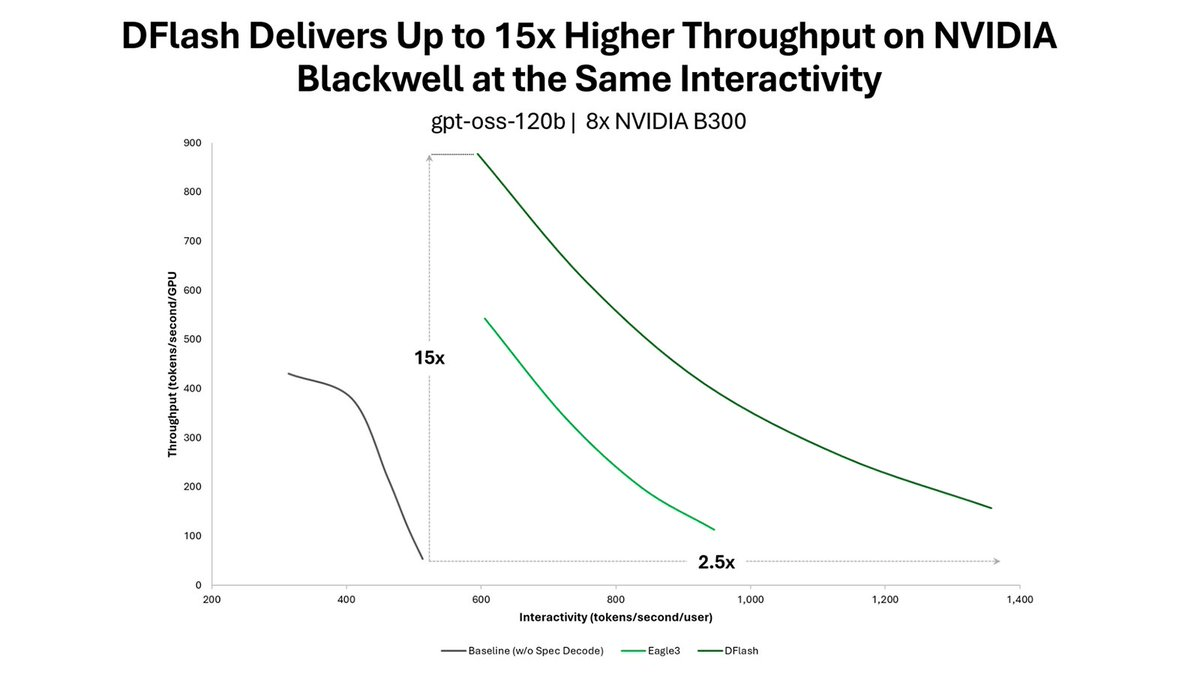
NVIDIA Backs DFlash to Boost LLM Inference 15x on Blackwell
NVIDIA's inference stack now supports DFlash, a block-diffusion speculative decoding method that delivers up to 15x throughput gains on Blackwell GPUs with zero code changes.
20 stories
NVIDIA's inference stack now supports DFlash, a block-diffusion speculative decoding method that delivers up to 15x throughput gains on Blackwell GPUs with zero code changes.
Automagic v2 brings a fused backward pass and per-layer adaptive learning rates to AI Toolkit, slashing VRAM from 13.65GB to 2.75GB versus Prodigy on a 500M-param model.
Microsoft's MAI-Voice-2 brings tag-level emotion control and zero-shot voice cloning to 15 languages, preferred over real human recordings nearly half the time

Databricks launches a revamped startup program offering up to $200K in credits spanning its full data and AI platform plus Neon's serverless Postgres, targeting pre-seed to Series A founders.
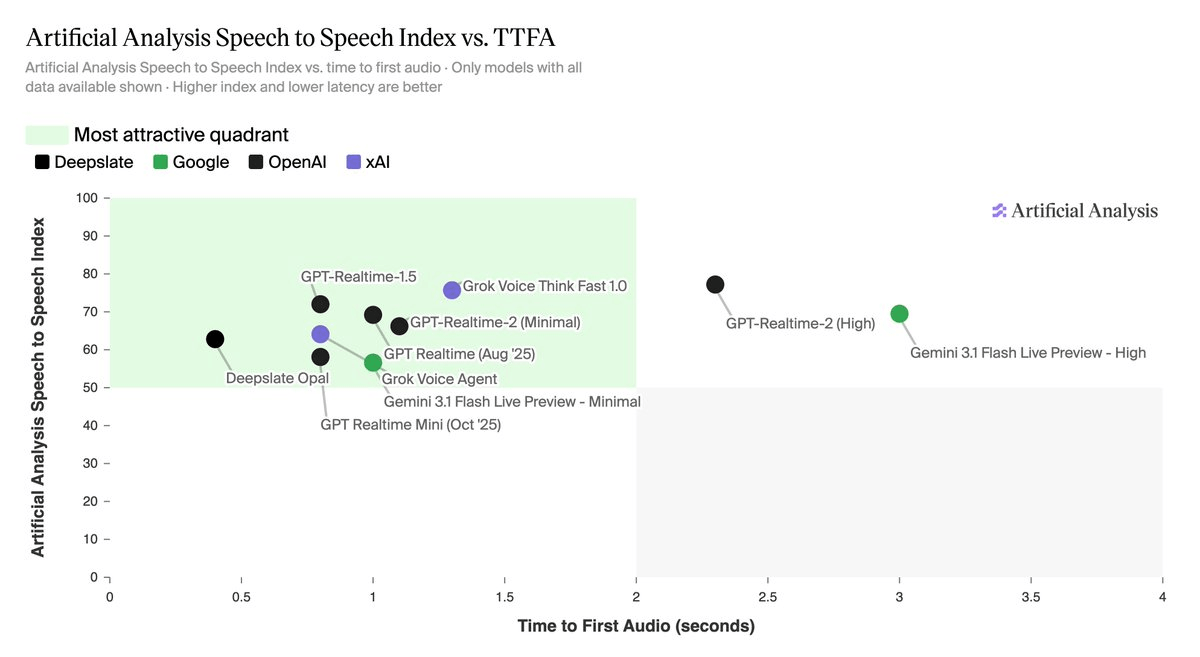
Artificial Analysis launches the first composite Speech-to-Speech Index, revealing a hard ceiling on agentic voice tasks where every model scores below 53%
Manus adds smart source suggestions to projects, letting the agent learn which web pages to reference across future tasks — no URL hunting required.
Krea open-sources its 12B aesthetic image model as two weights: a malleable mid-training checkpoint for fine-tuning and a distilled 8-step version for fast 2K generation
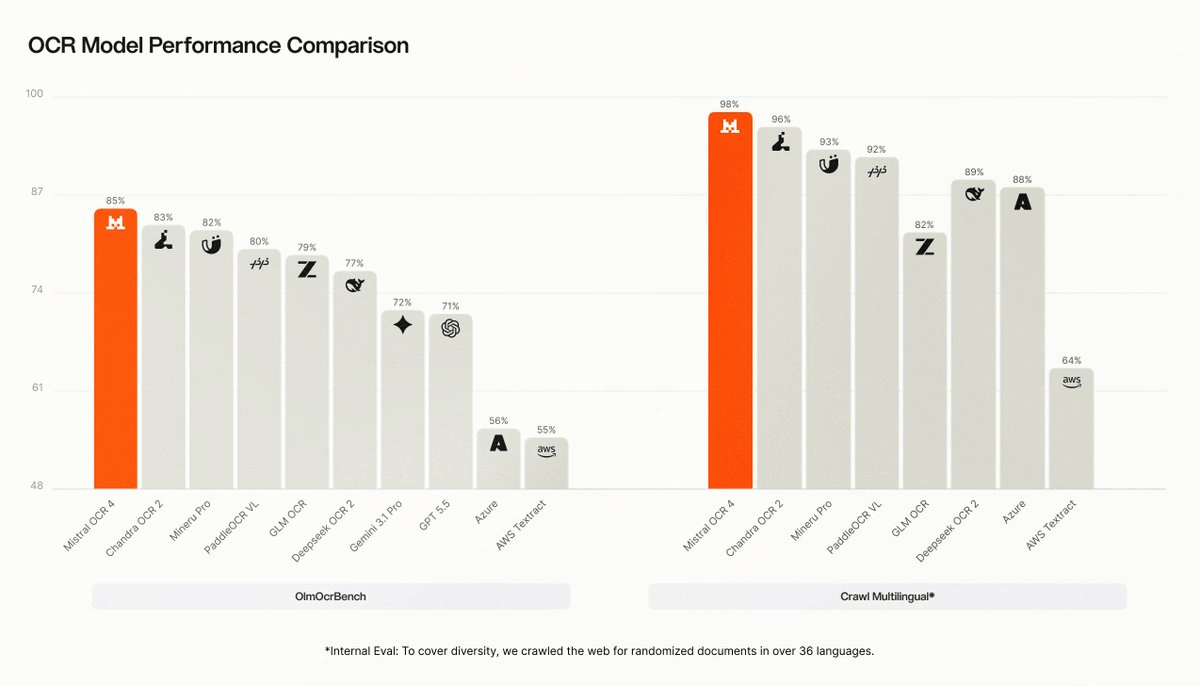
Mistral OCR 4 adds bounding boxes, block classification, and confidence scores, topping OlmOCRBench with a 72% average human-preference win rate across 12+ languages
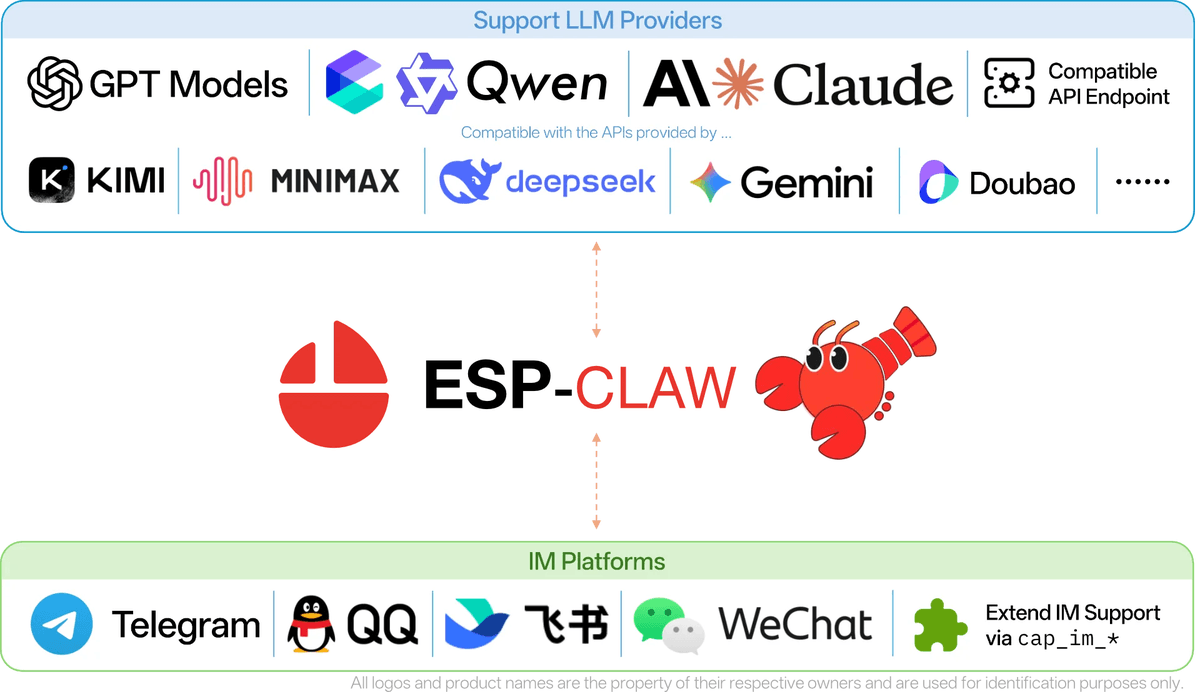
Espressif's ESP-Claw turns a $3 ESP32 chip into a conversational AI agent that senses, decides, and acts at the edge — no cloud required for execution.
Baidu's Unlimited-OCR uses a novel attention mechanism to parse entire multi-page documents in a single pass, eliminating the chunking bottleneck that plagues current OCR pipelines.
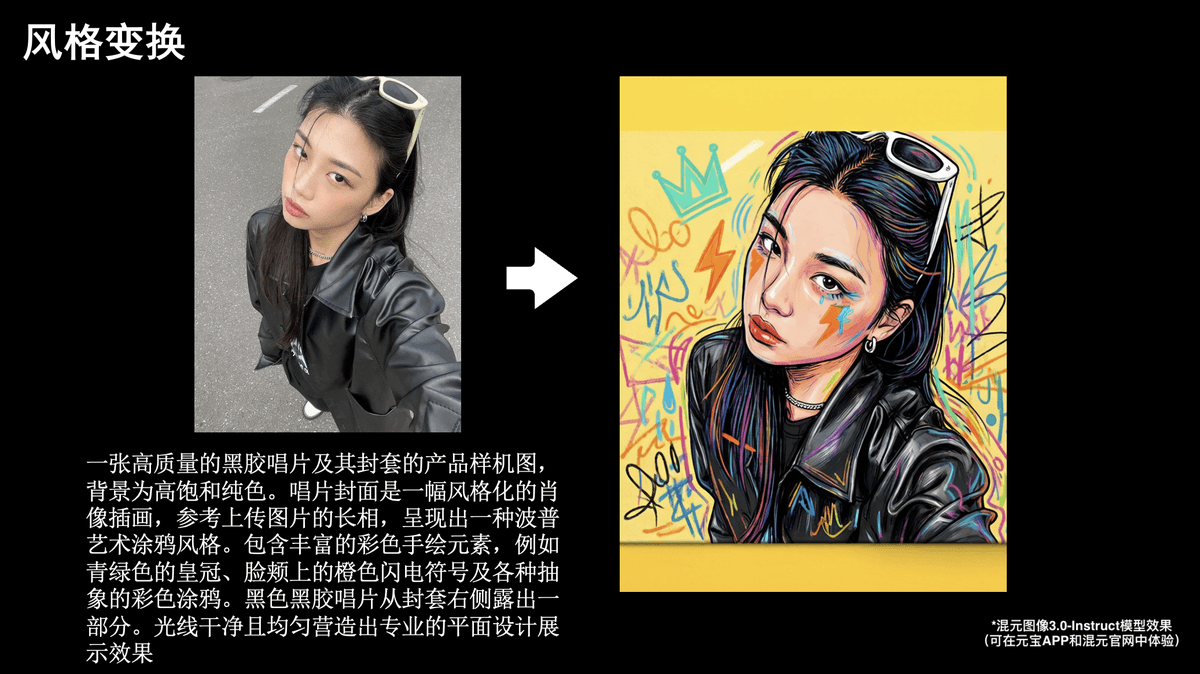
Tencent open-sources HunyuanImage 3.0, an 80B MoE model that reasons before generating images, rivaling closed-source leaders like GPT-Image and Midjourney.
Kyutai's Pocket TTS adds French, Spanish, Portuguese, Italian, and German to its 100M-parameter model that runs faster than real-time on a laptop CPU with no GPU required.
CLIProxyAPI turns your Gemini, Claude, and Codex CLI subscriptions into a unified OpenAI-compatible API server with multi-account load balancing
PINTO0309 converts DDN, a state-of-the-art edge detector, to ONNX and multi-framework formats for immediate edge deployment
RAPTOR turns Claude Code into a full autonomous security agent that scans, validates, exploits, and patches vulnerabilities — now with multi-model support and Z3 constraint solving
DeepSeek's open-source CUDA kernel library gets Mega MoE, FP8×FP4 GEMM, and a fused MoE mega-kernel that overlaps NVLink comms with tensor core compute
Alibaba's Qwen3-VL-Embedding brings text, image, video, and document search into a single open-source embedding model, topping the MMEB-V2 leaderboard at 77.8
A W4A16 quantized build of Baidu's 3B Unlimited-OCR shrinks the model for consumer GPUs while preserving one-shot long-document parsing quality.
GEPA optimizes prompts, code, and agent architectures using LLM reflection on execution traces, beating RL methods with 35x fewer rollouts.
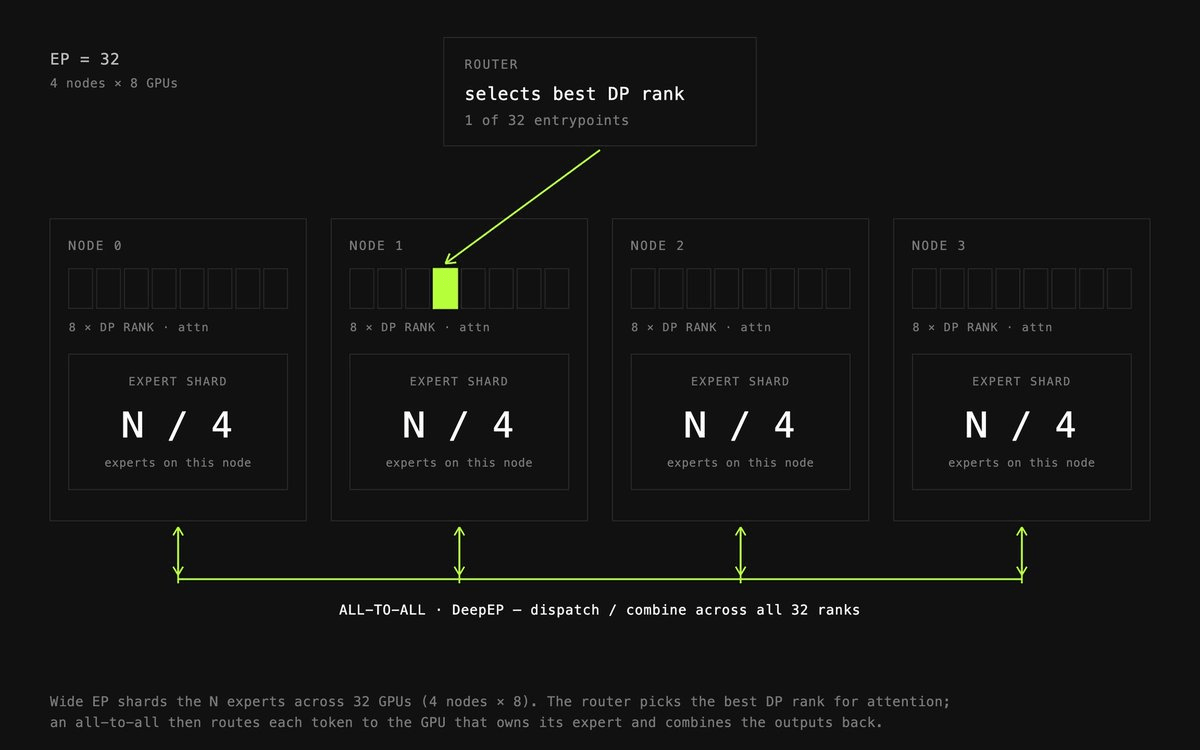
Prime Intellect's prime-rl v0.6.0 brings RL post-training to trillion-parameter MoE models with sub-5-minute step times on 28 H200 nodes