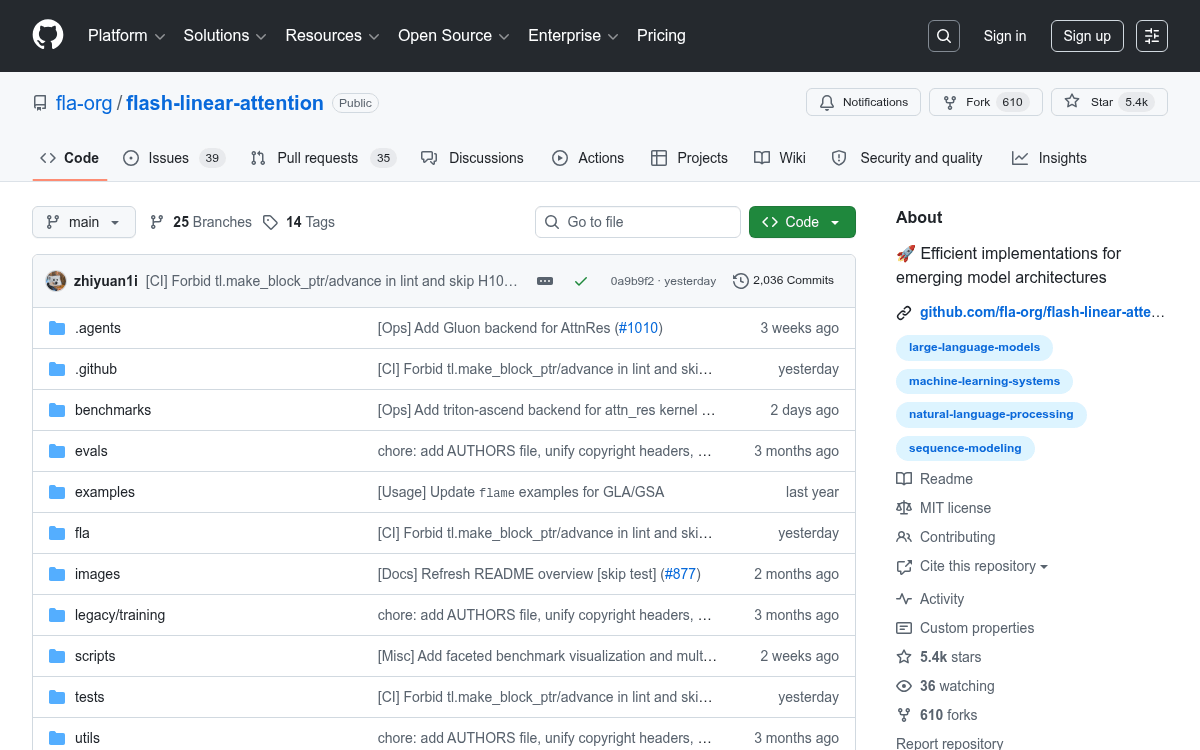
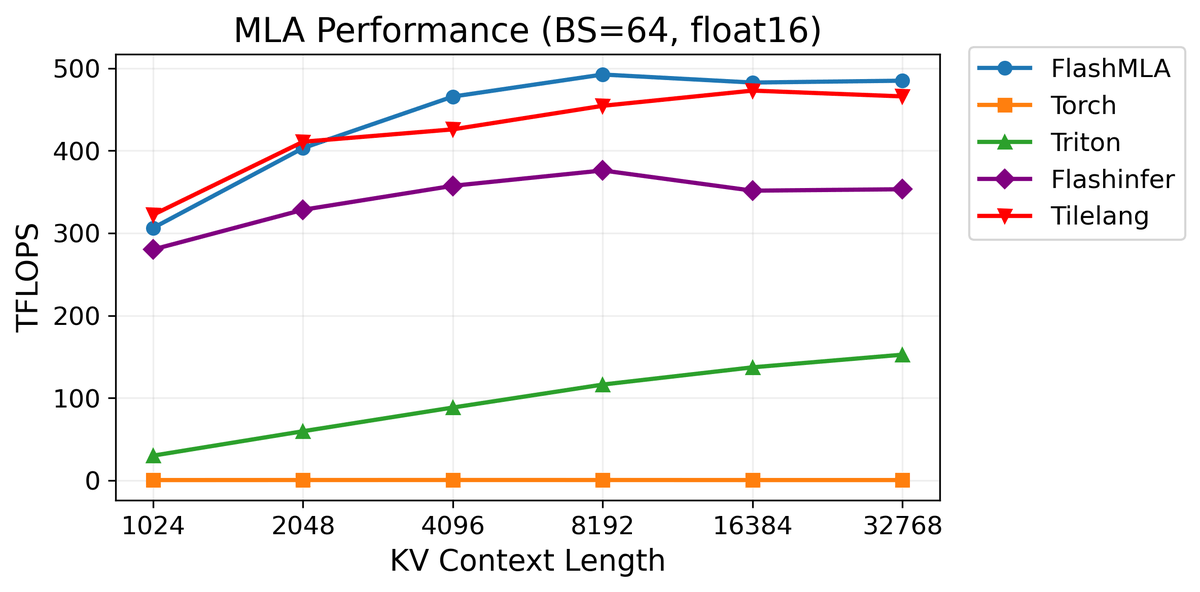
Flash Linear Attention is the open-source kernel library quietly powering production LLMs like Qwen3.5 and Kimi, with 30+ subquadratic architectures in one place
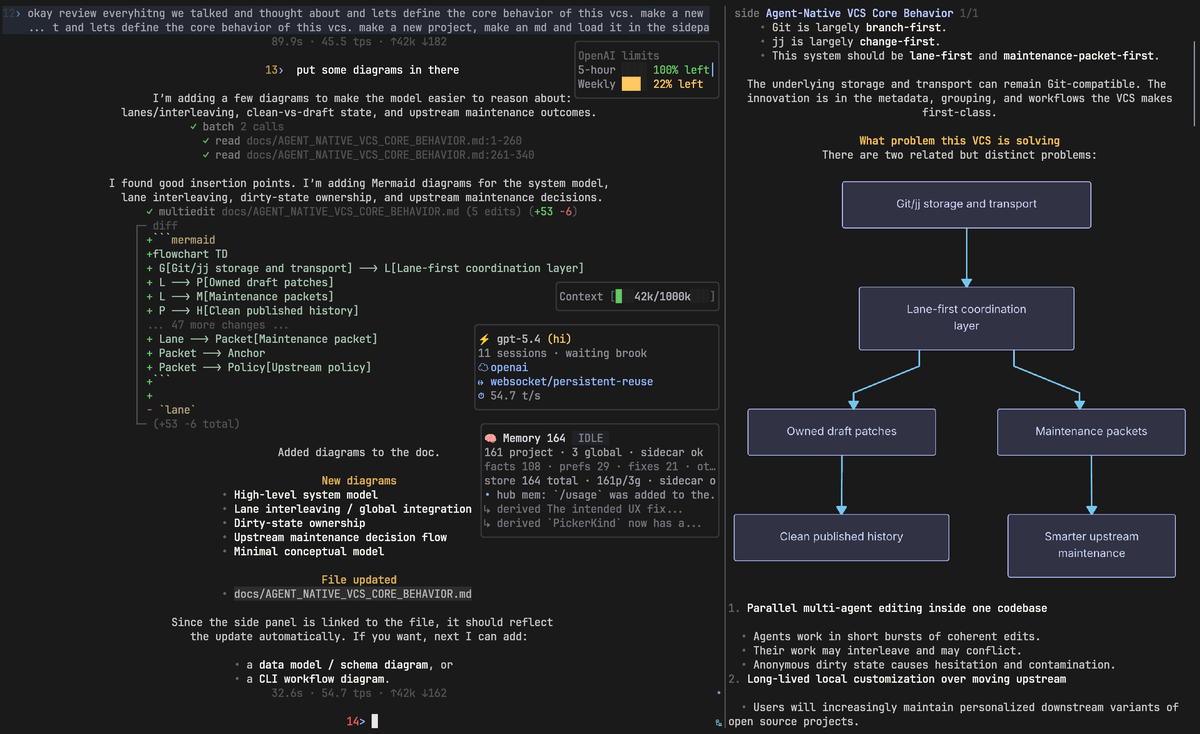
jcode is a Rust-native coding agent harness that boots in 14ms, runs 10+ parallel agents on 8GB of RAM, and lets the agent rewrite its own source code — all free and open-source.
Exa's AI-native web search is now a one-command install inside xAI's Grok Build terminal agent, bringing real-time search and deep research to coding workflows
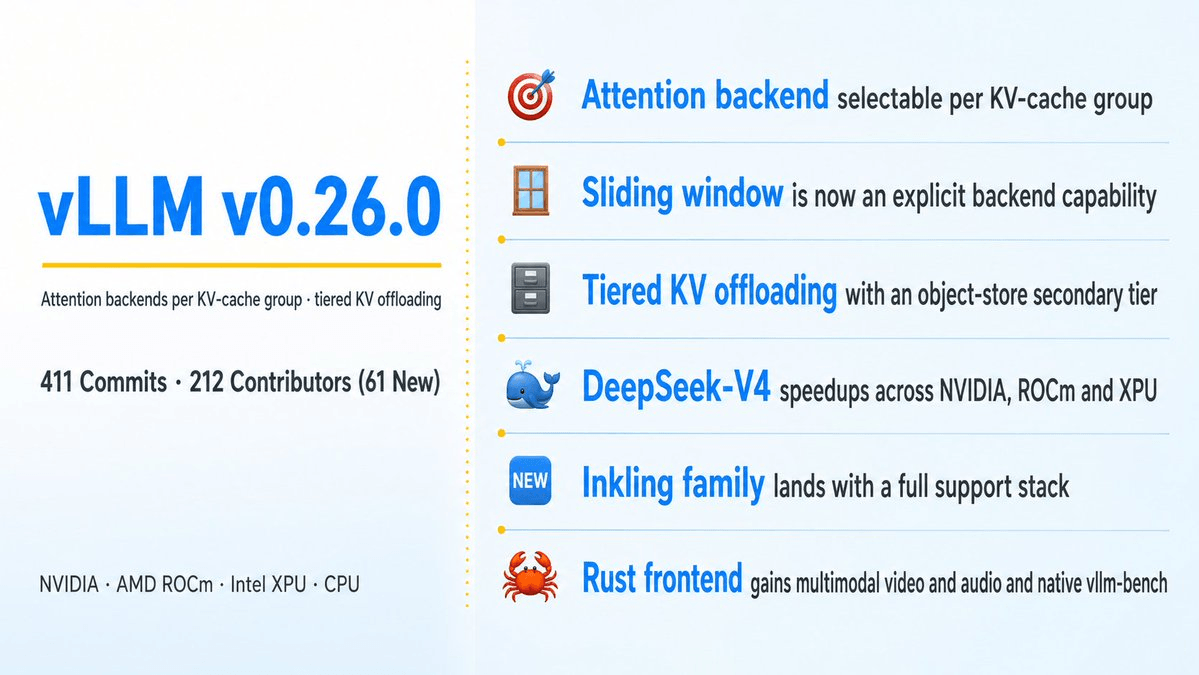
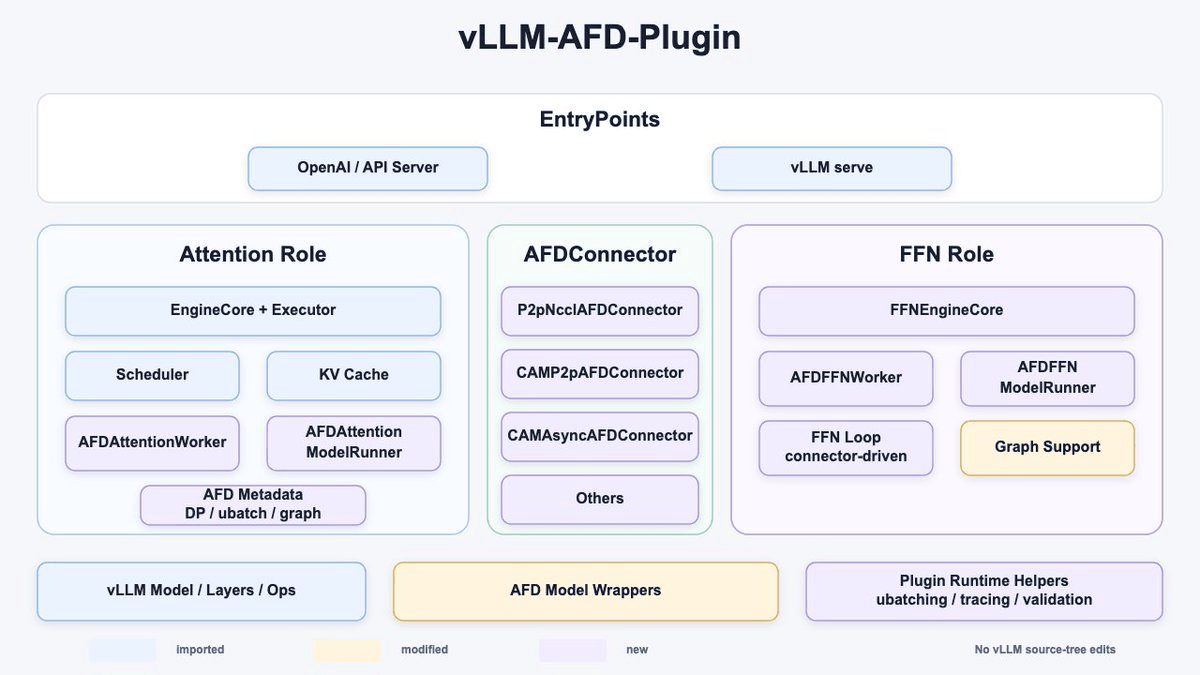
vLLM's new AFD Plugin splits Attention and expert computation into independent services, unlocking +11% decode throughput for large MoE models like DeepSeek-V3.2