
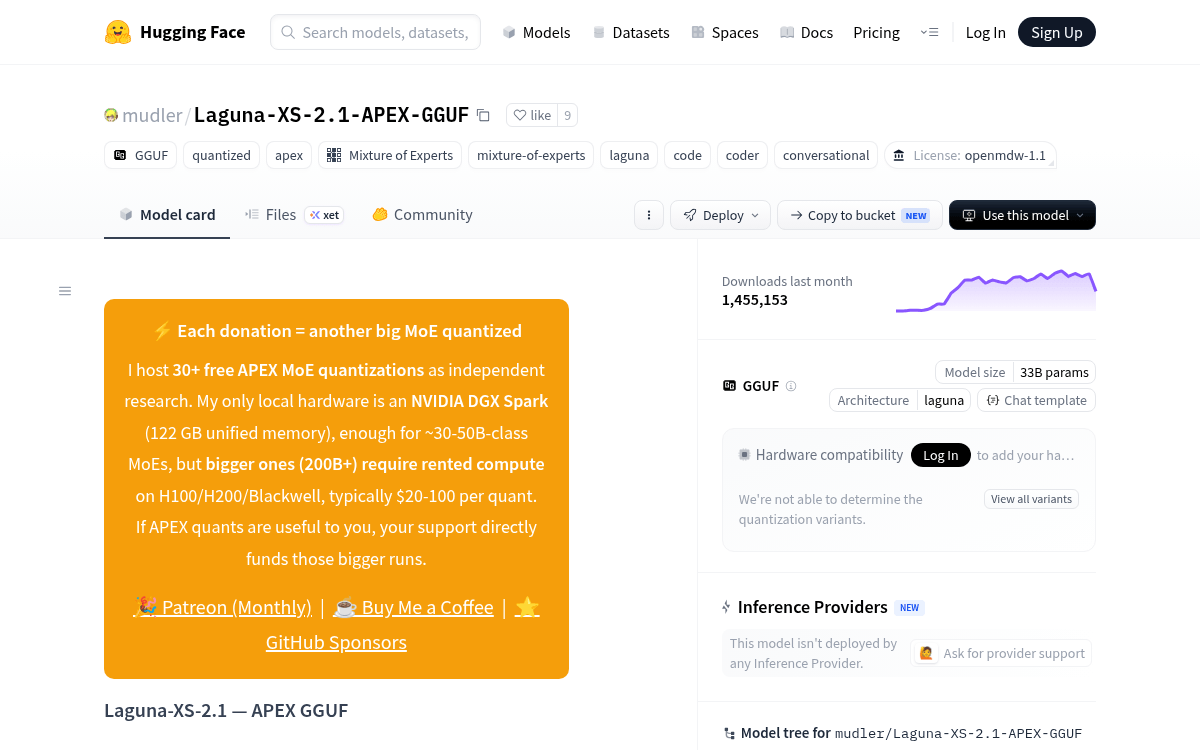
Poolside's Laguna-XS-2.1 Hits 1.4M Downloads With Half-Size APEX Compression
A community-quantized build of Poolside's 33B coding MoE hits 1.4M downloads, using a MoE-aware compression scheme that beats Q8 at half the size.
Takeaways
- Laguna-XS-2.1-APEX-GGUF hit 1.4M+ downloads, quantizing Poolside's 33B/3B-active coding MoE.
- Uses APEX, a MoE-aware method that matches Q8_0 quality at 38% less size.
- Ships 7 tiers from Mini (fits 16 GB GPUs) up to I-Quality for max fidelity.
- Base Laguna XS 2.1 scores 63.1% on SWE-bench Multilingual, 256K context.
- Runs on stock llama.cpp, Ollama, LM Studio, LocalAI, Docker Model Runner.
- Requires recent llama.cpp with Laguna arch support (PR #25165); OpenMDW-1.1 licensed.
A GGUF quantization of Poolside's Laguna-XS-2.1 coding model has quietly become one of the most-downloaded packages on Hugging Face, racking up more than 1.4 million pulls. What's drawing attention is the compression technique used to shrink it: APEX, a Mixture-of-Experts aware method that claims to match Q8_0 quality at roughly half the size.
The Laguna-XS-2.1-APEX-GGUF repo, maintained by LocalAI's Ettore Di Giacinto, packages seven quant tiers of the base model so you can pick a tradeoff that fits your hardware, from a highest-quality build down to a Mini variant tuned for consumer 16 GB GPUs.
The model underneath
Laguna XS 2.1 is Poolside's small open-weight coder: a 33B total parameter Mixture-of-Experts model with 3B activated parameters per token, designed for agentic coding and long-horizon work on a local machine. It shares the same architecture as XS.2, with a notable jump on SWE-bench Multilingual and stronger performance on terminal-style tasks. It fits on a Mac with 36 GB of RAM and ships under OpenMDW-1.1, which is permissive for commercial use.
The architecture is unusual enough to matter for anyone wiring it into an inference stack:
- 40 layers total: 1 leading dense FFN, then 39 MoE layers
- 256 routed experts plus 1 shared expert per MoE layer, with 8 experts active per token and sigmoid gating
- 48 attention heads / 8 KV heads, with a per-layer output gate and hybrid full plus sliding-window attention
- YaRN rope scaling with a 256K context window
- Native interleaved reasoning between tool calls
On benchmarks, XS 2.1's biggest gain over XS.2 shows up on SWE-bench Multilingual, up 5.4 points to 63.1%. For a 3B-active model, that puts it in genuinely useful territory for real code work rather than toy demos.