
Pro
DeepSeek's DSpark Makes V4-Flash Run 85% Faster for Everyone
DeepSeek open-sources DSpark, a speculative decoding module that makes DeepSeek-V4-Flash up to 85% faster per user with zero quality loss
20 stories
DeepSeek open-sources DSpark, a speculative decoding module that makes DeepSeek-V4-Flash up to 85% faster per user with zero quality loss
pdf-craft turns scanned book PDFs into clean Markdown or EPUB files entirely offline, powered by DeepSeek OCR running locally on your GPU
The Newton physics engine, a Linux Foundation project built on NVIDIA Warp, has crossed 5,000 GitHub stars as a community-maintained robotics simulator.
Google AI Studio's new Design Variations button generates multiple UI layouts instantly, solving the hardest part of vibe coding: describing visual aesthetics
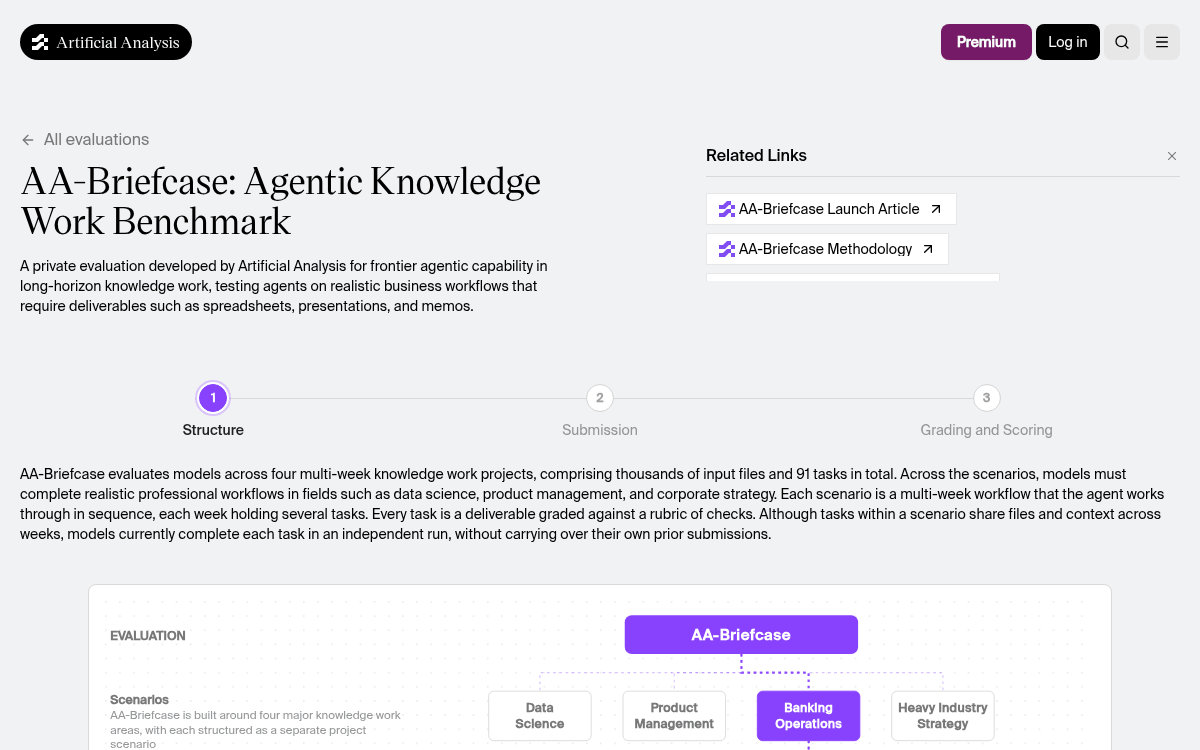
Artificial Analysis launches AA-Briefcase, a new agentic benchmark for long-horizon knowledge work, where NVIDIA's Nemotron 3 Ultra ranks among the top open models
NVIDIA RAPIDS RAFT v26.06 ships with a unified memory resource system, Randomized SVD, and CUDA 13.2 support — breaking changes included
Artificial Analysis launches Model Sets, letting users save and instantly apply custom model groups across all benchmark charts on the platform.
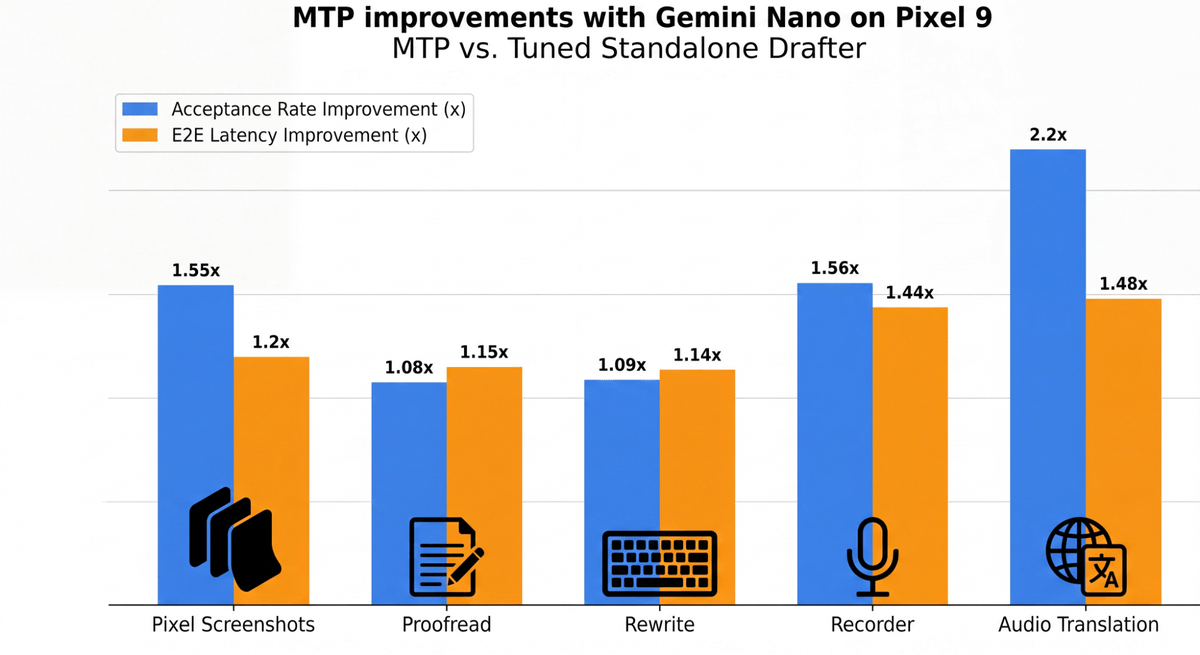
Google retrofits Multi-Token Prediction onto frozen Gemini Nano v3, delivering 50%+ faster on-device inference on Pixel 9 and 10 without touching the base model

Google Antigravity 2.0 gets a built-in guide skill, audio rendering, and smarter file search in its latest CLI and app update
NVIDIA's official NVFP4 checkpoint of GLM-5.2 is now live on vLLM, cutting memory ~1.8x vs FP8 while matching accuracy on Blackwell GPUs.
Microsoft's first in-house coding model ships inside GitHub Copilot, beating Claude Haiku 4.5 by 16 points on SWE-Bench Pro while using 60% fewer tokens
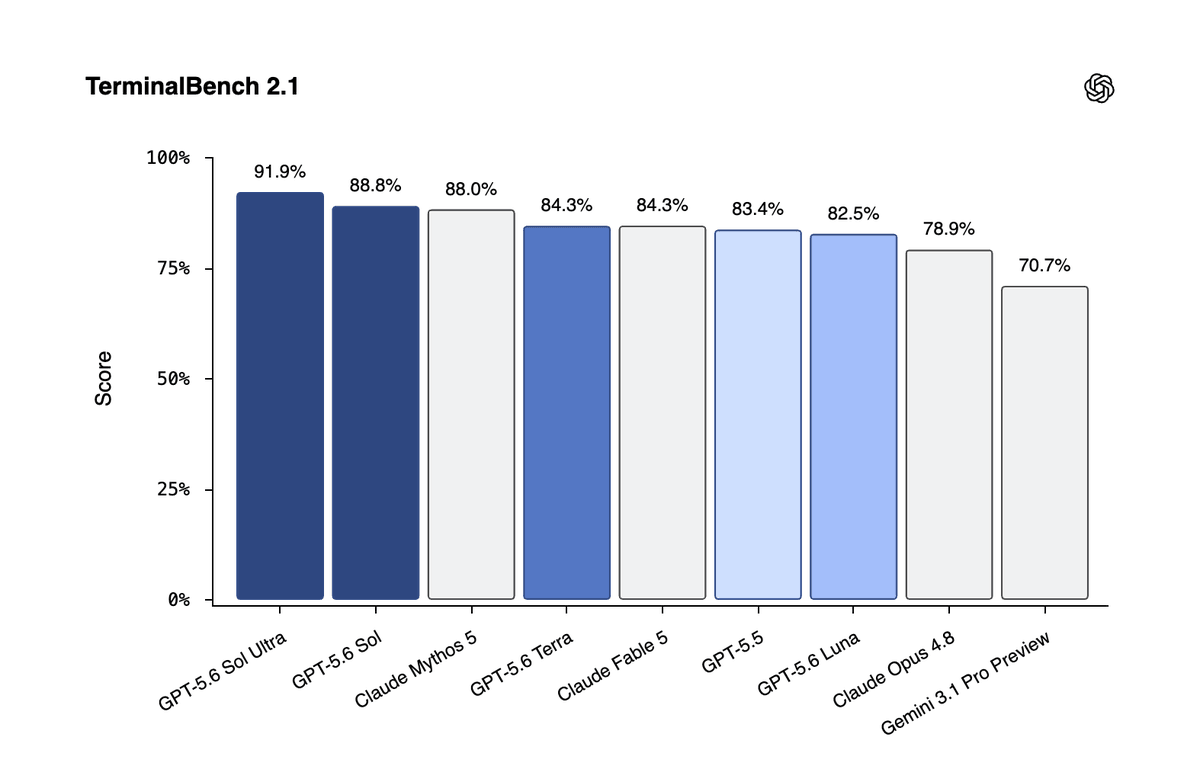
OpenAI's GPT-5.6 family launches in limited preview at US government request, with Sol setting new agentic coding and cybersecurity benchmarks at a new naming tier structure

Cerebras launches a global Ambassador Program to seed grassroots AI communities around its record-breaking inference platform, fresh off a blockbuster IPO.
Gemma 4 31B lands on Cerebras Inference at 1,500 tokens/sec — 15x faster than Claude Haiku — with a 24-hour hackathon kicking off this Sunday
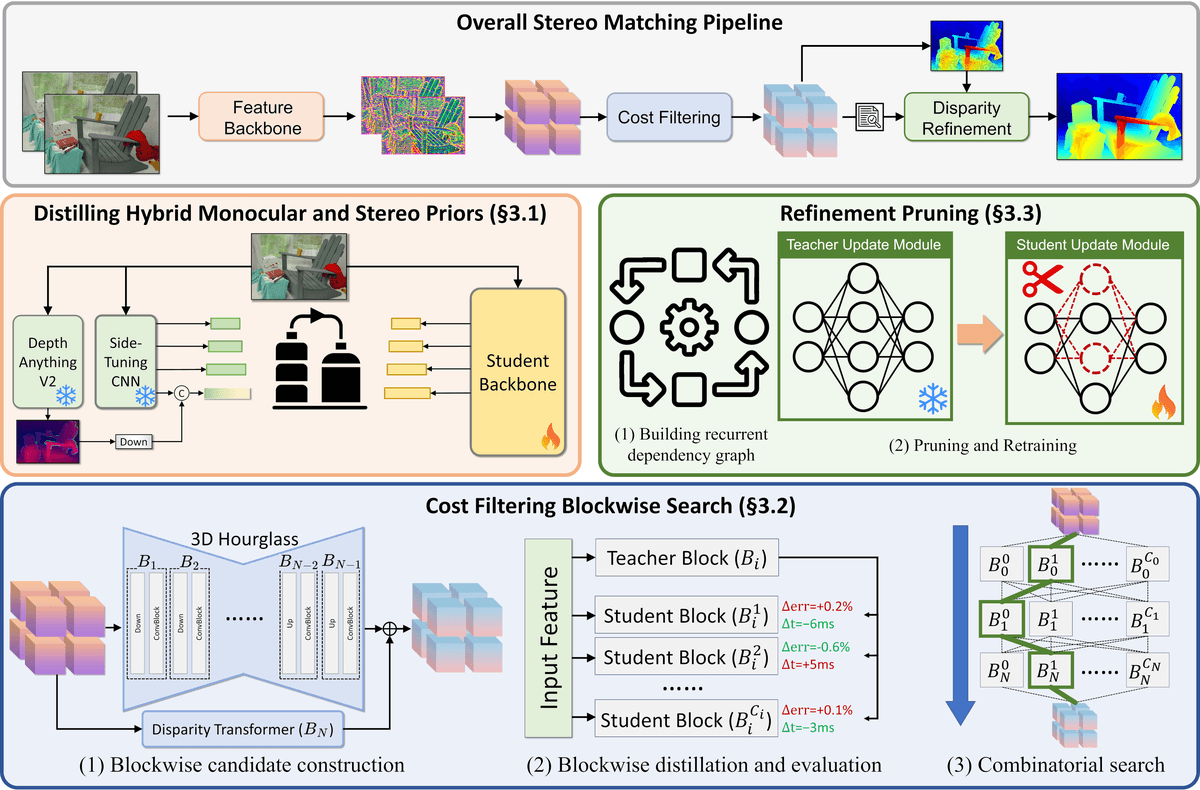
NVIDIA's Fast-FoundationStereo delivers zero-shot stereo depth estimation at real-time speeds with just 14.6M parameters, making foundation-model accuracy viable on edge hardware for the first time.
Hugging Face's TRL hits v1.0 with a formal stability contract, GRPO for reasoning models, vLLM integration, and Harbor for agentic training

Google's June Gemini Drops bring real-time image editing in Live, business profile management, Google Play app installs in-chat, and thinking levels for all users
Epoch AI's MirrorCode benchmark shows Claude Opus 4.7 can autonomously reimplement entire codebases, completing tasks estimated to take human engineers weeks
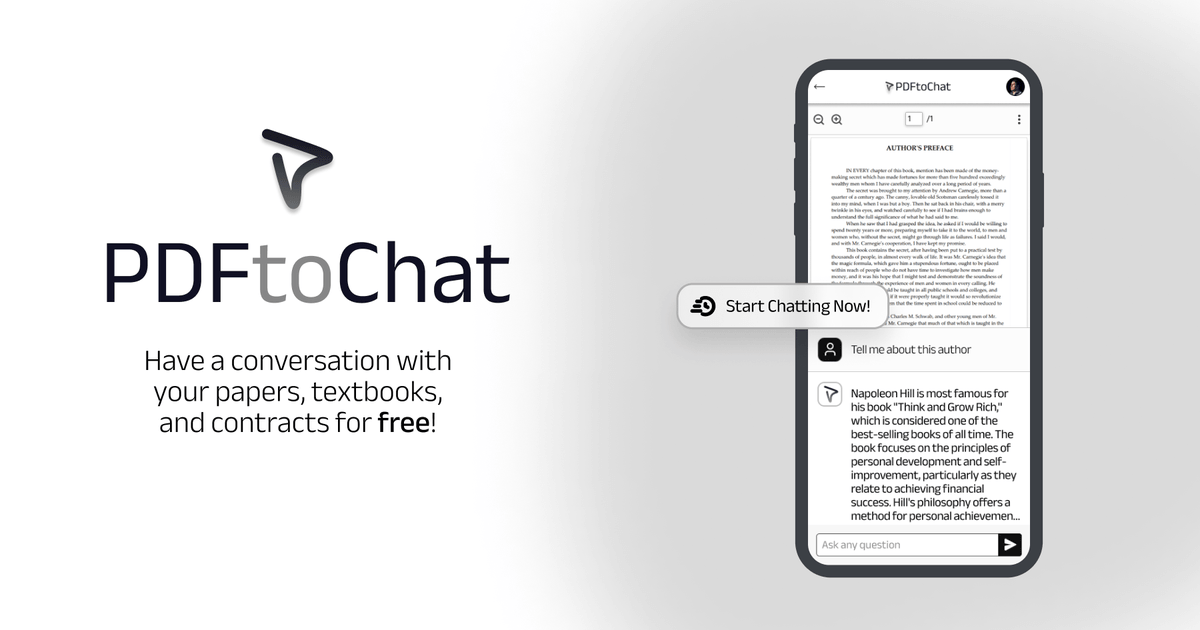
An open source Next.js template lets you build a hosted PDF chat app with hybrid vector search, no local embedding model required.
EvoSkill v1.3.0 adds Fireworks AI as a first-class inference provider, letting you run fully open-source self-improvement loops at high speed and low cost