LATESTEDITORIALLEADERBOARDTOPICS
AboutAdvertisePrivacy
LMSYS Org profile image

LMSYS Org

Open research collective (UC Berkeley, Stanford, CMU) focused on large model systems. Builds SGLang, a high-throughput inference engine for LLMs and VLMs with radix cache and chunked prefill; FastChat, an open platform for training, fine-tuning, and serving LLMs; Vicuna, a Llama-based open-source chat model; and S-LoRA for multi-adapter serving.
Last 12 months

Focus areas

INFRA•GPUS•LLMS•INFERENCE OPTIMIZATION•MODEL SERVING•QUANTIZATION

Links

Website•X

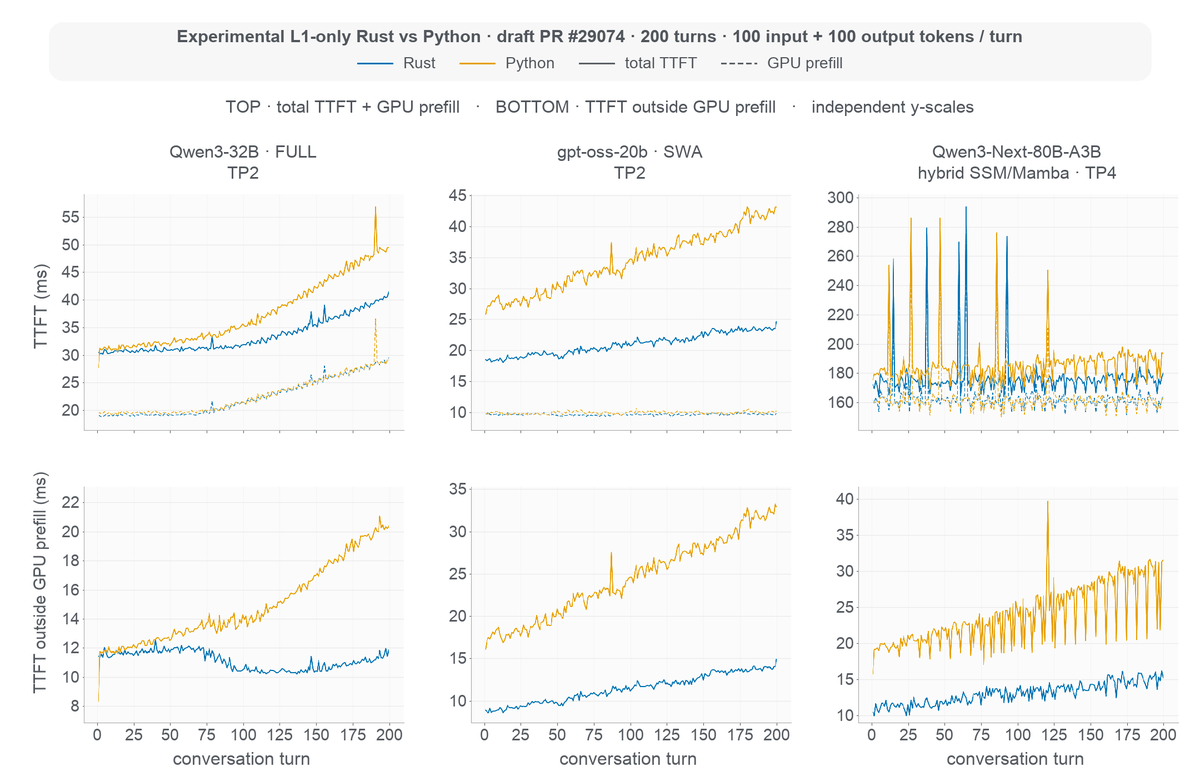
SGLang's HiCache Slashes AI Response Times by 60% Across Distributed Clusters

LMSYS OrgLMSYS Org·Infra
·7 days ago·

SGLang's Low-Latency Mode Boosts DeepSeek-V4.1-Flash Speed by 1.56x on AMD

LMSYS OrgLMSYS Org·Infra
·Oct 20·

SGLang Squeezes 78% More AI Throughput on NVIDIA's Blackwell GPUs

LMSYS OrgLMSYS Org·Infra
·Sep 21·

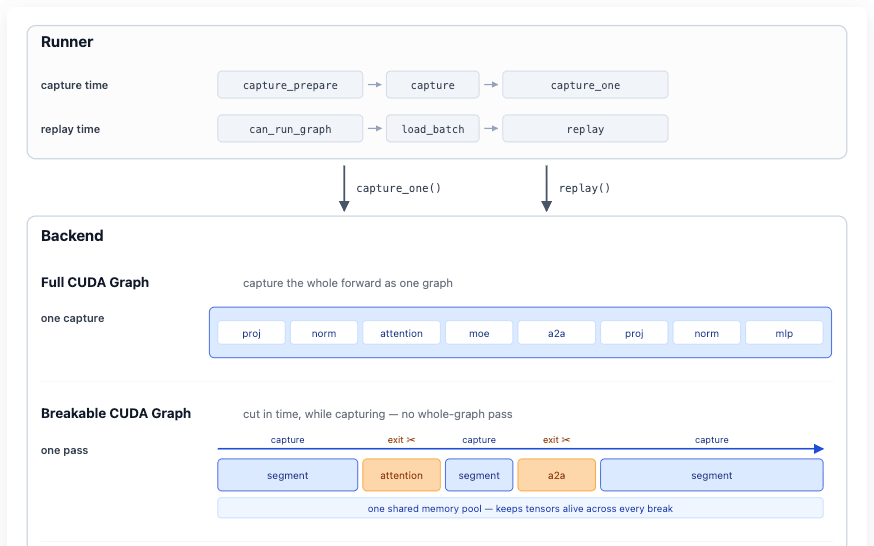
SGLang and Meta Cut LLM Prefill Time 1.7x With Breakable CUDA Graph

LMSYS OrgLMSYS Org·Infra
·Aug 17·

LMSYS Rebuilds SGLang's Cache to Finally Support Hybrid AI Models

LMSYS OrgLMSYS Org·Infra
·Aug 11·

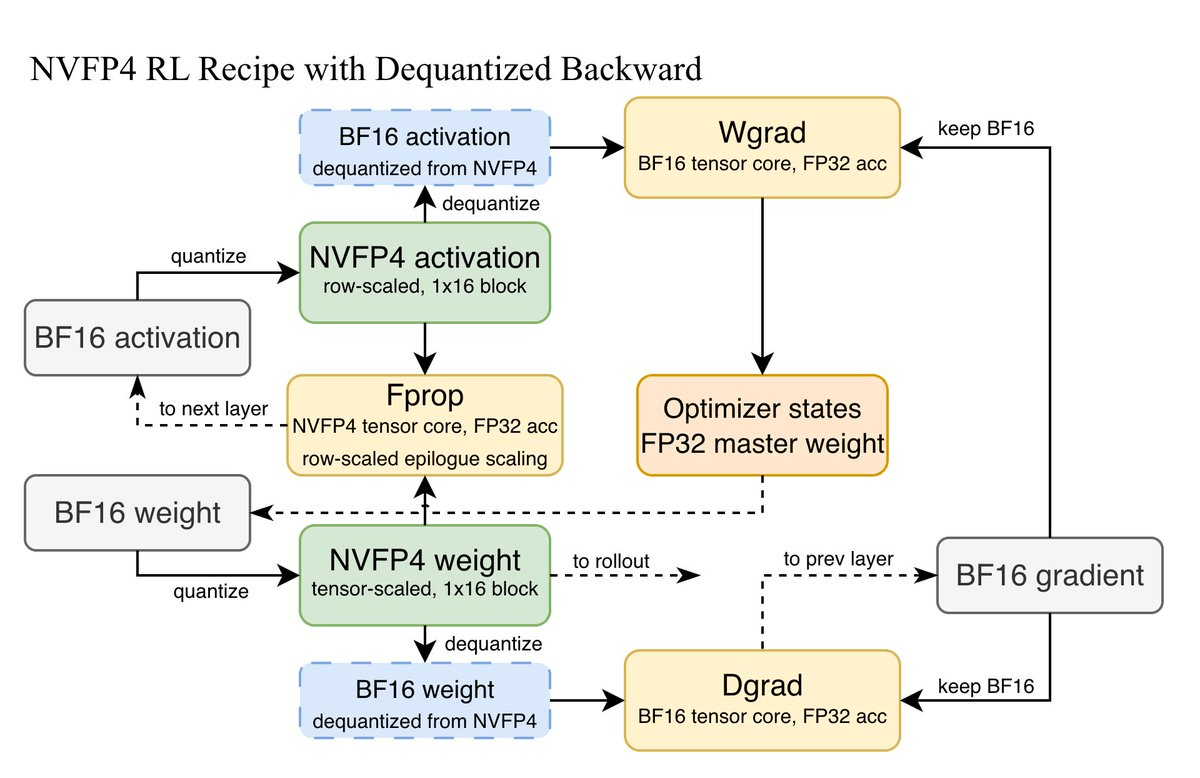
LMSYS Drops Miles, an Open-Source RL Framework Running 4x Faster on Blackwell GPUs

LMSYS OrgLMSYS Org·Training Infra
·Jul 29·

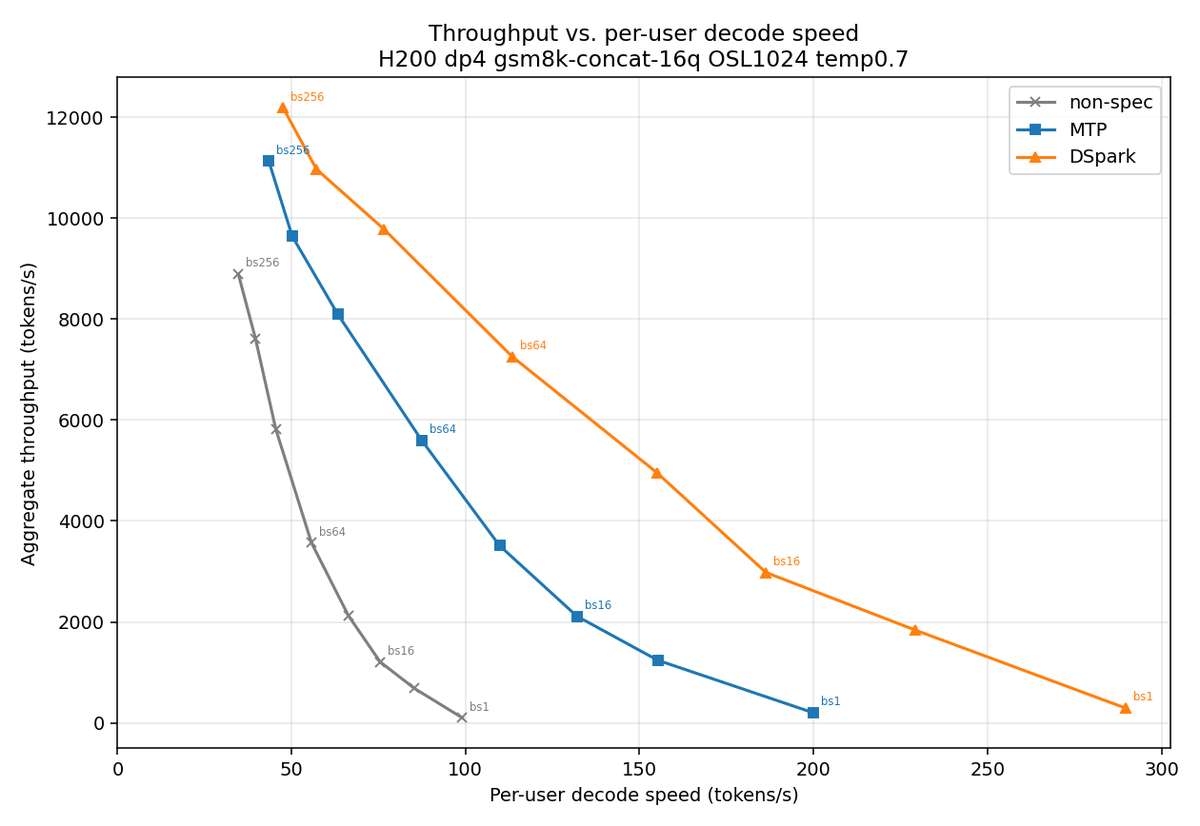
DeepSeek's DSpark Makes DeepSeek-V4 Generation 85% Faster at Any Scale

LMSYS OrgLMSYS Org·Infra
·Jul 06·

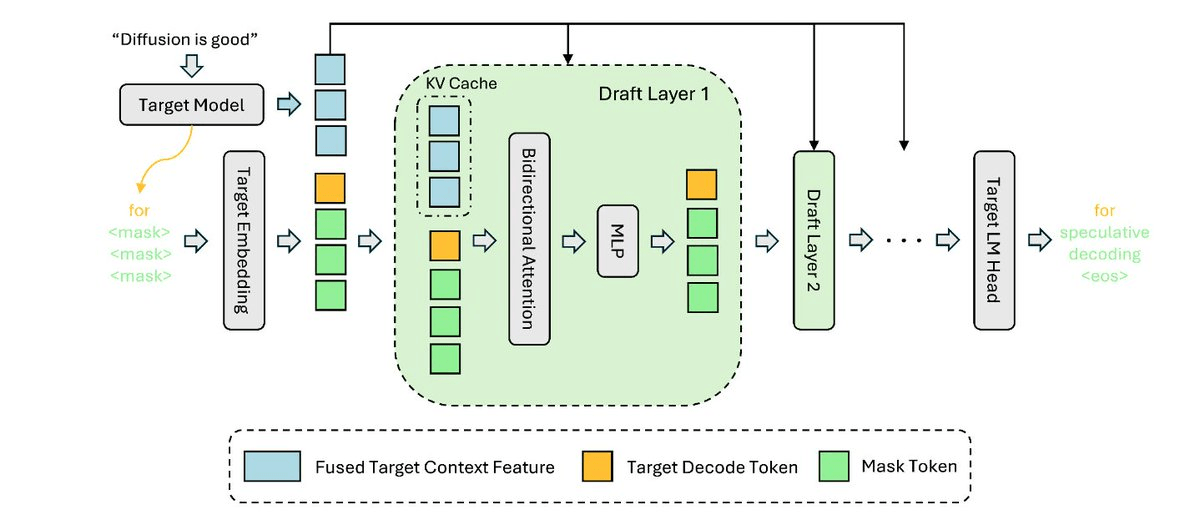
Z Lab's DFlash Hits 4.3x Throughput by Drafting Tokens in Parallel

LMSYS OrgLMSYS Org·Infra
·Jun 15·

SGLang Breaks 12,000 Tokens per Second on DeepSeek V4 Pro

LMSYS OrgLMSYS Org·Infra
·Jun 12·

LMSYS's Miles Framework Fixes the Silent Bug Wasting 10x AI Training Compute

LMSYS OrgLMSYS Org·Post Training
·Jun 09·

AI moves faster than any field in history. AlphaSignal tracks every paper, repo, model, and release in real time—organized, searchable, and tuned to your work.

Product

LatestEditorialLeaderboardTopicsArchive

Resources

NewsletterAdvertiseGet ListedEnterprise

Company

AboutEditorial TeamTermsPrivacy

© 2026 AlphaSignal