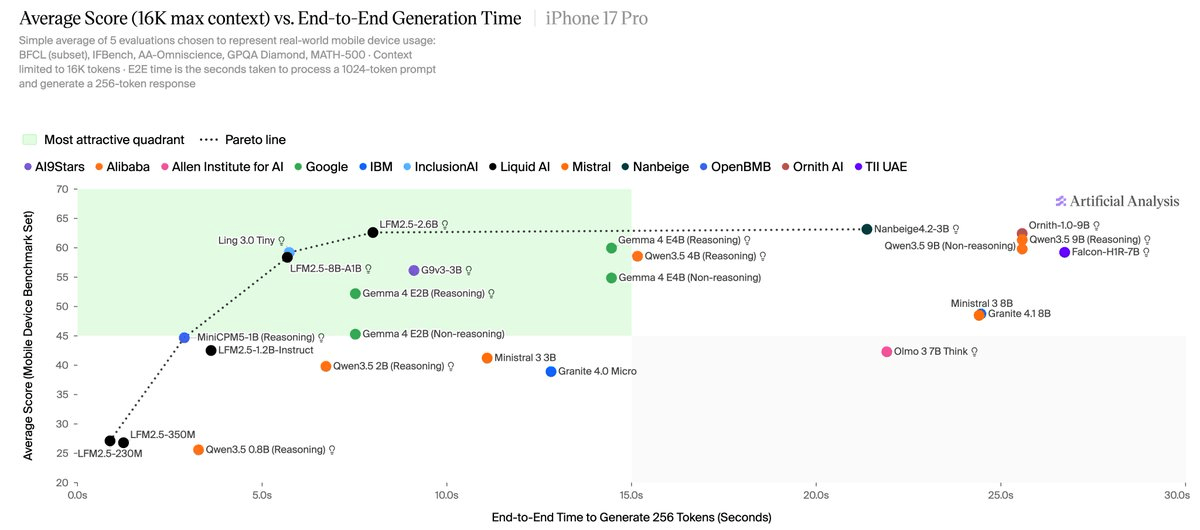
Artificial Analysis and Liquid AI launched a joint benchmark measuring how quantized small models actually perform on iPhone 17 Pro and Galaxy S26 Ultra.
Liquid AI and Artificial Analysis release an open-source suite that measures model quality, speed, latency, and memory across real phones, laptops, and embedded hardware.
A compact 4B open-source model with hybrid sliding-window attention, native 1M-token context, and agent-focused benchmarks that top comparable small models.
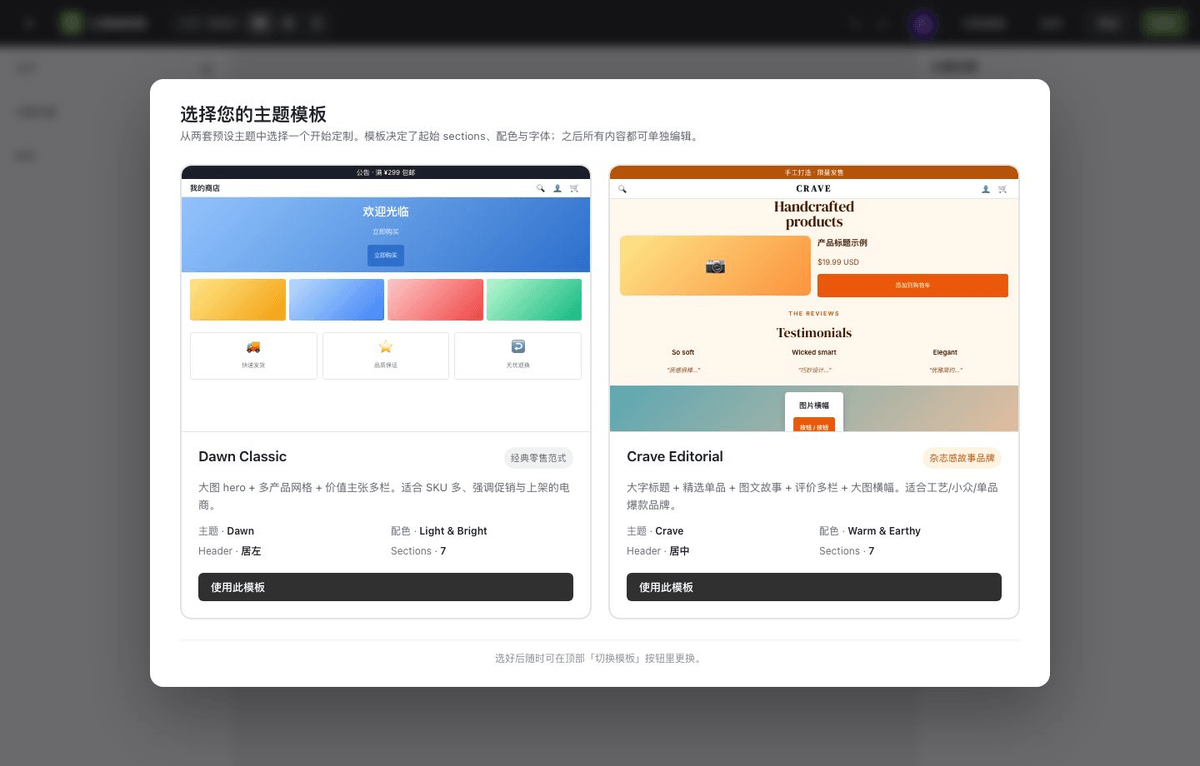
Alibaba's Accio team open sourced a 107-task benchmark that forces agents to complete real e-commerce workflows inside stateful replicas of Shopify, Gmail, Stripe and more.
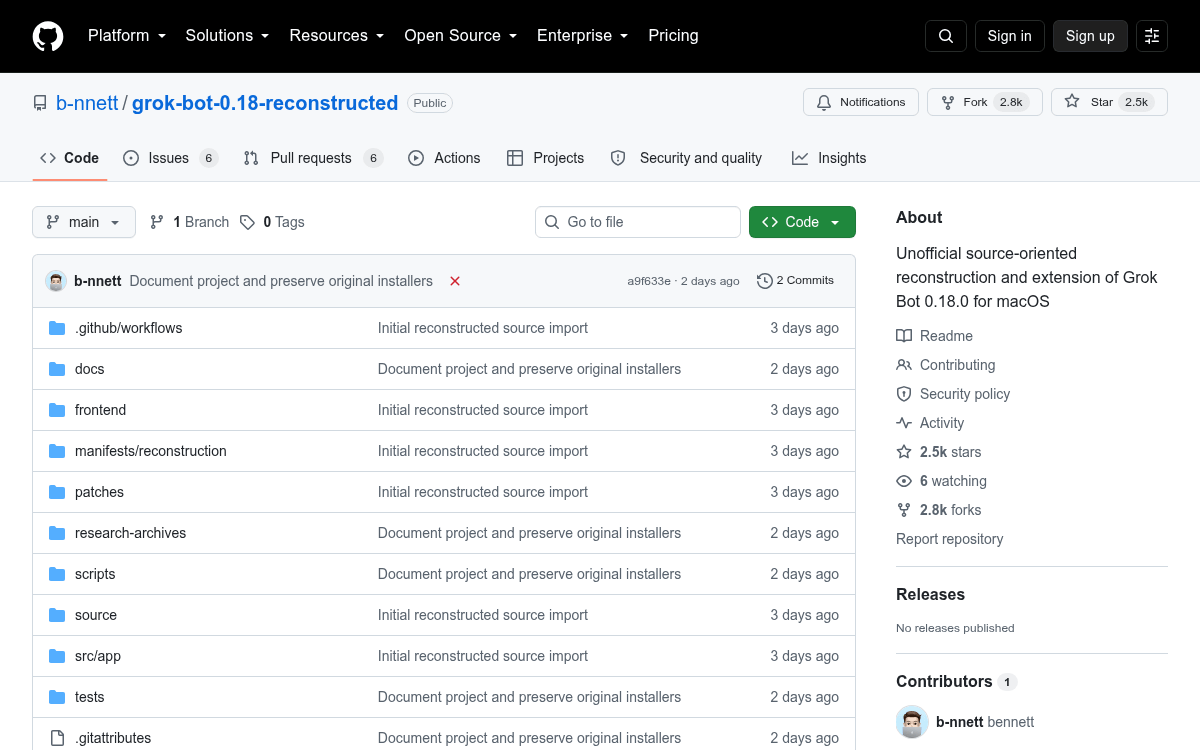
A weekend reverse-engineering project turns a compiled macOS app into 440K lines of readable TypeScript, then bolts on a four-provider inference router.
GitHub added a three-day default cooldown on Dependabot version update pull requests, aiming to filter out short-lived poisoned package releases before they land in your repo.
A community quantization pairs a 27B Qwen model with multi-token prediction and AMD's IU4 matrix path, hitting ~49 tokens per second on a single Strix Halo APU.
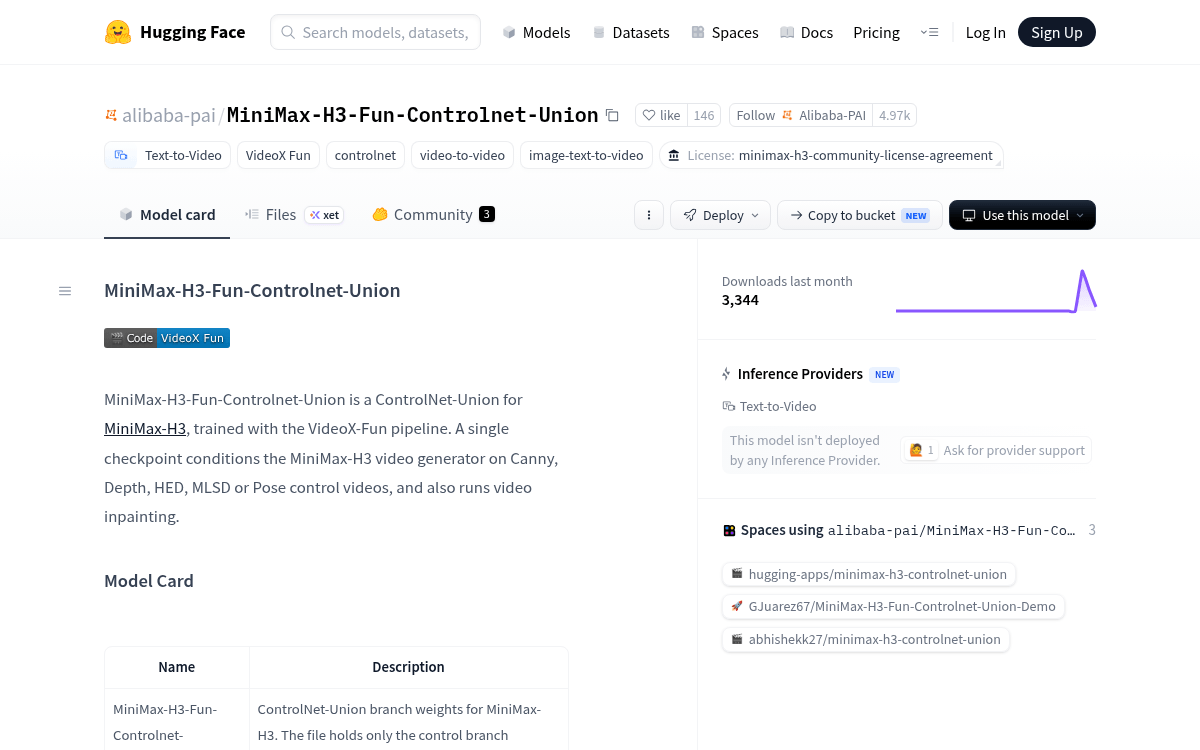
A community-made checkpoint grafts Z-Image's texture attention onto MiniMax H3's video engine, giving richer surfaces without retraining or extra VRAM.
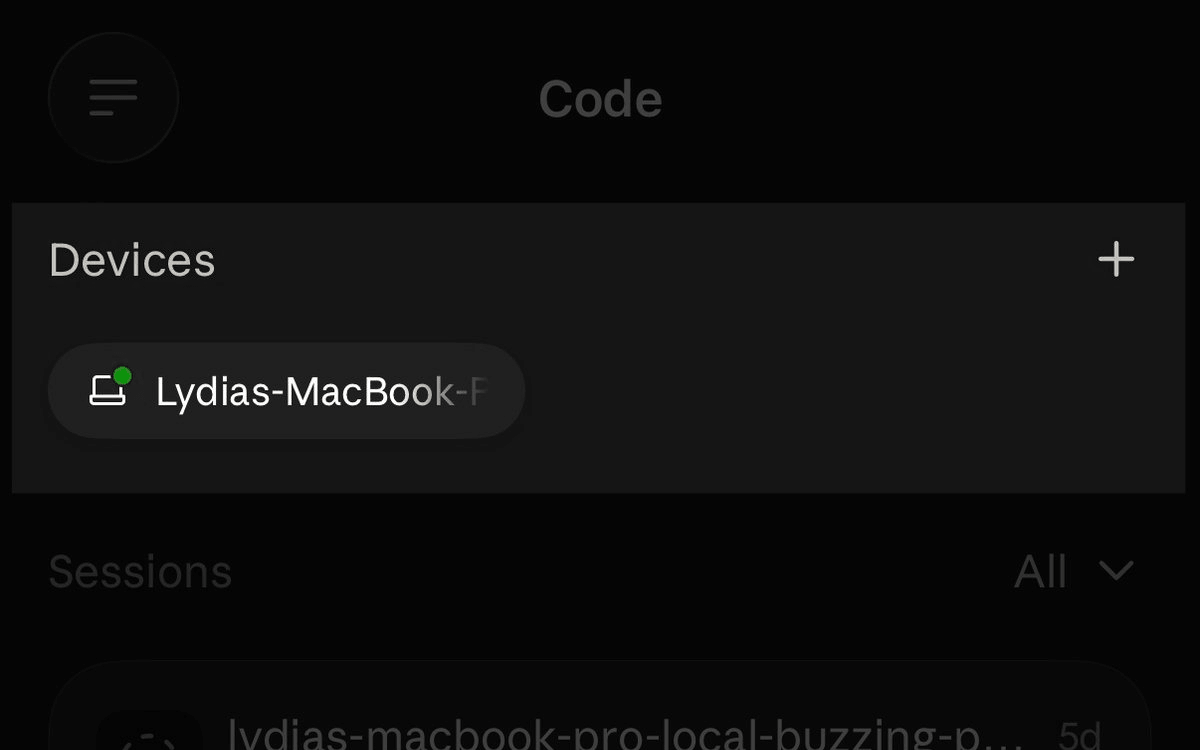
Anthropic ships reliability fixes to Claude Code Remote Control, adds auto-reconnect, tighter phone-CLI sync, and the ability to launch sessions from your phone.
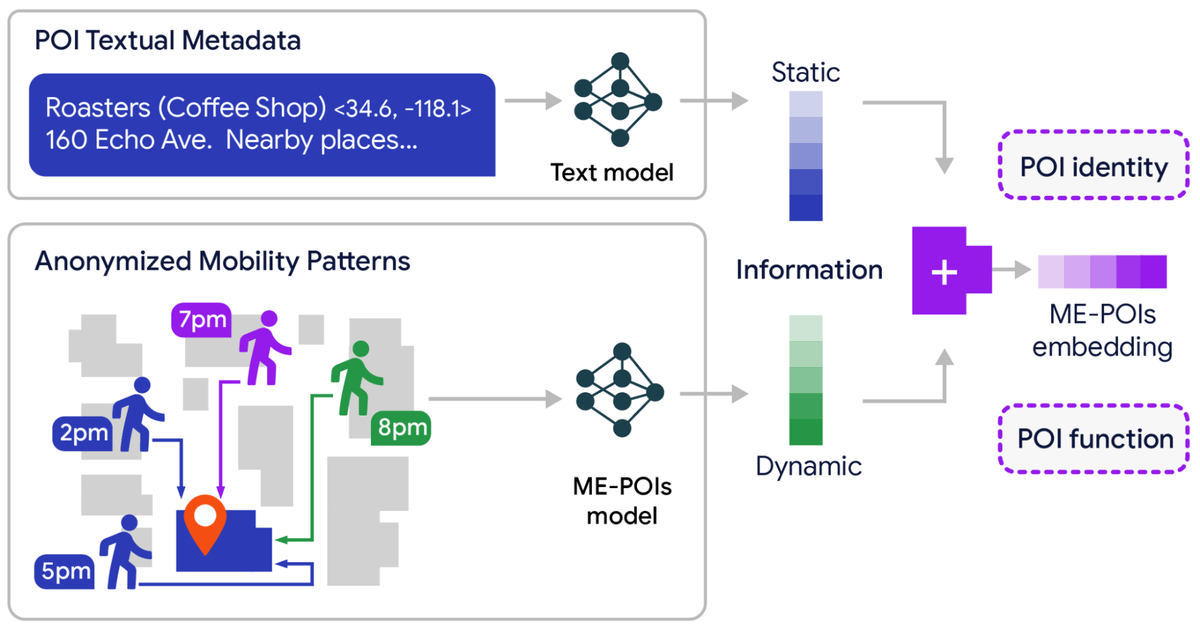
Google Research unveils ME-POIs, a framework that fuses anonymized foot-traffic patterns with text embeddings to improve place understanding by up to 81.9%.

 Pro
 Pro
 Pro
 Pro
 Pro
 Pro
 Pro
 Pro
 Pro