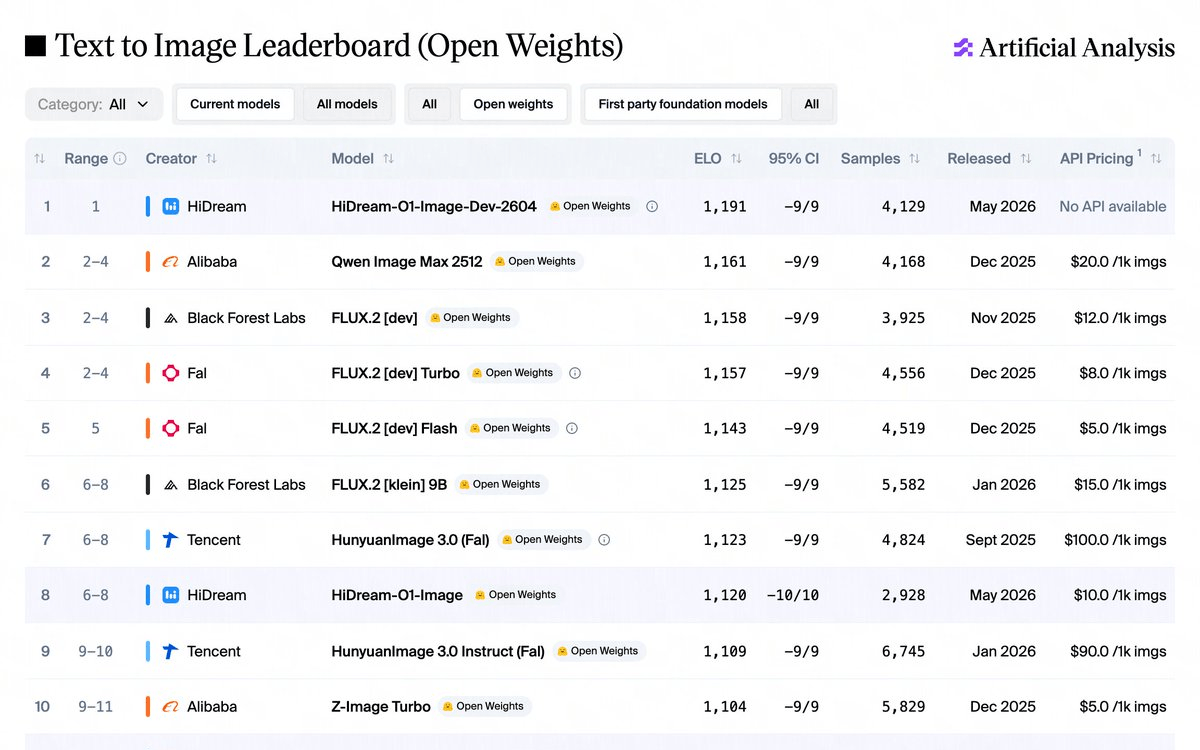
HiDream-O1-Image is an 8B open-weights model that ditches the VAE entirely, beating models 7x its size on key benchmarks while running three tasks from one checkpoint under MIT license.
GitHub Copilot's shift from flat-rate to token-based billing is live, and heavy users of agentic coding in Zed and other editors are already reporting 10x to 50x cost spikes.
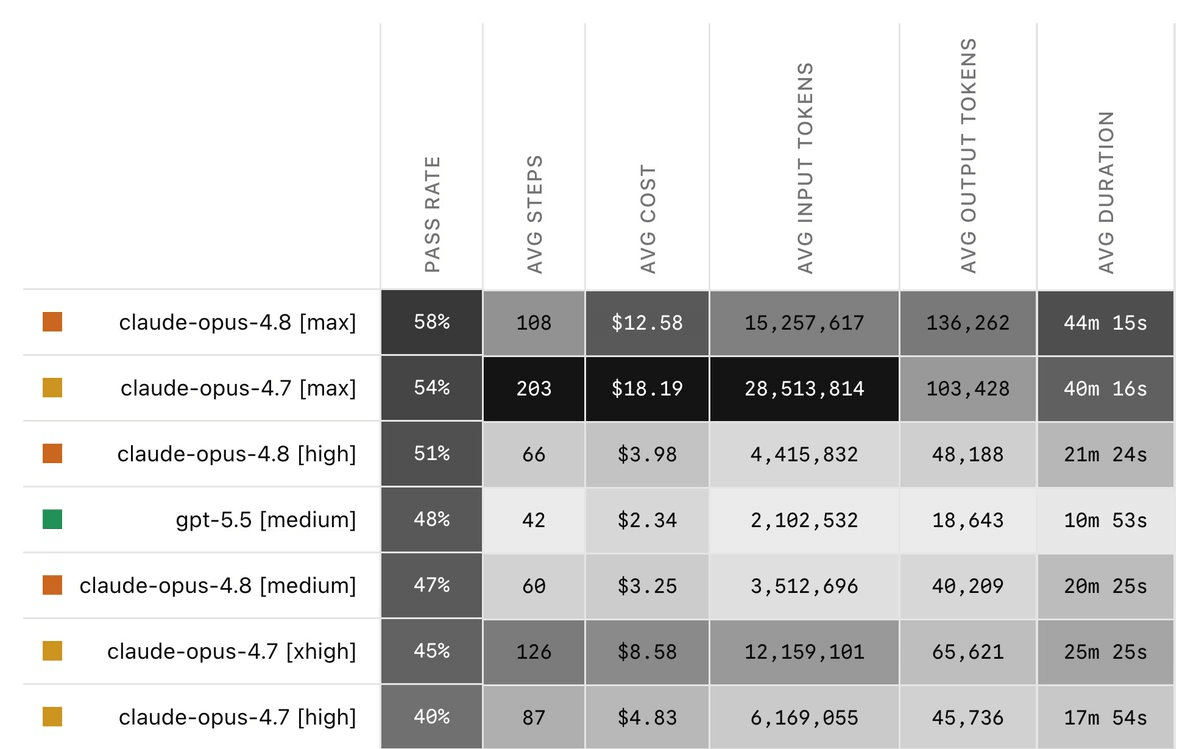
Datacurve adds Claude Opus 4.8 to DeepSWE, revealing a 6% accuracy gain over Opus 4.7 at lower cost — but GPT-5.5 still leads the leaderboard by 12 points
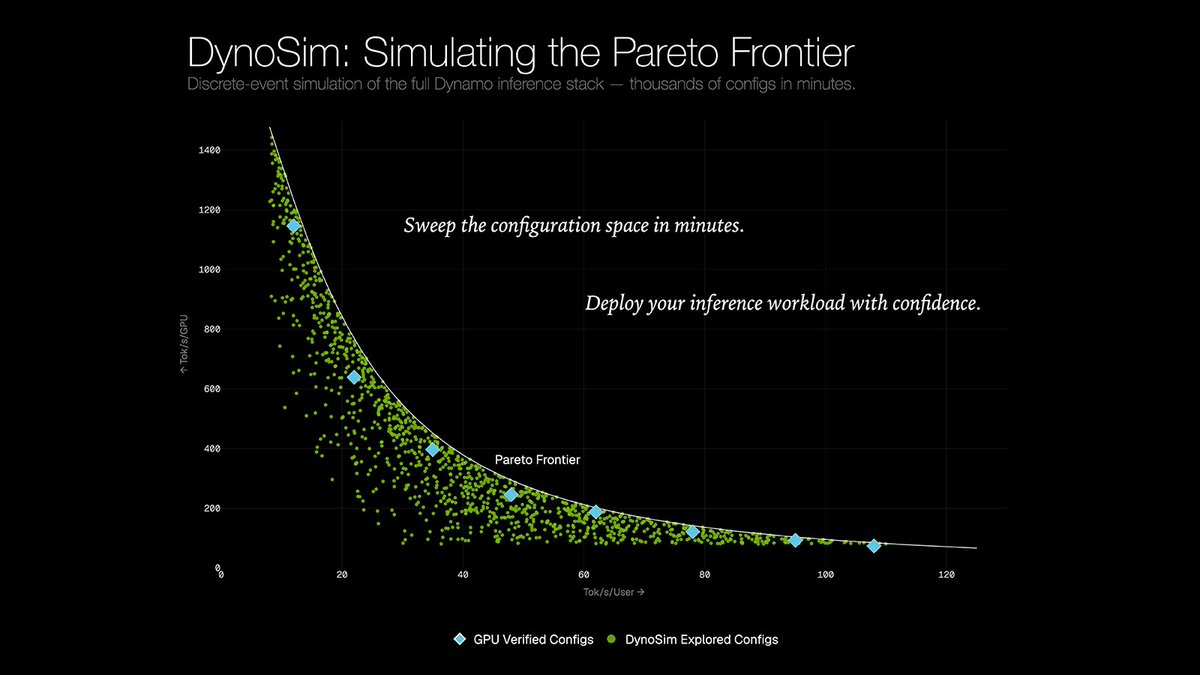
NVIDIA's DynoSim lets teams simulate thousands of LLM serving configurations at 1,500x real-time speed, cutting GPU validation costs before production deployment.
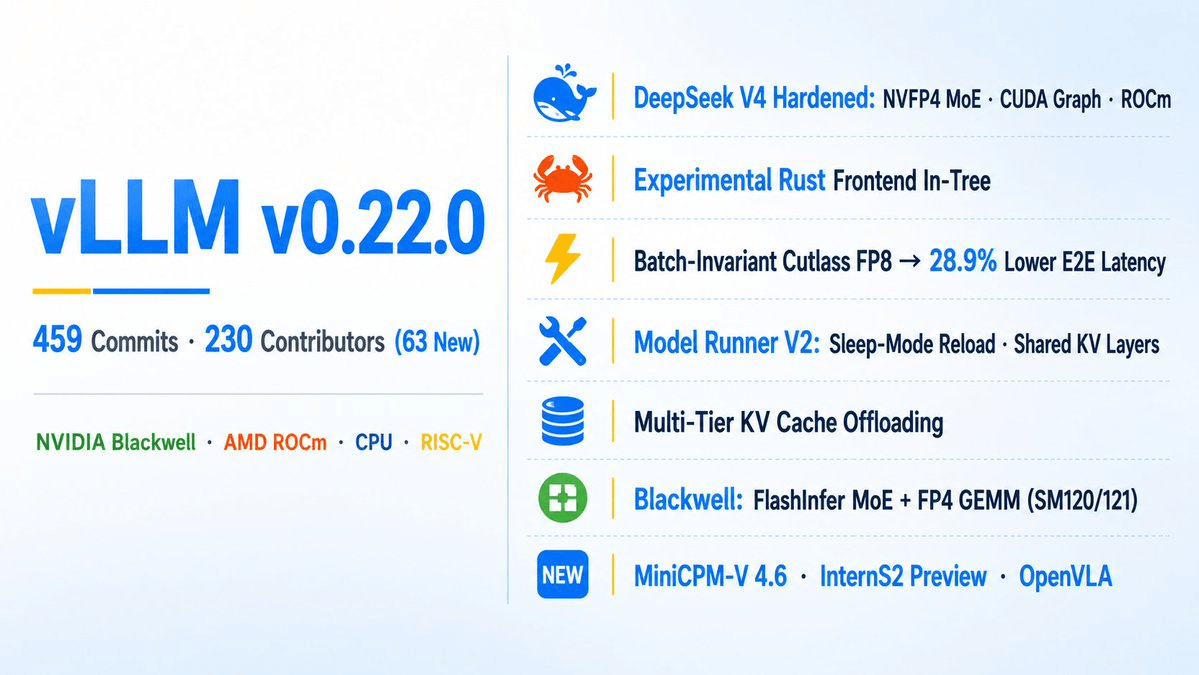
vLLM v0.22.0 lands a Rust frontend, 28.9% latency gains from batch-invariant FP8, and production-grade DeepSeek V4 support across NVIDIA, AMD, and CPU hardware
StepFun's 198B MoE vision-language model is now free on Nous Portal for 30 days, giving Hermes Agent users a powerful new backbone for coding, search, and multimodal workflows.
A 35B Mixture-of-Experts model squeezed into 4-bit floating point, shrinking memory roughly threefold while holding benchmark accuracy within a point of the original.
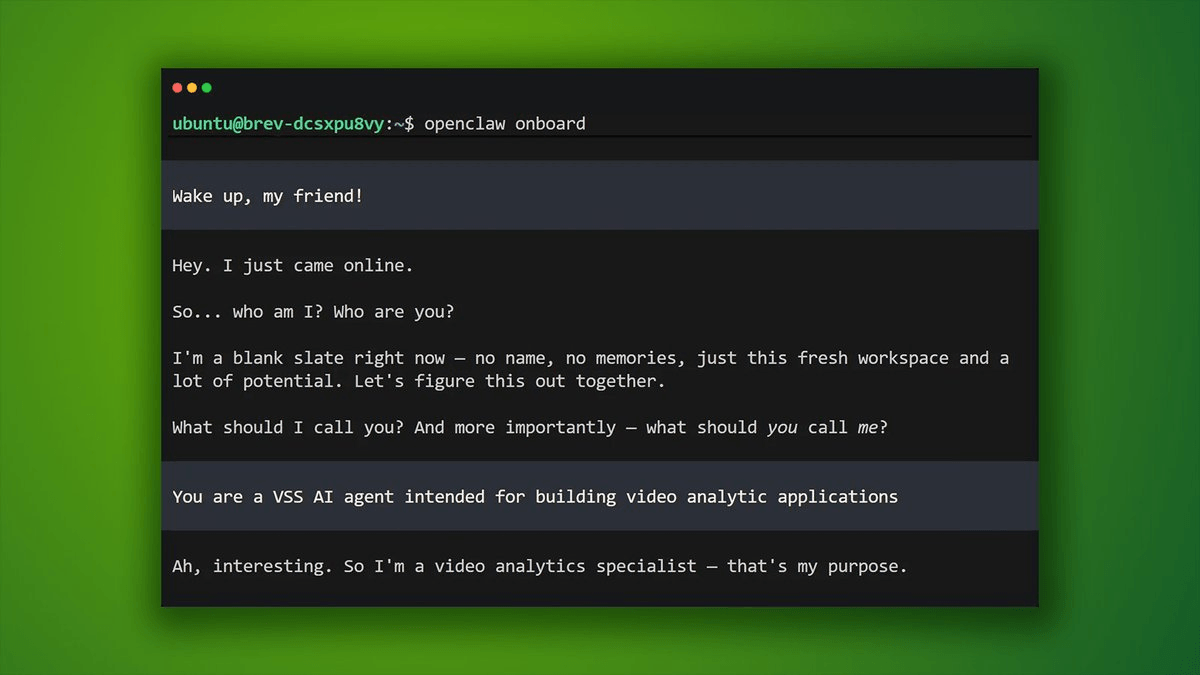
NVIDIA's VSS 3 lets coding agents deploy, configure, and query a full video analytics stack through plain-language chat, no microservice wiring required.
parakeet.cpp brings NVIDIA's best speech-to-text models to any CPU or GPU, with no Python, no PyTorch, and output identical to the original NeMo framework
Codex can now drive Windows desktop apps directly and accept commands from your phone, closing the gap with the macOS version released earlier this year.
Cohere's Command A+ is a 218B open-weight MoE model that beats Google Translate and outperforms closed models on multilingual benchmarks — all on just two H100s


 Pro
 Pro
 Pro