A new proposal to classify undecidable problems into three complete complexity classes, borrowing the NP-complete playbook to map what lies past the halting problem.
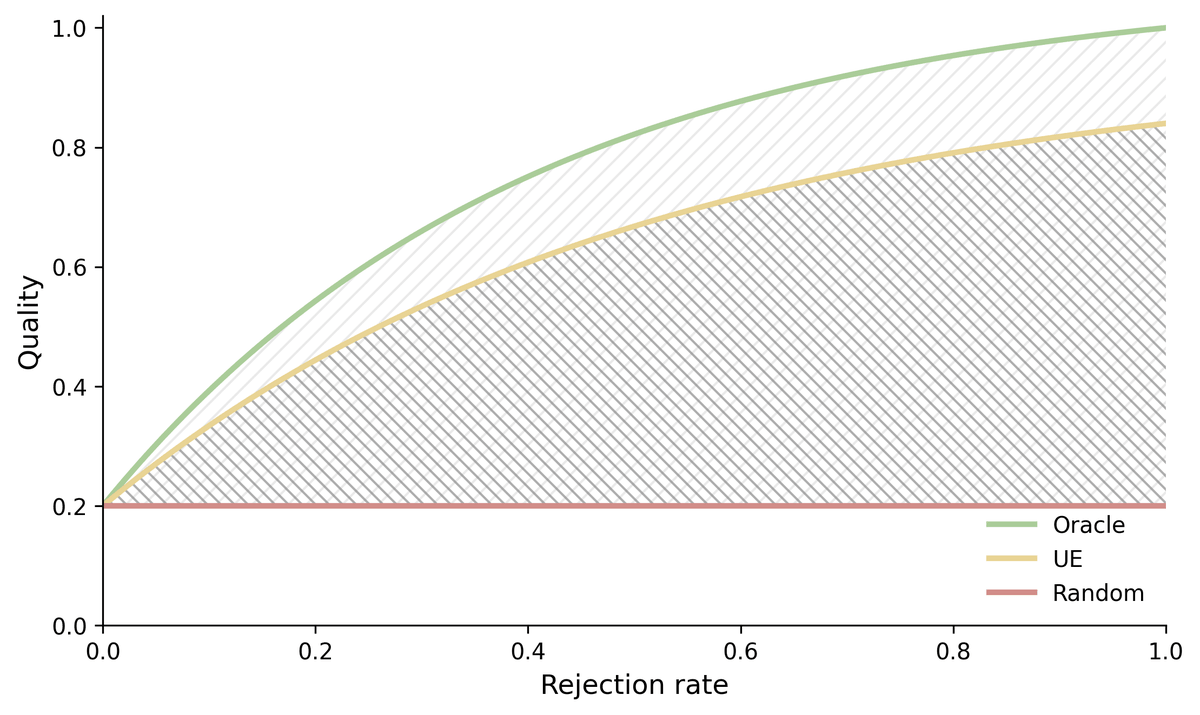
A new benchmark reveals confidence scores in LLMs break down when questions have multiple valid answers or ambiguous phrasing, exposing predictable failure modes.
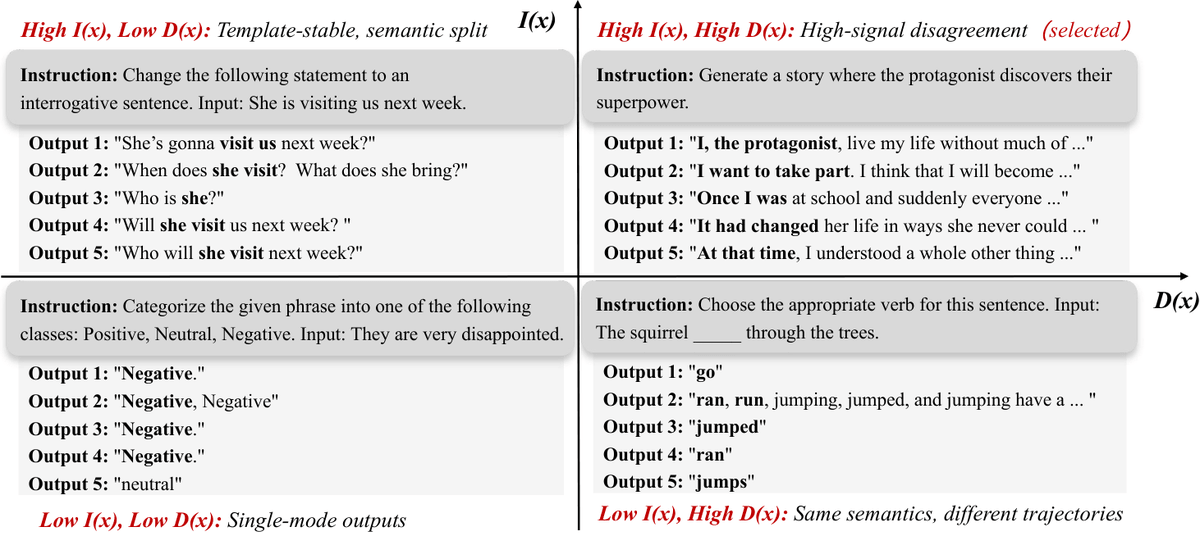
A new geometry-aware method scores instruction data by measuring how a model's own multi-sample answers spread in embedding space, beating strong selectors with just 10K examples.
A controlled study finds diffusion language models hallucinate more than autoregressive peers, with three unique failure modes tied to parallel decoding.
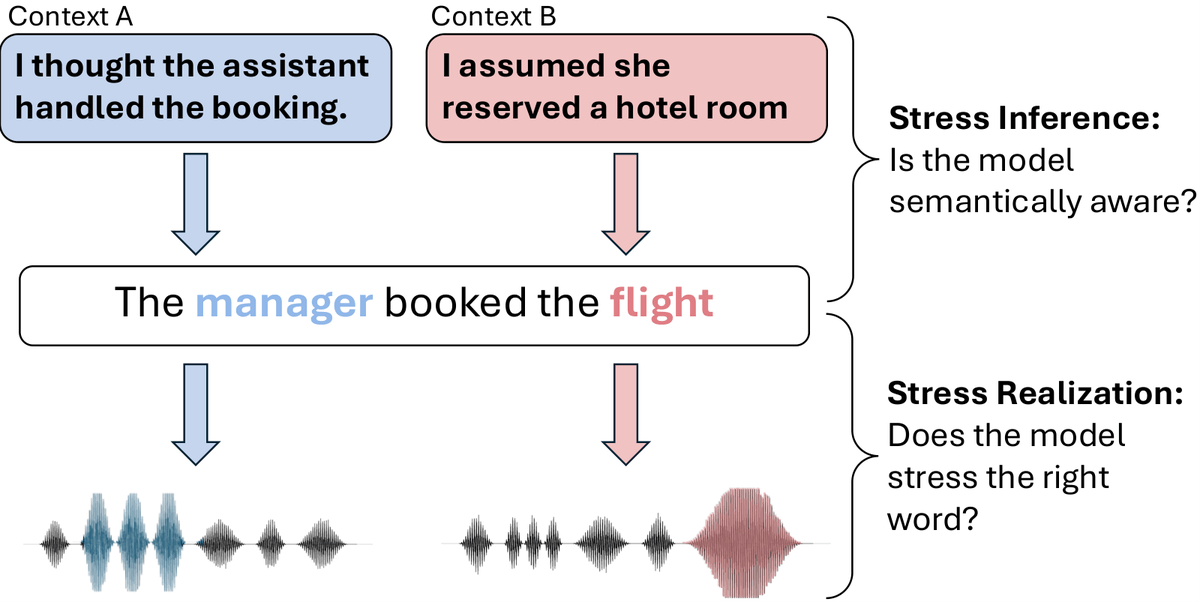
A new benchmark called CAST shows that state-of-the-art text-to-speech models fail to place emphasis on the right word based on conversational context.
A new study shows that important entities in text are locally harder to predict but make surrounding content more predictable, refining the Uniform Information Density theory.
A comprehensive taxonomy of over 90 deep learning methods for predicting human actions before they happen, with benchmark results across major datasets.
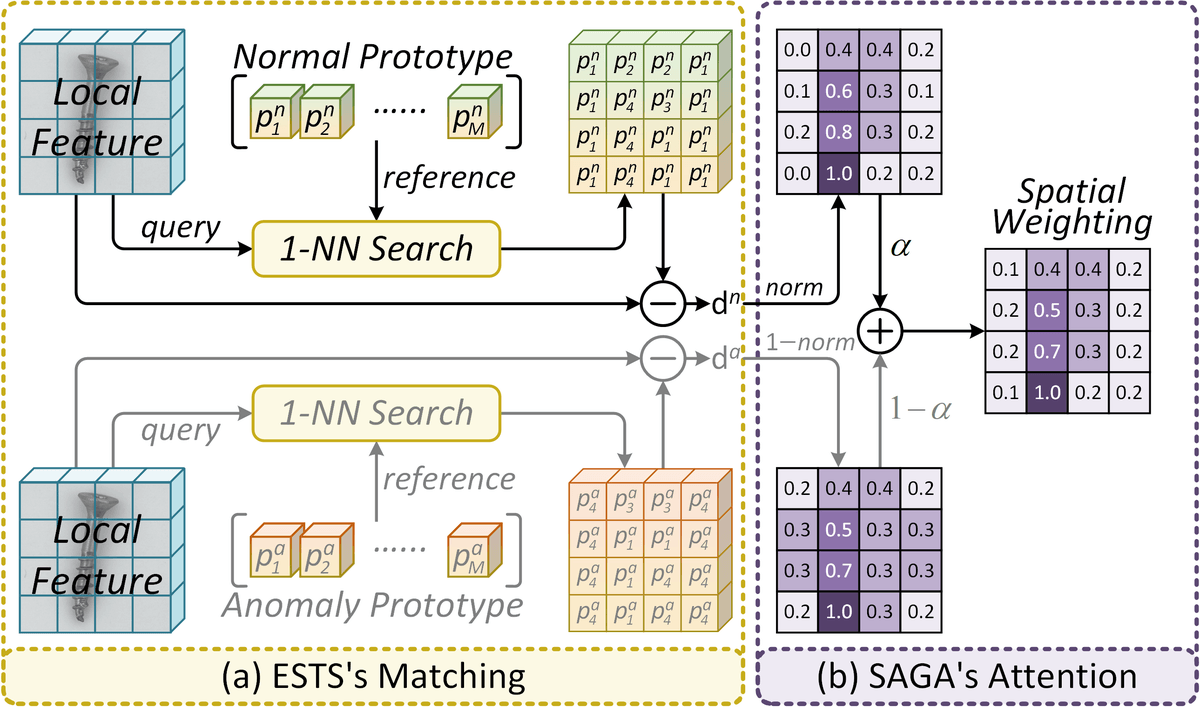
A new CLIP-based framework generates prompts on the fly from image features, beating zero-shot anomaly detection baselines by 1.4-1.9% AUROC across 13 datasets.
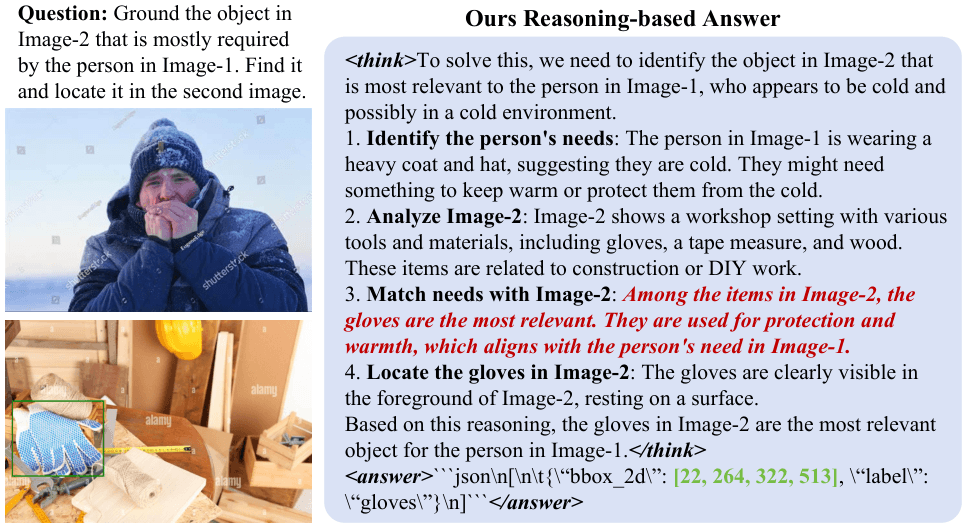
A two-stage recipe combining chain-of-thought fine-tuning with GRPO reinforcement learning pushes a 7B model past 72B baselines on cross-image grounding tasks.
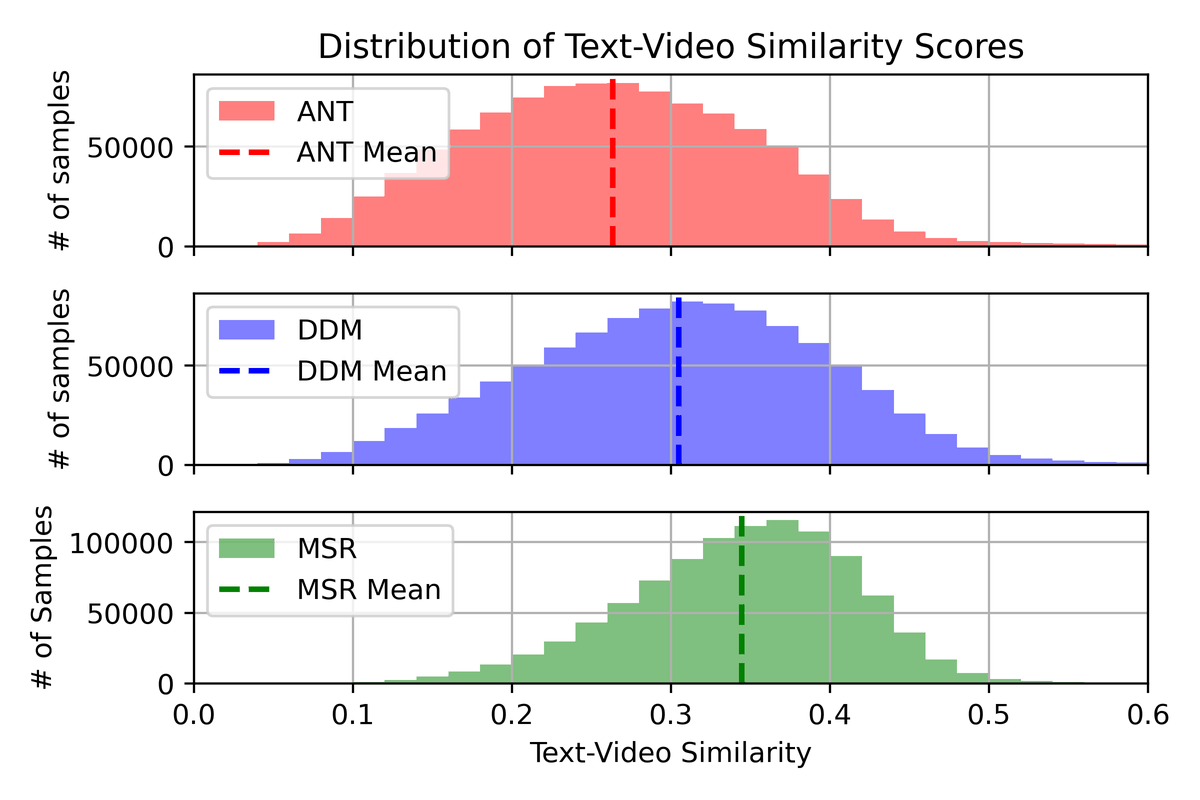
A new adversarial technique pushes attacker videos to the top of retrieval results across multiple queries at once, exposing a fresh vulnerability in text-to-video search.
A new fine-tuning recipe touches only batch norm and classifier layers to keep breast cancer models accurate when hospitals swap scanners and imaging protocols.
A new domain adaptation framework uses medical text descriptions like 'left atrium' to bridge the gap between CT and MRI segmentation models without target labels.
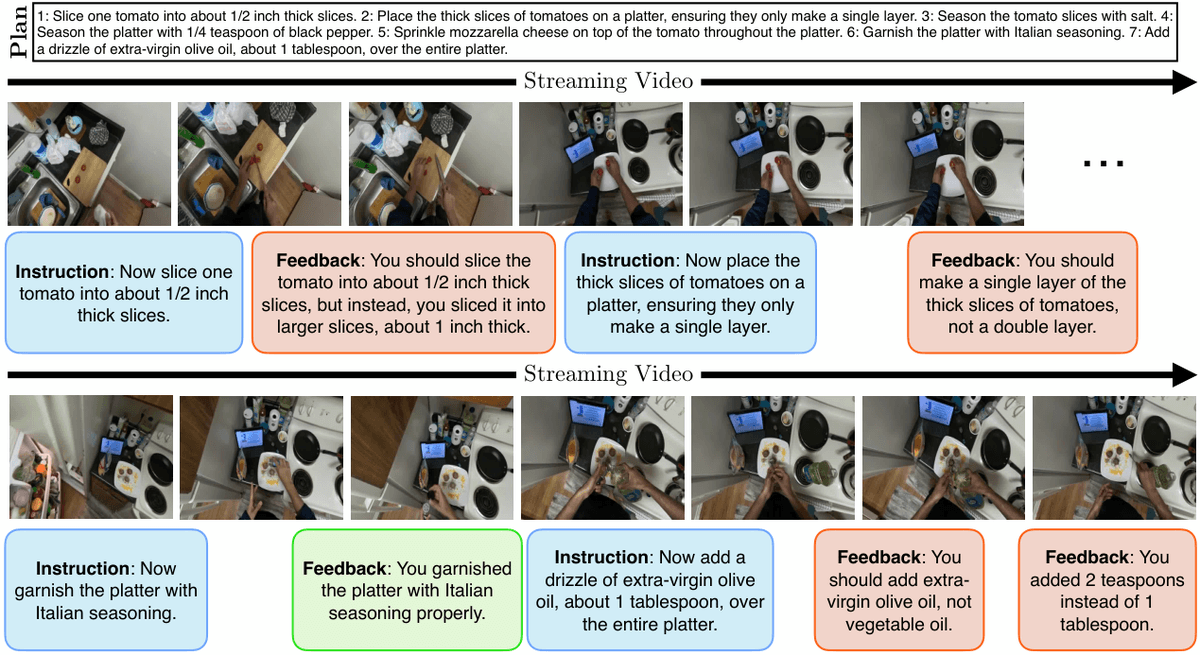
Qualcomm's new benchmark and streaming Mamba-based model tackle real-time cooking coaching, exposing where current multi-modal LLMs fail at watching users work.
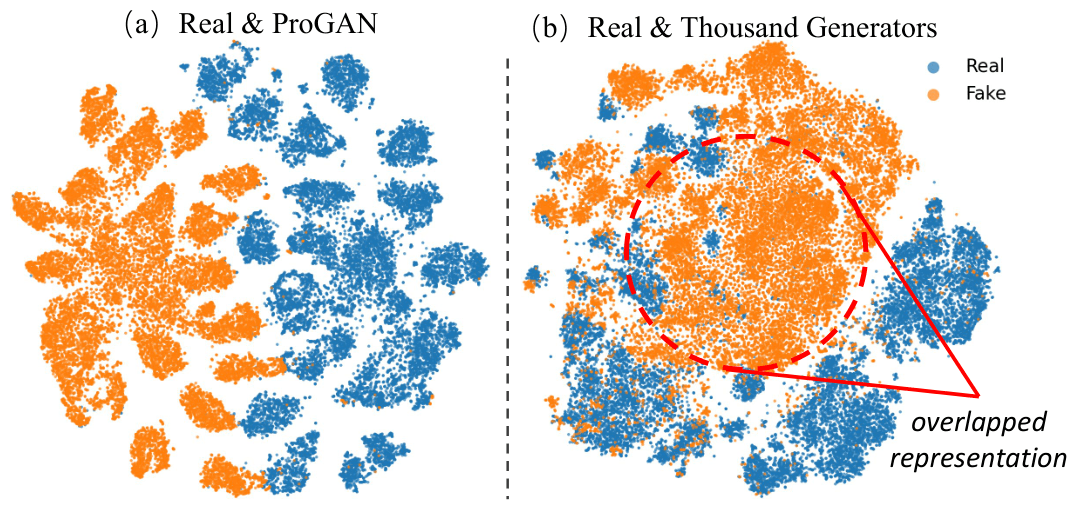
A CVPR 2026 paper shows that scaling AI-image detectors across thousands of generators backfires, and proposes a prototype-based fix that hits 90.4% accuracy.