
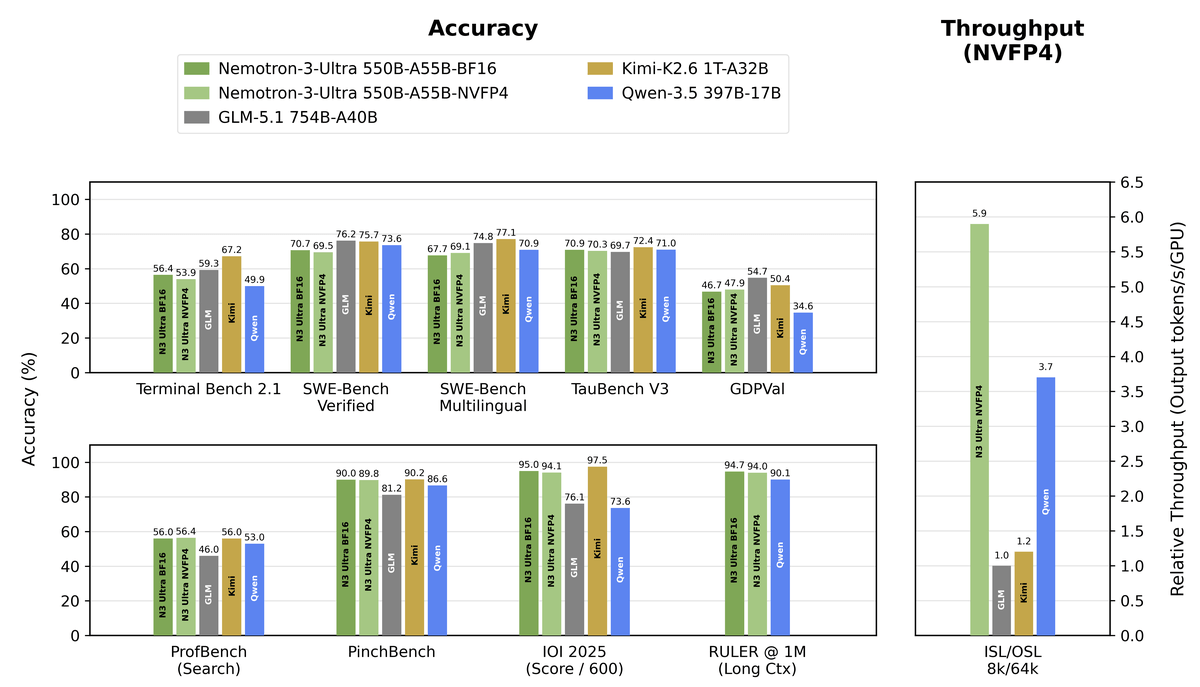
NVIDIA's Nemotron 3 Ultra Hits 6x Faster Inference With 550B Open Model
NVIDIA's 550B-parameter open model lands free on OpenCode, combining a 1M-token context window with up to 6x higher throughput than rival open LLMs
20 stories
NVIDIA's 550B-parameter open model lands free on OpenCode, combining a 1M-token context window with up to 6x higher throughput than rival open LLMs

Kaggle ported its benchmark authoring workflow out of the web notebook and into a CLI plus agent skill that runs in any IDE.
Anthropic's internal data shows Claude now writes 80% of its production code, with a coding speedup test jumping from 3x to 52x in twelve months.
OpenAI's new Dreaming V3 architecture quietly synthesizes context from past chats, doubles memory capacity for Plus and Pro, and reaches Free users next.
Microsoft's new speech-to-text model hits 2.4% word error rate on Artificial Analysis, transcribes an hour of audio in under 15 seconds, and supports 43 languages.
Arena ships Agent Mode and a causal-tracing leaderboard that ranks frontier models on real multi-step jobs, not curated prompts.
Warp's new shared memory layer lets Claude Code, Codex, and Warp Agent learn from each other's sessions, with self-hosted or managed storage.
Anthropic open-sources 12 practice-area plugins and 80+ agents that wire Claude directly into legal workflows — from contract review to bar prep
Perplexity is handing $250 in Computer credits to as many as 100,000 SBA loan recipients in a $25M push to put agentic AI into small business hands.
Nous Research joins NVIDIA's Nemotron Coalition and offers two free weeks of the 550B Nemotron 3 Ultra model via Hermes Agent
Liquid AI's ShieldFlow scrubs sensitive data on-device before any prompt reaches the cloud, with no GPU required and a debut at Microsoft Build 2026
Manus launches a Shopify connector that builds, manages, and markets entire e-commerce stores from a single chat — as the company navigates a turbulent Meta acquisition unwind
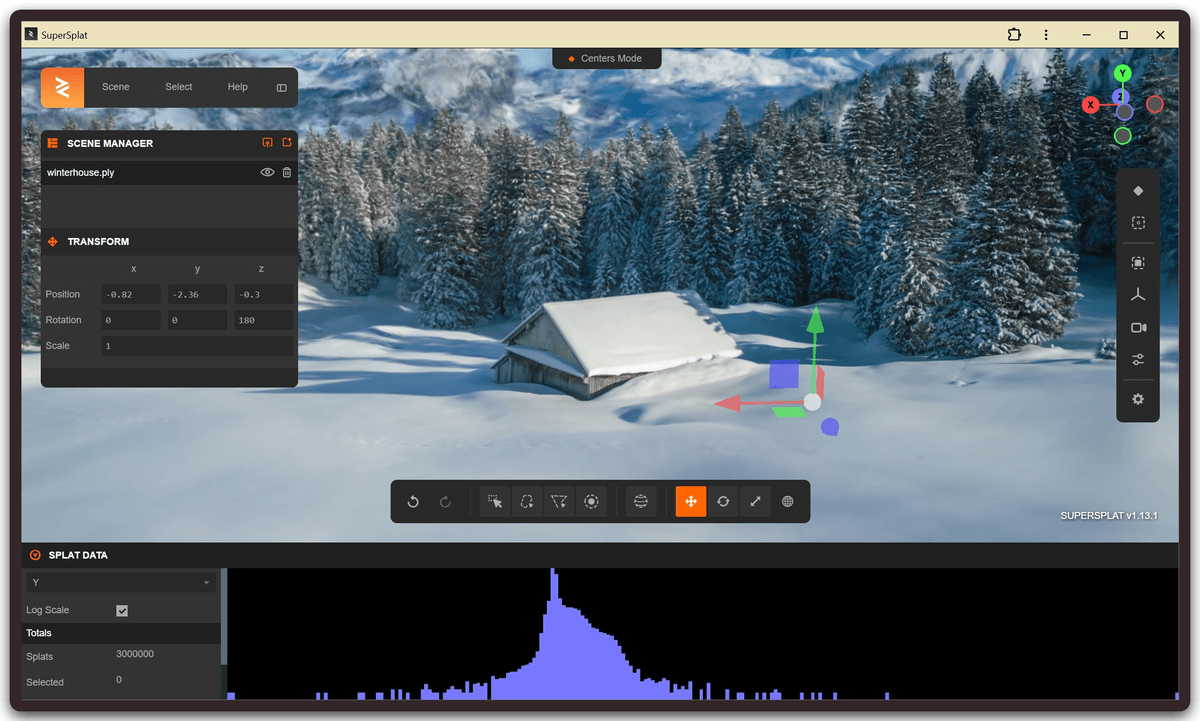
SuperSplat is a fully browser-based, MIT-licensed editor for 3D Gaussian Splats — no install, no GPU setup, and now over 9,000 GitHub stars.
Krea's new Turbo variant generates high-quality images in 2 seconds, keeping full support for style references, moodboards, and LoRAs
Runway's upgraded video editing model now propagates a single frame edit across 30-second 1080p clips and multi-shot sequences without altering untouched footage.
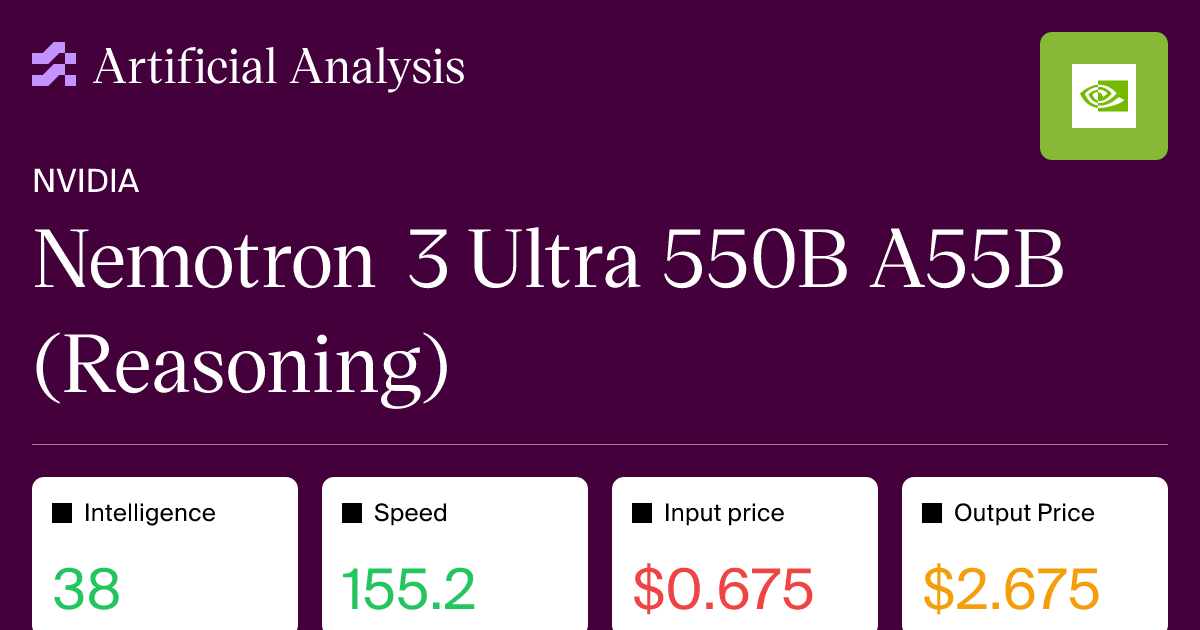
NVIDIA's Nemotron 3 Ultra is a fully open 550B-parameter reasoning model that tops the US open-weights leaderboard while running 5x faster than comparable frontier models
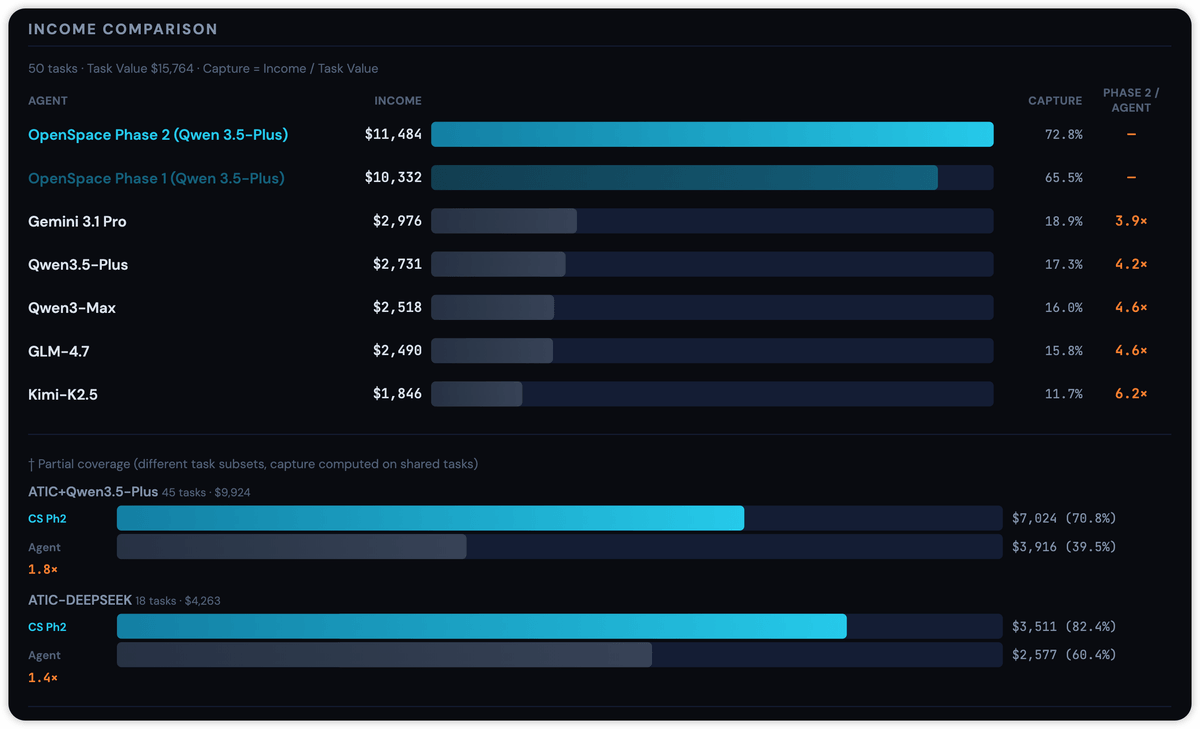
OpenSpace gives any AI agent a memory that compounds — slashing token costs by 46% while multiplying output quality across professional tasks
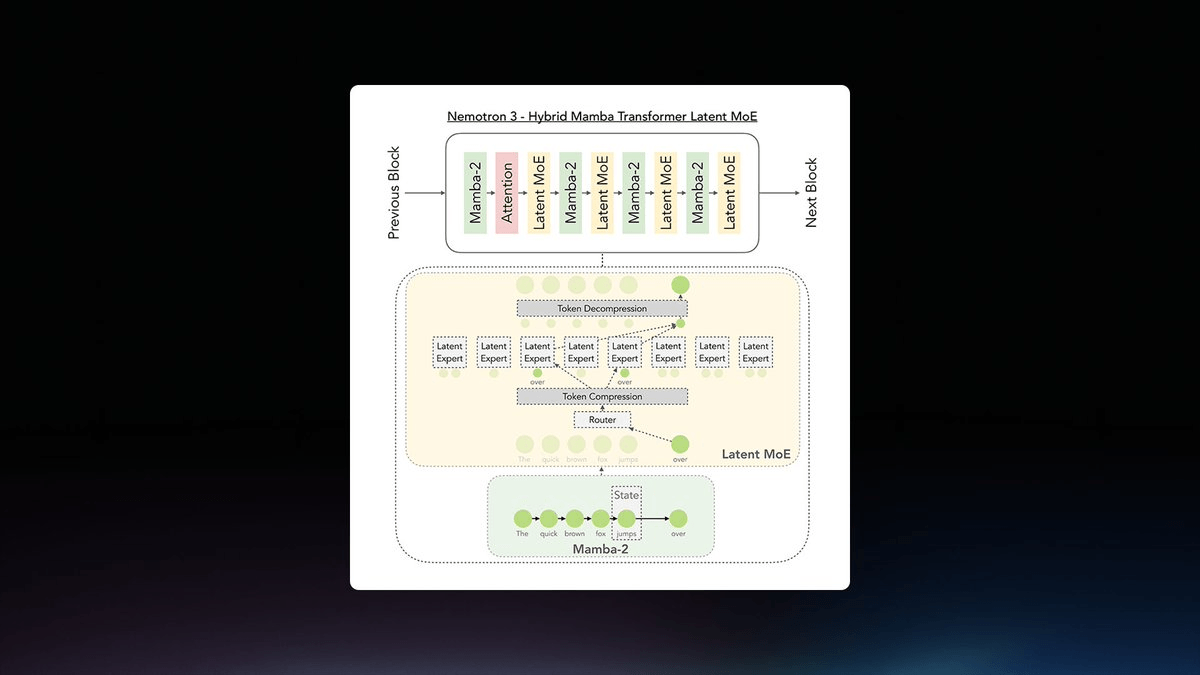
NVIDIA ships Nemotron 3 Ultra, a fully open 550B MoE model that runs 5x faster than comparable frontier models and cuts agentic task costs by 30%
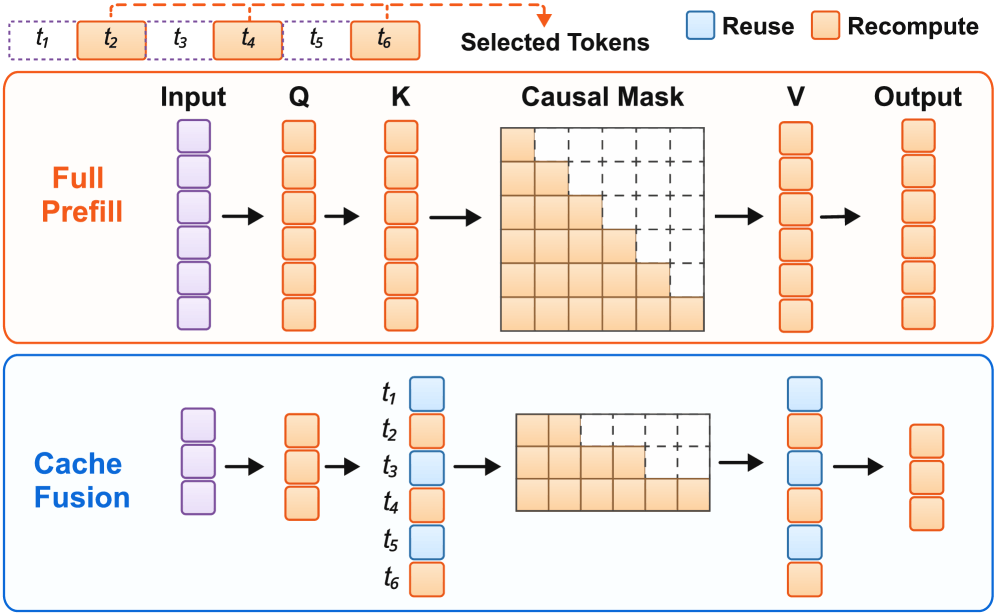
QCFuse cuts RAG prefill time by 1.7x over full prefill and 1.5x over the best baseline, matching full-quality answers without stalling the serving pipeline.
Researchers from Institute of Science Tokyo and Tencent show that simply reversing input text before embedding boosts frozen LLM performance by up to 8 points on standard benchmarks