Researchers from Brown and MIT introduce a Monte Carlo method for volumetric 3D shape analysis that runs orders of magnitude faster than prior approaches, scaling to 450,000 real-world meshes
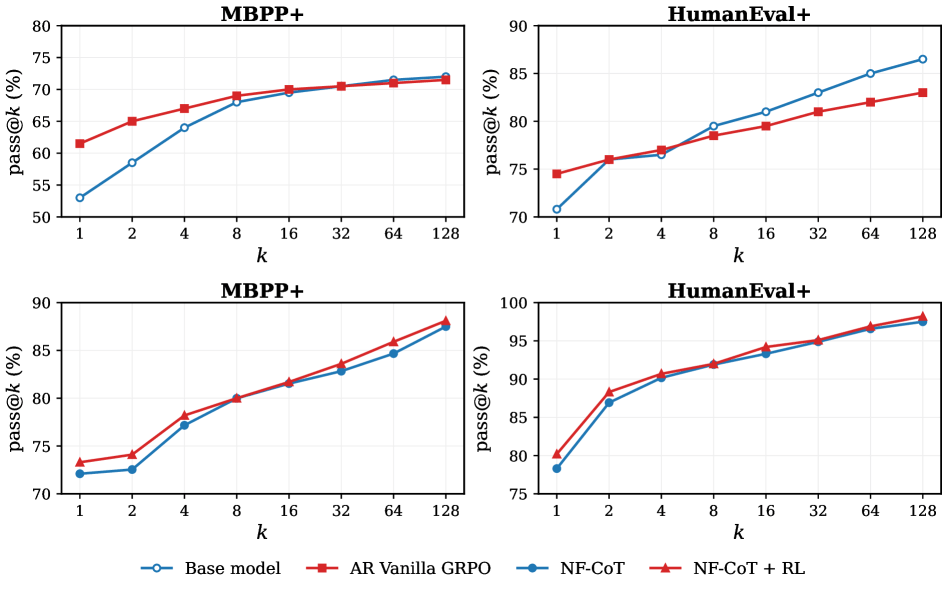
NF-CoT embeds a normalizing flow inside an LLM to reason in continuous latent space, beating explicit chain-of-thought and diffusion-based baselines on code benchmarks while running 1.9x faster.
ColBERTSaR converts ColBERT's bloated multi-vector index into a true inverted index, cutting storage 50–70% while keeping retrieval quality competitive
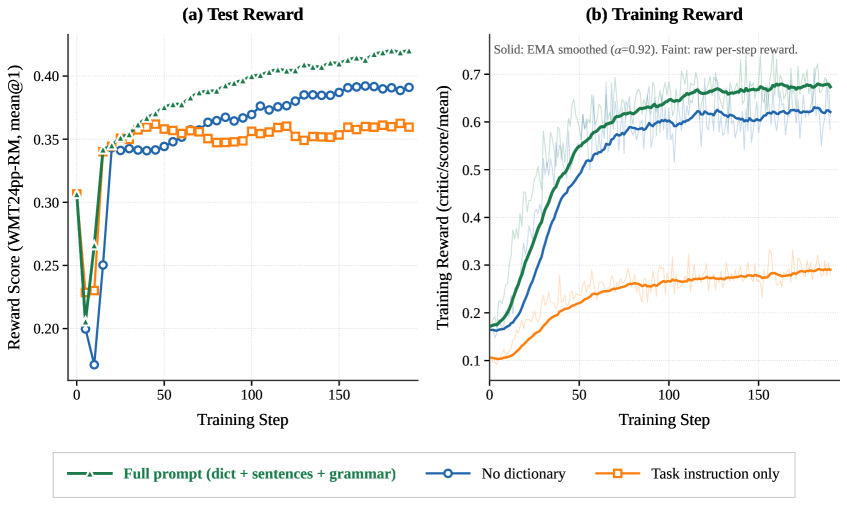
Researchers use RL with a simple translation score as reward to teach LLMs to read grammar books for languages they've never seen before — and it beats both fine-tuning and in-context learning.
A new paper shows that structurally different circuits in transformers can implement the exact same computation, exposing a fundamental flaw in how mechanistic interpretability evaluates circuit findings.
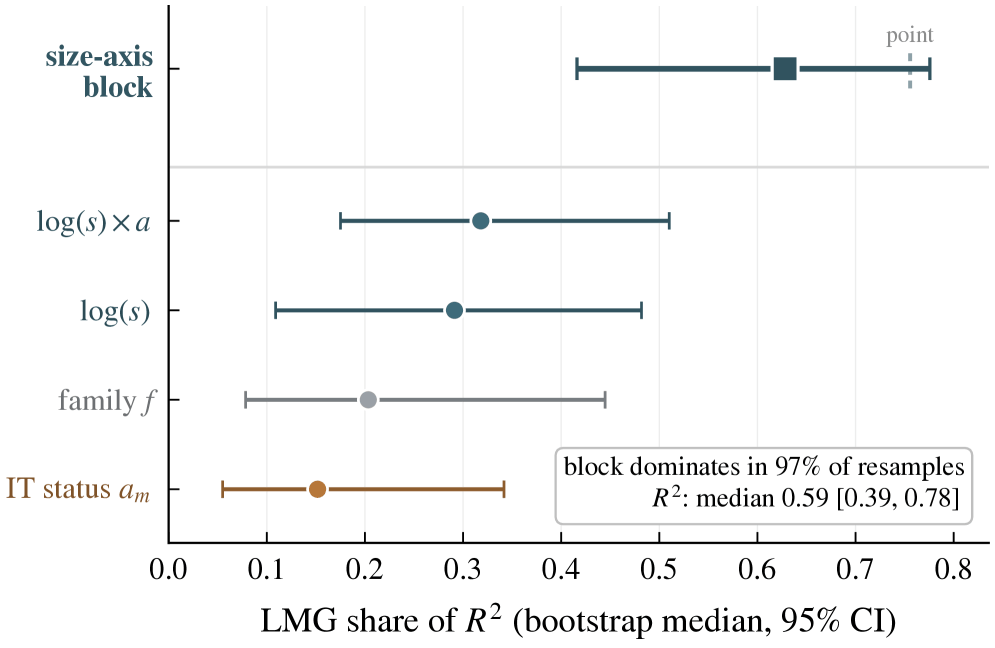
A new decomposition framework reveals that instruction tuning makes large models more sycophancy-resistant but can make small ones worse, across 56 open-weight models
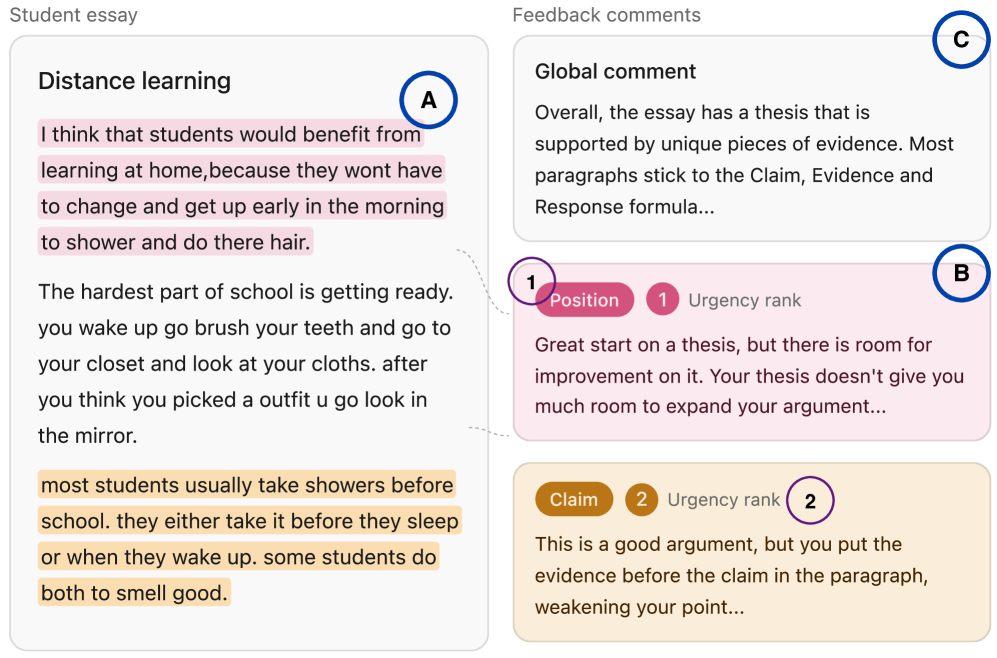
A new dataset of 2,340 essay comments reveals where LLMs and human writing instructors agree, diverge, and why longer comments inflate AI quality scores
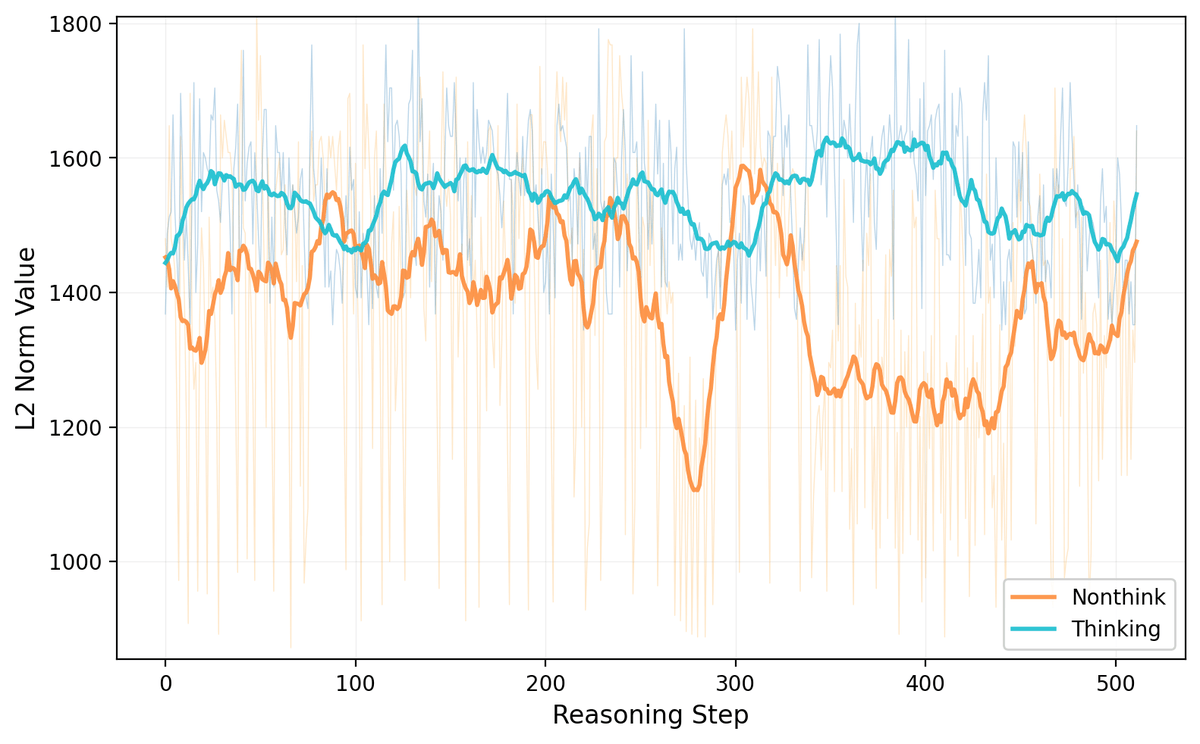
A new paper shows the L2 norm of a model's hidden states is a built-in meter for reasoning intensity, enabling three training-free techniques that boost performance on AIME, GPQA, and GSM8K.
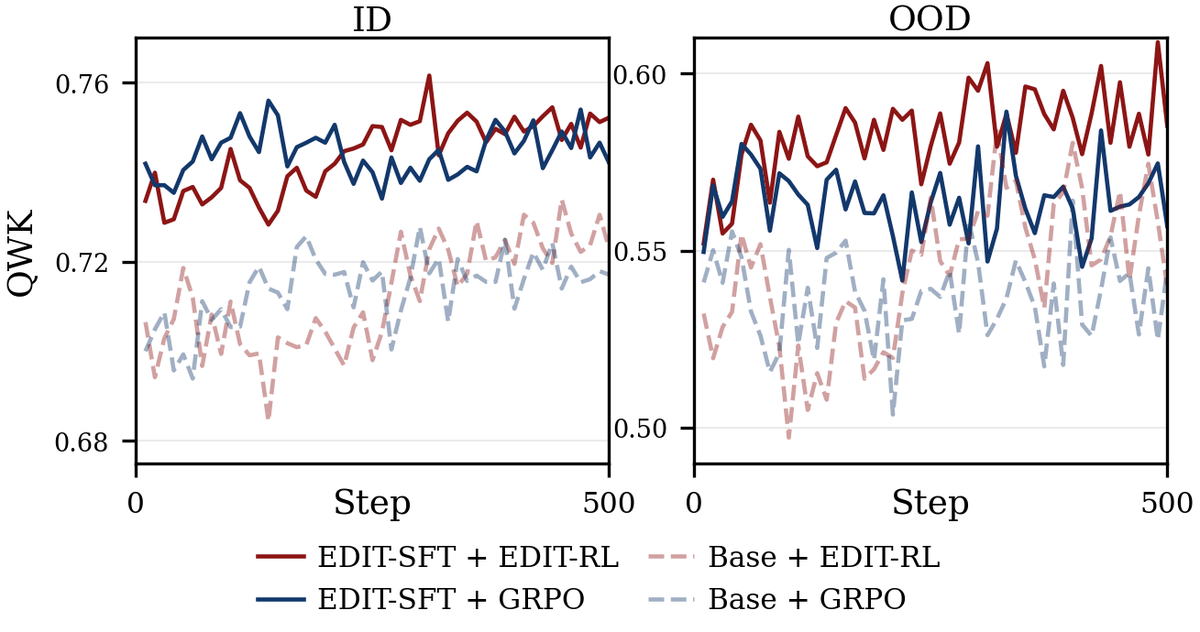
EDIT trains LLMs to grade student answers by diagnosing exactly which reasoning step went wrong and fixing only that step, beating standard RL baselines on real exam data.
A new study tests whether LLMs prompted with demographic identities can replicate how different human groups disagree on hate speech — and finds the answer is mostly no, with one surprising exception.
Researchers freeze a 4.7B-parameter SpeechLLM and inject speaker identity into every transformer layer to transcribe dysarthric speech without breaking the base model
A new user-study framework reveals that state-of-the-art speech translation fails real users roughly half the time, with stark gaps across dialects and gender.
IA-RAG replaces timestamp lookups with Allen's Interval Algebra, letting RAG systems reason about event overlap, duration, and containment for the first time
SkillComposer trains a 4B model to write, refine, and merge reusable agent skills at inference time, boosting a 27B executor by up to +4.5 points on agent benchmarks
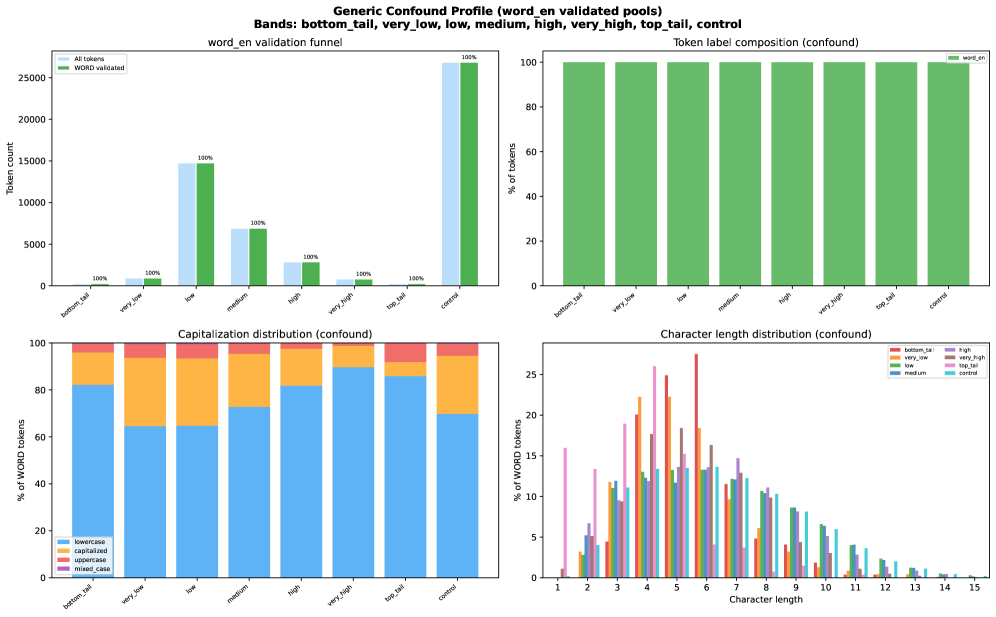
A new audit of 4 pretraining filters and 3 guardrails finds they systematically erase transgender, women's, and Central American content — while humans would keep over 88% of what these systems flag for removal.
A new study finds LLMs consistently struggle with far-right and nationalist political text across 10 models and 37 languages, and instruction-tuning does nothing to fix it.
ACE-SQL uses reinforcement learning to jointly train schema retrieval and SQL generation, hitting 65.3% on BIRD Dev with 70% fewer tokens than competing methods