| Hey, | Welcome to today's edition of AlphaSignal, a newsletter for developers by developers.
We identify and summarize the top 1% news, papers, models, and repos in the AI industry. |
|
|
|
IN TODAY'S SIGNAL
| Read time: 6 min 12 sec | 🎖️ Top News
📌 Encord: SAM 2 for Video Labeling
⚡️ Trending Signals
📌 Speechmatics: SAM 2 for Video Labeling
⚙️ Top Tutorials
🧠 How-To
|
|
|
|
If you're enjoying AlphaSignal please forward this email to a colleague.
It helps us keep this content free. |
|
|
|
TOP NEWS
| LLM | Qwen 2.5-Coder outranks GPT-4o and o1-preview on Livebench coding & released its Technical Report. |
⇧ 1,889 Likes |
 |
What's New |
Qwen2.5-Coder is the latest iteration in Alibaba's Qwen series, designed for code generation and understanding. Built on the Qwen2.5 architecture, it comes in 1.5B and 7B parameter versions, each with an instruction-tuned variant. The model supports 92 programming languages and handles up to 128K tokens of context.
Key highlights
Pretrained on 5.5 trillion tokens of code-related data Three-stage training: file-level, repo-level, and instruction tuning Coarse-to-fine hierarchical filtering for data cleaning Balanced mixture of code, math, and text data Supports multiple programming paradigms
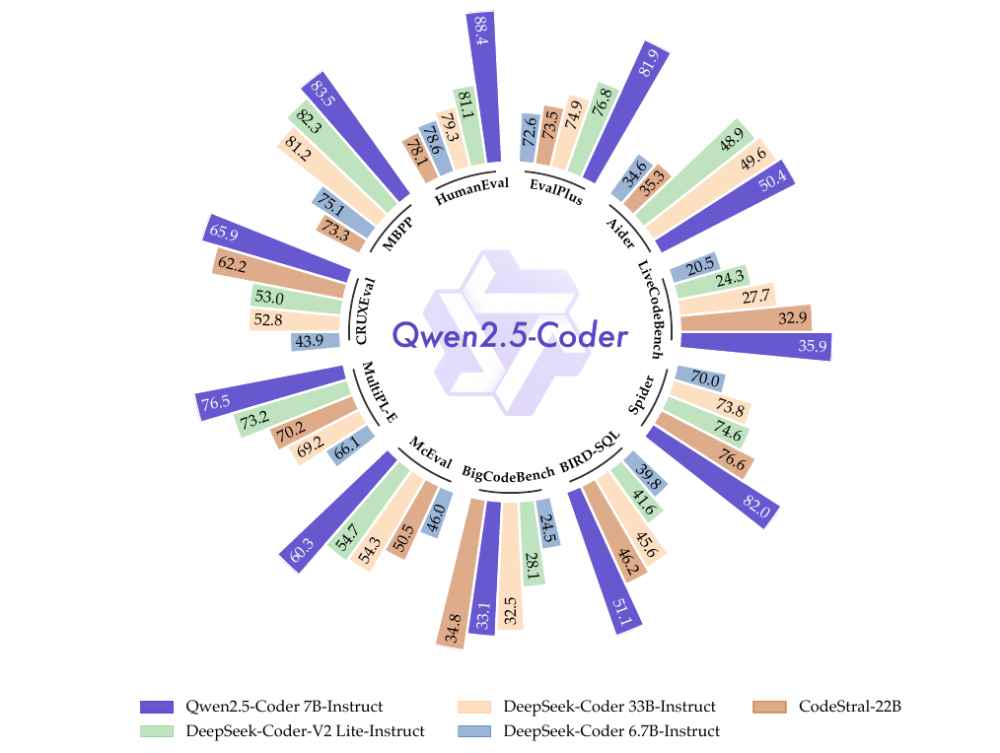
Performance Metrics Qwen2.5-Coder-7B-Instruct achieves 84.1% accuracy on HumanEval+, surpassing larger models. It scores 76.5% on MultiPL-E across 8 languages and performs well on McEval, covering 40 languages. For code reasoning, it scores 65.8% and 65.9% on CRUXEval Input-CoT and Output-CoT tasks. The model maintains strong performance in text-to-SQL tasks, scoring 82.0% on Spider and 51.1% on BIRD benchmarks.
Training Approach The model employs a unique three-stage training pipeline. File-level pretraining focuses on individual code files with a maximum sequence length of 8,192 tokens. Repo-level pretraining extends context to 32,768 tokens, with YARN mechanism allowing up to 131,072 tokens. Instruction tuning uses a mix of standard SFT data and FIM instruction samples. Data Processing: Qwen2.5-Coder introduces a coarse-to-fine hierarchical filtering approach for data cleaning. The final training dataset comprises 70% code, 20% text, and 10% math data, totaling 5.2 trillion tokens.
Practical Applications
Beyond benchmarks, Qwen2.5-Coder shows promise in real-world coding tasks. It excels in code completion, achieving high scores on HumanEval Infilling tasks across Python, Java, and JavaScript. For code editing, it scores 50.4% Pass@1 on the Aider benchmark, demonstrating practical utility for developers. |
|
|
Read more
|
|
|
|
| Label video data 8.4x quicker using SAM 2 | Cut video annotation time by 90% with Meta's new SAM 2 model. Label data 8.4x faster using automated video tracking.
SAM 2 just changed the game for AI teams. Now you can fine-tune it for your specific datasets.
Learn how to finetune SAM 2 for data labeling in their upcoming webinar. Their ML research team was first to apply SAM 2 to this use case.
Join their webinar to explore:
Practical SAM 2 integration tips Fine-tuning techniques for your data Real-world performance benchmarks |
|
Register now
| partner with us |
|
|
|
TRENDING SIGNALS
| AI Code generation |
|
⇧ 1,700 Likes | |
AI Code Generation |
|
⇧ 291 Likes | |
Machine Learning |
|
⇧ 335 Likes | |
Multi Modal Model |
|
⇧ 524 Likes | |
AI Video Generation |
|
⇧ 703 Likes | | |
|
|
|
|
|
Power your Conversational AI with this Real-Time Speech API
| Speechmatics just released a new update to their real-time speech-to-text API. It's now powering Conversational AI products globally with: The API enables robust voice interactions in applications. |
Try it today [Free] |
|
|
|
|
TOP LECTURES
| OpenAI |
| ⇧ 1,200 Likes |
Learn about OpenAI's new initiative to support AI innovation globally. Explore how the OpenAI Academy invests in developers and organizations in low- and middle-income countries. Discover the program's key components: expert training, API credits (initial $1 million), community building, and contests. See real-world examples of AI applications solving local challenges. Understand how this initiative aims to fuel economic growth and innovation across various sectors. |
| Multi AI Agent application |
|
⇧ 410 Likes |
Learn to build multi-agent applications without coding using RAGApp v0.1. This tool integrates with LlamaIndex. You'll create agents with specific roles, system prompts, and tools. The tutorial covers setup, configuration, and deployment. You'll use Docker for local testing and learn about API endpoints. It also explains security considerations and cloud deployment options. |
| AI Agent |
|
⇧ 346 Likes |
Learn to build an advanced customer service bot for a medical clinic using LangGraph. This tutorial shows you how to implement various tasks like scheduling, cancellations, and result checks. You'll create an agentic system that handles complex queries and workflows. Gain practical experience with LangGraph's capabilities in real-world applications. Enhance your skills in developing AI-powered customer service solutions. |
| |
| |
|
|
HOW TO
| Document parsing | Parse any PDF (with text/tables/images) into machine and LLM-readable markdown on your file system. |
⇧ 414 Likes |
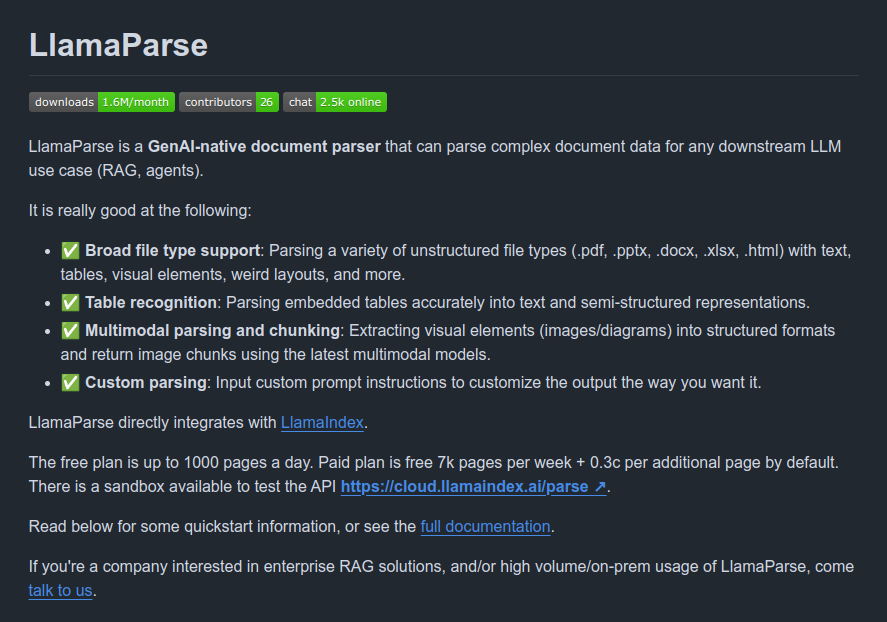 |
LlamaParse is a GenAI-native document parser that handles complex documents for LLM applications. It parses PDFs, PowerPoint, Word, Excel, and HTML files, extracting text, tables, and visual elements. LlamaParse converts these into structured formats suitable for RAG systems and AI agents. It integrates directly with LlamaIndex for seamless use in LLM pipelines.
You'll learn Parsing diverse file types Accurate table recognition Multimodal parsing and chunking Custom parsing with prompt instructions Integration with LlamaIndex Async and batch processing File object and byte handling Usage with SimpleDirectoryReader API key setup and management
Step-by-step PDF parsing with llama_parse
1. Install: `pip install llama-parse`
2. Import: `from llama_parse import LlamaParse` 3. Initialize parser:
`parser = LlamaParse(api_key="key", result_type="markdown")`
4. Parse PDF
`documents = parser.load_data("./my_file.pdf")`
5. Process results in `documents` variable
|
|
Read more
|
|
|
|
Looking to promote your company, product, service, or event to 200,000+ AI developers? Let's work together.
|
|
Advertise
|
|
|
|
|
