| Hey, | Welcome to today's edition of AlphaSignal, a newsletter for developers by developers.
We identify and summarize the top 1% news, papers, models, and repos in the AI industry. |
|
|
|
IN TODAY'S SIGNAL
| Read time: 5 min 47 sec | 🎖️ Top News
📌 Ori
Ori Serverless Kubernetes: AI cloud service with affordable, scalable, simple management. Pay-per-use pricing. Autoscaling, powerful GPUs. $1000 signup credit.
⚡️ Trending Signals
📦 Top HF Models
Mistral-NeMo-Minitron 8B: Compact model, created by pruning Mistral NeMo 12B, and then fine-tuned with knowledge distillation.
Llama-3.1-Storm-8B: Powerful 8B param language model, outperforms Llama-3.1-8B.
Magnum-v2-123b: Generate high-quality prose similar to Claude 3 Sonnet and Opus. It's fine-tuned on Mistral-Large.
🧠 Pytorch Tip |
|
|
|
If you're enjoying AlphaSignal please forward this email to a colleague.
It helps us keep this content free. |
|
|
|
TOP NEWS
| Recommendation System | Microsoft releases Phi-3.5-mixture-of-experts (MoE), outperforming Llama 3 8B and Gemma 2 9B, very close to GPT-4o mini |
⇧ 3,885 Likes |
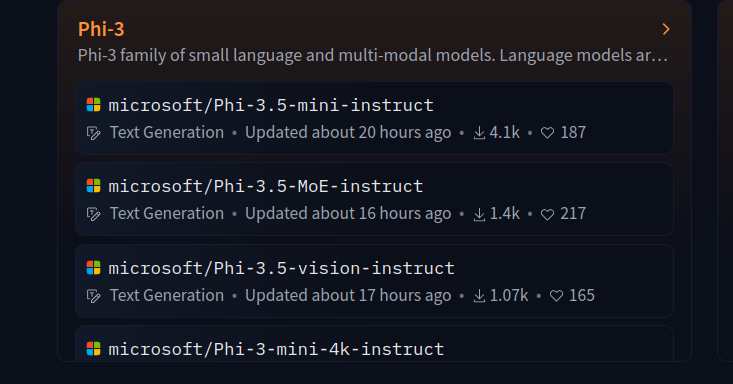 |
What's New | Microsoft has introduced Phi-3.5, a new family of language models featuring three variants: Mini-instruct (3.8B parameters), Vision-instruct (4.2B parameters), and MoE (42B parameters).
Key Points
All three models are MIT-licensed and support a 128k token context window and are available on Azure AI Studio and Hugging Face. Trained on 4.9 trillion tokens, including 10% multilingual content, Phi-3.5-MoE outperforms Llama 3.1 8B and competes with GPT-4o mini across benchmarks. The model is intended for commercial and research use in multiple languages.
Performance metrics showcase Phi-3.5's capabilities Phi-3.5-MoE: Average score of 69.2 on 21 benchmarks (vs. GPT-4o mini's 74.9) Phi-3.5-Mini: MMLU (69), MATH (48.5), HumanEval (62.8) Phi-3.5-Vision: BLINK benchmark score of 57 (comparable to Claude 3.5 Sonnet's 56.5) Architectural Details
The Phi-3.5-MoE model employs a Mixture of Experts architecture with 16 experts, activating only 2 during generation. This design allows for a 42B parameter model with just 6.6B active parameters during inference. The Vision-instruct model integrates an image encoder, connector, and projector, trained on 500 billion tokens of combined vision and text data. All Phi-3.5 variants underwent alignment using Supervised Fine-Tuning (SFT), Proximal Policy Optimization (PPO), and Direct Preference Optimization (DPO) techniques. These methods aim to improve the models' ability to follow instructions.
Training token details Mini - 3.4 trillion tokens MoE - 4.9 trillion tokens Vision - an additional 500B of vision tokens. | |
|
Read more
|
|
|
|
| Kickstart your AI training with $1000 in matched credit
|
Meet the specialized demands of your AI/ML workloads with their scalable, efficient, and robust cloud infrastructure. Reduce your AI costs with GPU-accelerated virtual machines, bare metal instances or Serverless Kubernetes.
AI-optimized infrastructure: Customize your hardware, storage, and networking to fit your unique workload needs. Flexible scalability: Configure compute, storage, and networking to scale as your demand increases. Reduce your AI costs: Benefit from personalized pricing and configurations that the hyper-scalers can't match. Receive $1000 in matched GPU credit when you sign up. |
|
Get started
| partner with us |
|
|
|
TRENDING SIGNALS
| OpenAI |
|
⇧1,349 Likes | |
LLM | |
⇧ 1,610 Likes | |
Google AI |
|
⇧ 1,100 Likes | |
LLM Inference Cost |
|
⇧ 1,490 Likes | |
AI Automation |
|
⇧ 1,759Likes | | |
|
|
|
|
|
TOP MODELS
| Language Models |
| ⇧Released just 4 hours before, so download data is not meaningful
| A compact model outperforming Llama 3.1 8B across key benchmarks. On HumanEval (0-shot), it scores 36.22 vs Llama 3.1 8B's 24.76. The model is created by pruning Mistral NeMo 12B. It's then fine-tuned with knowledge distillation on 380B tokens. This process is 40x more efficient than training from scratch. |
| Language Models |
|
| ⇧ 1141 Downloads |
Powerful 8B param language model that outperforms Llama-3.1-8B-Instruct across 10 benchmarks, including a 7.21% gain in GPQA and 9% in TruthfulQA. The model uses self-curated data, targeted fine-tuning, and SLERP merging with Llama-Spark. It excels in instruction-following, reasoning, and function calling tasks. |
| Language Model |
|
⇧ 1,505 Downloads |
Helps you generate high-quality prose similar to Claude 3 Sonnet and Opus. It's a 123B parameter model fine-tuned on Mistral-Large-Instruct-2407. Uses Mistral's instruction format. Trained for 1.5 epochs on 8x AMD MI300X GPUs. Incorporates filtered data from Stheno, Kalo-opus, and Claude writing datasets. Sensitive to learning rate adjustments due to narrow weight distributions. |
| |
|
|
|
|
|
PYTORCH TIP
| Language Models |
torchtune: Easily fine-tune LLMs using PyTorch |
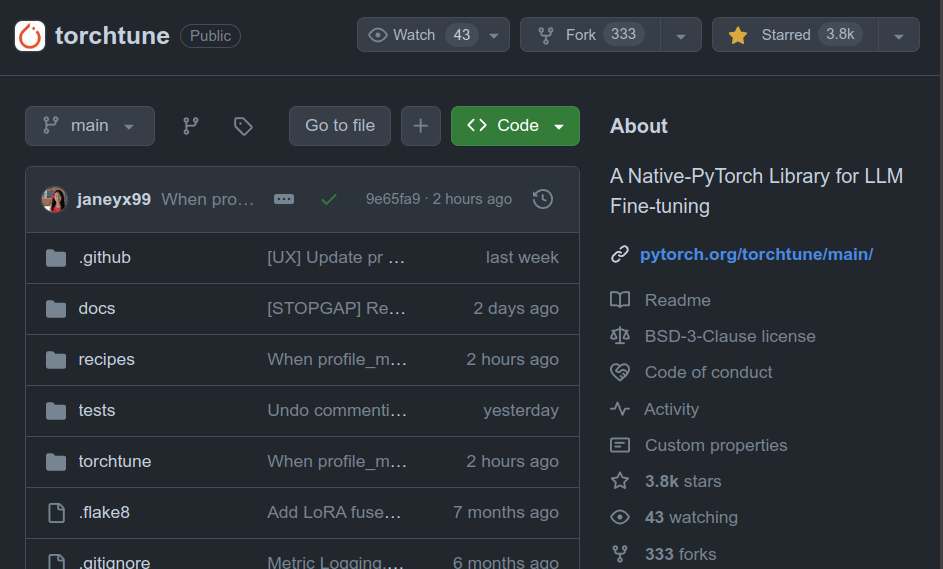 |
torchtune provides modular components for customizing the entire fine-tuning process, from data preparation to model evaluation. You can adapt LLMs to specific tasks or domains without high-end hardware, as it supports consumer-grade GPUs.
It integrates smoothly with Hugging Face Hub for models and datasets, PyTorch FSDP for distributed training, and Weights & Biases for experiment tracking.
torchtune is useful when adapting pre-trained models to specialized applications like medical text analysis or legal document processing.
Checkout many recipes in their official GitHub repo. Each recipe is self-contained - no trainers or frameworks, and is designed to be easy to read - less than 600 lines of code!
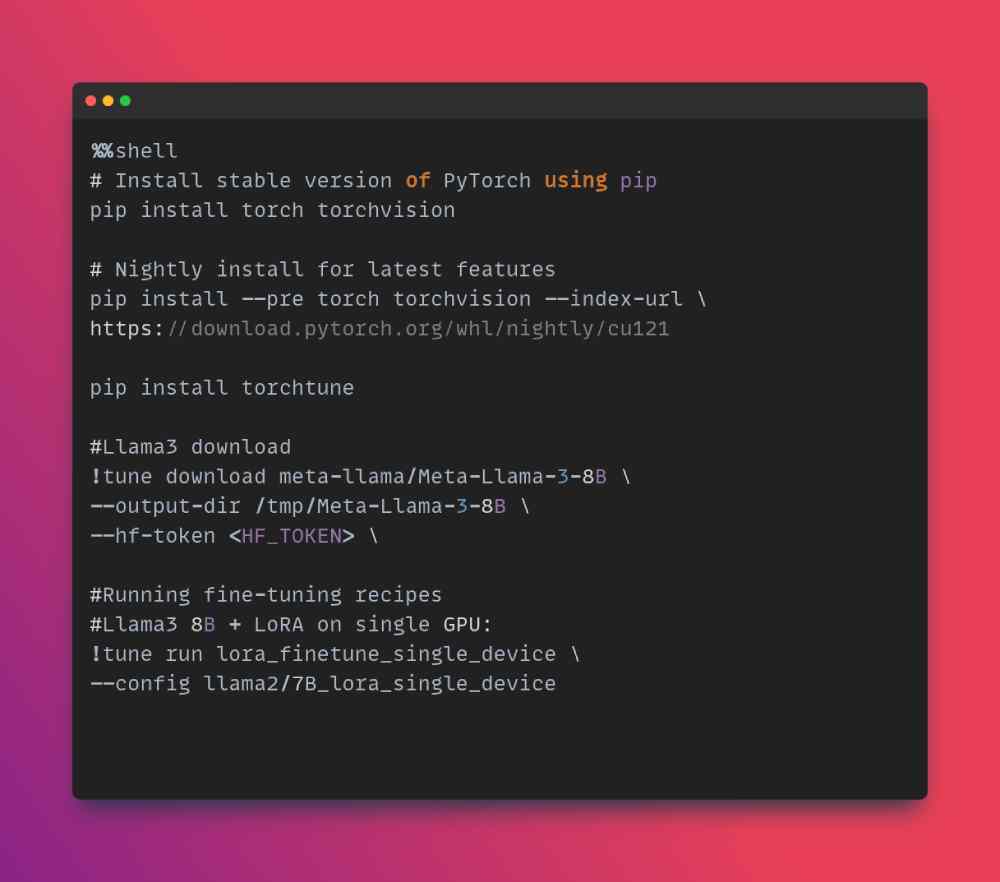
Let's walk through a basic fine-tuning code with the below code. As a 1st step, install the latest stable PyTorch, as torchtune is extensively tested with this version. |
 |
|
torchtune Github Repo
|
|
|
|
Want to promote your company, product, service, or event to 190,000+ AI researchers and engineers?
|
|
Sponsor
|
|
|
|
|
