| Hey, | Welcome to today's edition of AlphaSignal, a newsletter for developers by developers.
We identify and summarize the top 1% news, papers, models, and repos in the AI industry. |
|
|
|
IN TODAY'S SIGNAL
| Read time: 5 min 21 sec | 🎖️ Top News
📌 Ray Summit 2024
⚡️ Trending Signals
📦 Top HF Models
🧠 Deep Dive
|
|
|
|
If you're enjoying AlphaSignal please forward this email to a colleague.
It helps us keep this content free. |
|
|
|
TOP NEWS
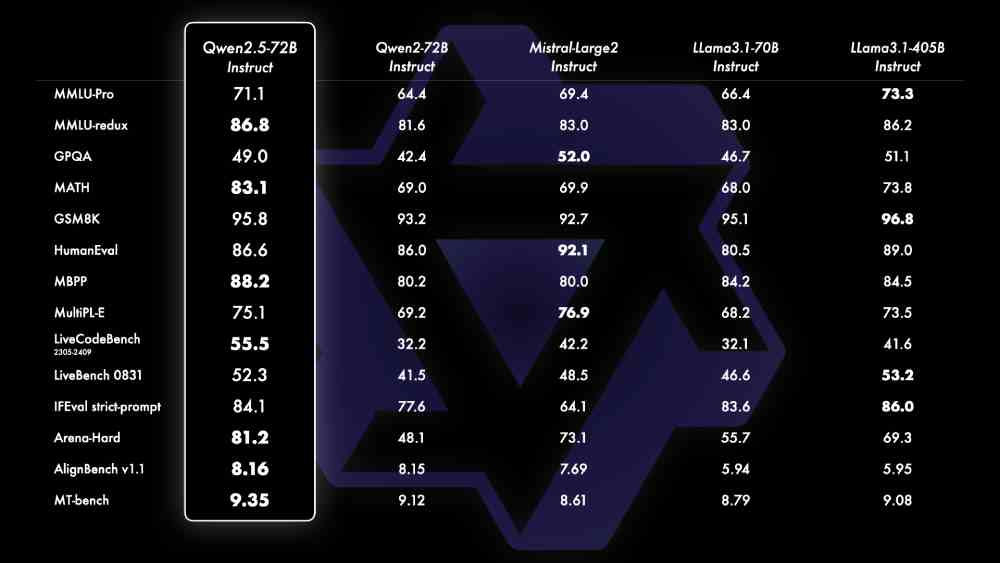
| LLM | Qwen, a Chinese AI company, dropped Qwen 2.5, a new series of LLMs ranging from 0.5B to 72B parameters |
⇧ 1,353 Likes |
 |
What's New | This release from Qwen includes general-purpose models, specialized coding and math variants, and an updated vision-language model.
Key Points
The Qwen 2.5 models were trained on 18 trillion tokens, exceeding the 15T used for Meta's Llama 3. They support a 128K token context length and can generate up to 8K tokens. The models cover over 29 languages, including English, French, Spanish, and Chinese. Enhanced instruction following Better structured data understanding Improved JSON output generation Advanced system prompt handling for role-playing Increased resilience to diverse system prompts The release includes various quantized versions (GPTQ, AWQ, GGUF) for efficient deployment. Qwen provides integration with popular frameworks like Hugging Face Transformers, vLLM, and Ollama, offering tool-calling support and easy implementation. Access
All models have the most permissive license apache2.0, except the 72B models that have a custom license mentioning "you can use it for free EXCEPT if your product has over 100M users". All the open-sourced models, except for the 3B and 72B variants, in the above family are available in HuggingFace Performance benchmarks
Qwen 2.5-72B is competitive with Llama-3.1-405B and outperforms Llama-3.1-70B on most tests. The 32B variant surpasses OpenAI's GPT-4o mini, while the compact 3B model achieves a 68 score on MMLU, outperforming Qwen1.5-14B. Qwen 2.5-Coder, available in 1.5B and 7B sizes, demonstrates superior performance compared to larger coding-specific models like DeepSeek-Coder 33B-Instruct. Qwen 2.5-Math introduces support for Chain-of-Thought, Program-of-Thought, and Tool-Integrated Reasoning in both English and Chinese.
|
|
|
Read more
|
|
|
|
| Ray Summit 2024: The Largest Gathering of AI Experts and Leaders is 11 Days Away | Ray Summit 2024 features 60+ sessions with AI and ML industry leaders.
Connect with top leaders from:
NVIDIA Intel Google Apple OpenAI Coinbase Plus others |
|
Get 15% off
| partner with us |
|
|
|
TRENDING SIGNALS
| AI Code generation |
|
⇧ 1,793 Likes | |
Speech to Speech Model |
| ⇧ 4,905 Likes
| | Video Generation |
|
⇧ 332 Likes | |
Video Generation |
|
⇧ 534 Likes | |
Computer Vision |
|
⇧ 347 Likes | | |
|
|
|
|
|
TOP MODELS
| LLM | |
| ⇧98 Downloads |
Nemotron-Mini-4B-Instruct helps you generate responses for roleplaying, RAG, and function calling. This 4B-parameter SLM is optimized for speed and on-device deployment. It supports 4,096 token context and uses a 3072 embedding size, 32 attention heads, and 9216 MLP dimension.
Key features
Distilled from 15B model Uses GQA and RoPE Commercially licensed Trained Feb-Aug 2024 Optimized for English tasks Undergone safety evaluation (Garak, AEGIS, human testing) | |
MoE |
|
⇧ 77 Downloads |
GRIN MoE helps you build powerful AI systems with minimal computational resources. This 6.6B active parameter model outperforms larger models in coding and math tasks. It achieves 79.6% average score across popular benchmarks, surpassing Mixtral 8x7B.
Key features
16x3.8B total parameters, 6.6B active 4K token context length Trained on 4T tokens Excels in memory/compute constrained environments Strong reasoning in code, math, and logic Supports multiple languages MIT license
| | Code LLM |
|
⇧ 5,659 Downloads | DeepSeek-V2.5 helps you build advanced AI applications with improved general and coding abilities. It combines DeepSeek-V2-Chat and DeepSeek-Coder-V2-Instruct, offering better alignment with human preferences.
Key features
Outperforms predecessors in benchmarks like AlpacaEval 2.0 (50.5) and HumanEval python (89) Supports function calling and JSON output Handles Fill-In-the-Middle (FIM) tasks Runs locally on 8 GPUs with 80GB each Integrates with Hugging Face Transformers and vLLM for efficient inference Allows commercial use under its license | |
|
| |
|
|
DEEP DIVE
| Create Synthetic Dataset Using Llama 3.1 to Fine-Tune Your LLM |
 |
In this blog you will learn using Llama 3.1 405B and Nvidia Nemotron 4 reward model to create a synthetic dataset for instruction fine-tuning.
Key steps Get Nvidia NIM API key for Llama 3.1 405B access. Generate subtopics for your dataset using Llama 3.1. Create instructions for each subtopic with Llama 3.1. Generate responses for each instruction using Llama 3.1. Use Nvidia's Nemotron 4 to score and filter responses. Remove low-quality responses based on helpfulness and verbosity scores. Save filtered dataset as JSON Lines file. Log in to Hugging Face and upload your dataset.
This process helps you create a synthetic dataset for fine-tuning smaller LLMs. It uses Llama 3.1 405B to generate high-quality instruction-response pairs and Nemotron 4 to refine the dataset.
Its a very cost-effective method and gives you control over dataset creation. |
|
Read more
|
|
|
|
Looking to promote your company, product, service, or event to 200,000+ AI developers? Let's work together.
|
|
Advertise
|
|
|
|
|
