| Hey, | Welcome to AlphaSignal – the most read newsletter by AI developers.
We bring you the top 1% of news, papers, models, and repos, all summarized to keep you updated on the latest in AI. |
|
|
|
IN TODAY'S SIGNAL
| Read time: 6 min 38 sec | 🎖️ Top News
📌 Predibase
⚡️ Trending Signals
💻 Trending Repos
open-codex: Terminal-based coding agent that reads, writes, runs, and tests code using any ChatGPT-compatible model.
developer-roadmap: Open source interactive developer roadmaps and best practices to guide learning across multiple tech domains.
pocketbase: Go-powered backend with realtime API, auth, storage, and embedded SQLite in one binary.
🧠 Top Lecture |
|
|
|
If you're enjoying AlphaSignal please forward this email to a colleague.
It helps us keep this content free. |
|
|
|
TOP NEWS
| RL | Google DeepMind introduce Streams for RL agents to learn from continuous interaction, instead of static data
| ⇧ 3,827 Likes |
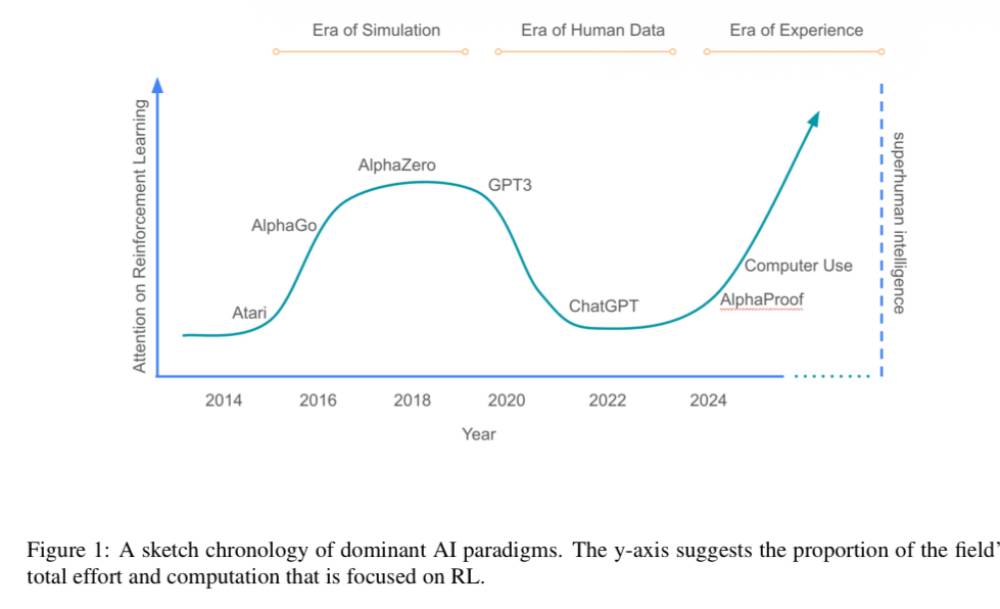
| What's New | Pioneers of modern reinforcement learning, Richard Sutton and David Silver released a new paper, “Welcome to the Era of Experience,” proposing that AI should stop relying on fixed human-labeled data.
They argue that supervised pre-training and RLHF have hit diminishing returns. The paper introduces “streams”, continuous interaction loops with real or simulated environments, as the foundation for future agents.
Core Concept: Learning through experience Agents create and learn from their own data in dynamic environments.
Avoids dependence on finite human-generated datasets for training.
Uses environmental feedback instead of supervised labels or predefined objectives.
Supports continuous, long-term learning across multiple tasks and domains.
Focuses on capability growth over time, not task-specific performance.
Streams The stream model replaces static datasets with continuous interaction. Streams operate without resets, retain state across time, and provide real-time feedback from the environment.
Each stream is a sequence of actions, observations, and rewards without episodic breaks.
Agents update policies continuously instead of training on frozen datasets.
Feedback comes from the task environment, not human annotations or rankings.
Agents use rewards tied to measurable outcomes like scores, accuracy, or task completion.
Setup: Use Persistent Environments
Stream-compatible setups require stateful, interactive environments that support long time horizons. Minecraft (via MineDojo or Voyager) supports long-term exploration and crafting behaviors.
NetHack provides procedural depth and long-horizon reasoning under constraints.
Scientific simulators model drug discovery or materials optimization with direct task rewards.
Real-world tasks include learning from medical records or educational assessments over time.
Adapt Existing RL Tools You can use RLlib, CleanRL, or JAXline with added memory and environment persistence.
Agents must handle cross-session memory and long-term state tracking.
Replay buffers or episodic memory modules enable experience accumulation.
Planning modules adapt models across variable state sequences.
Exploration bonuses support open-ended learning without task supervision.
Replace labels with task signals
Rewards derive from objective metrics instead of subjective preference scores. Use exam scores, chemical novelty, or execution correctness as ground truth.
No human judgment required for reward shaping or ranking.
Intrinsic motivation guides exploration when task feedback is sparse.
Evaluation uses outcome-based metrics rather than imitation accuracy.
Tool use and custom integrations Both models support dynamic tool use with improved argument selection and context awareness.
Integrates with function calling and custom tools through the OpenAI API
Determines tool use based on system and user messages
Refines arguments more accurately during multi-turn tasks
Supports mixed-modality workflows including vision, text, and code
Implementation: Where and how to apply it
You can prototype these systems in formal logic and structured environments. Use Lean, Coq, or similar theorem provers to simulate controlled learning settings.
Train with RL libraries that support self-play and reward-based feedback loops.
Focus on environments where exploration creates high-value learning data.
Avoid reliance on human annotations or static benchmarks.
Community Feedback
LostAndFounding
"This seems completely sensible to me. It reminds me of the (much earlier) days of Machine Learning where there was a desire to move quickly towards "online" models that could ingest and adapt in realtime after some of the most popular algos (e.g. SVM) has been proven in static context."
Peter
"Wow. This has significant implications - current foundation model companies with large marketshare will accumulate an insurmountable lead with their access to proprietary experience data. And as they verticalize, they’ll turn into the AI version of AWS/GCP/Azure"
visarga
"Many people like to say we are just one or two discoveries away from AGI, I think they are wrong, it's a matter of data-loop, not algorithmic innovation. What Sutton says is that progress will come from interactivity not clever algorithms." | |
| Read more
|
|
|
|
| Fix Latency Bottlenecks in Your LLM Stack | Shipping an LLM is easy. Running it fast at scale is the hard part.
On April 24 at 10 AM PT, Predibase breaking down how to optimize LLM inference in real environments. You’ll see where latency issues actually come from, cold starts, memory limits, poor scaling. And how to fix them using quantization, speculative decoding, and autoscaling.
What you’ll walk away with:
Concrete ways to boost throughput and cut response times
Benchmarks against vLLM on real use cases like summarization and chat
A reference stack built for sub-second latency
A look at the new Predibase Inference Engine, built to auto-optimize any open model |
| Save your spot
| partner with us → |
|
|
|
TRENDING SIGNALS
| Responsible AI |
|
⇧ 1,639 Likes | |
AI Infrastructure |
|
⇧ 1,438 Likes | |
Generative AI |
|
⇧ 1,957 Likes | |
Conversational AI |
|
From Our Partners | |
Product Update |
|
⇧ 1,639 Like | | |
|
|
|
|
TRENDING REPOS
| Coding Agents | |
☆ 1,429 Stars |
Use this CLI to run agentic coding tasks directly in your terminal using any OpenAI-compatible provider. It supports full-autonomy with sandboxed execution, file diffs, and shell commands. In full-auto mode, tasks like refactoring or generating tests run end-to-end. Works with OpenAI, Gemini, OpenRouter, and Ollama. No setup beyond API keys.
|
| Open Source Curriculum |
| ☆ 315,284 Stars |
Explore interactive, open-source roadmaps for 50+ roles and technologies. It helps you navigate learning paths for AI, DevOps, Frontend, Backend, System Design, and more. Roadmaps include clickable nodes, best practices, and curated questions. Built with Astro and Tailwind 4. Requires Node.js and npm to run locally. |
| Developer Tools |
| ☆ 45,385 Stars |
Use PocketBase to build a full-featured backend in a single Go binary. It provides a realtime API, embedded SQLite database, file storage, auth, and an admin UI. Extend it with Go or JavaScript. Supports WebSocket subscriptions and cross-platform builds.
|
| |
| |
|
|
TOP LECTURE
| AI Industry |
Exploring AGI and the Future of AI: Insights from Demis Hassabis |
⇧ 1,248 Likes |
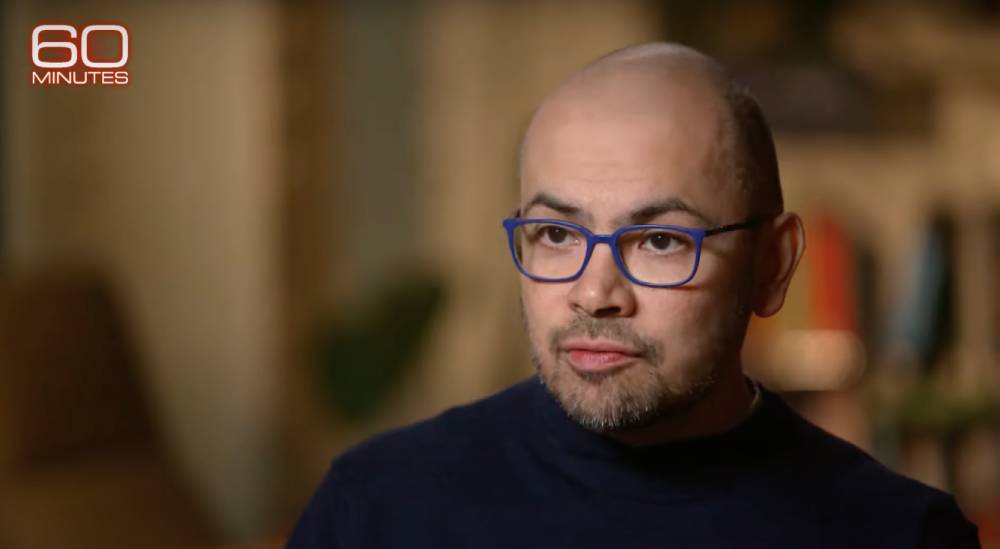
| Demis Hassabis, CEO of Google DeepMind and Nobel laureate, shares a direct look at AGI timelines, AI reasoning, and medical breakthroughs in this 60 Minutes interview.
He discusses near-future milestones in AI, including the projected 5–10 year window for AGI and demonstrates live systems with vision, emotion reading, and abstract reasoning.
Topics covered:
AGI timeline and progress
AI’s impact on drug discovery and medicine
DeepMind’s Project Astra demos: painting recognition, emotion reading
Experimental robotics with reasoning and abstract concept understanding
The future of AGI: implications for industry and society |
| Watch now
|
|
|
|
At Alpha Signal, our mission is to build a sharp, engaged community focused on AI, machine learning, and cutting-edge language models, helping over 200,000 developers stay informed and ahead. We’re passionate about curating the best in AI, from top research and trending technical blogs to expert insights and tailored job opportunities. We keep you connected to the breakthroughs and discussions that matter, so you can stay in the loop without endless searching. We also work closely with partners who value the future of AI, including employers and advertisers who want to reach an audience as passionate about AI as we are.
Our partnerships are based on shared values of ethics, responsibility, and a commitment to building a better world through technology.Privacy is a priority at Alpha Signal. Our Privacy Policy clearly explains how we collect, store, and use your personal and non-personal information. By using our website, you accept these terms, which you can review on our website. This policy applies across all Alpha Signal pages, outlining your rights and how to contact us if you want to adjust the use of your information. We’re based in the United States. By using our site, you agree to be governed by U.S. laws. |
|
|
|
Looking to promote your company, product, service, or event to 200,000+ AI developers? Let's work together.
|
| Work with us
|
|
|
|
|
