Pro
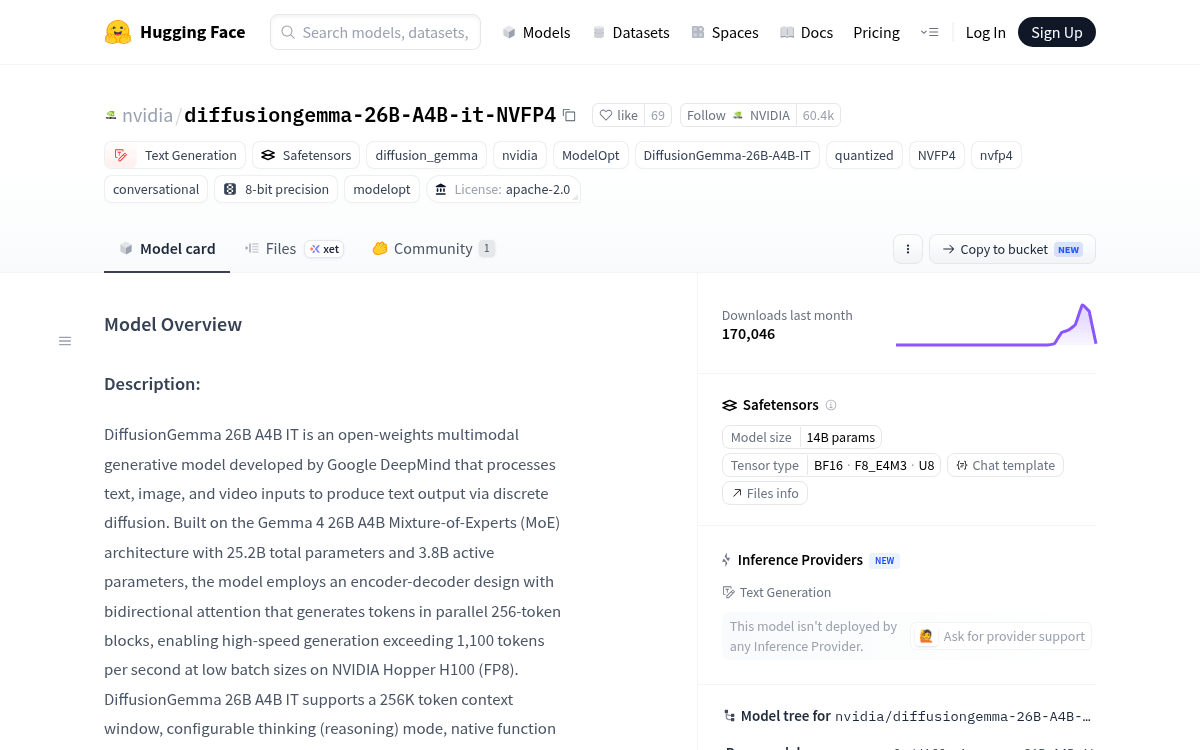
Google DeepMind's DiffusionGemma Generates Text 4x Faster by Ditching Sequential Tokens
Google DeepMind's DiffusionGemma generates 256 tokens in parallel, hitting 1,100+ tokens/sec on a single H100 — a new architecture for speed-first local inference