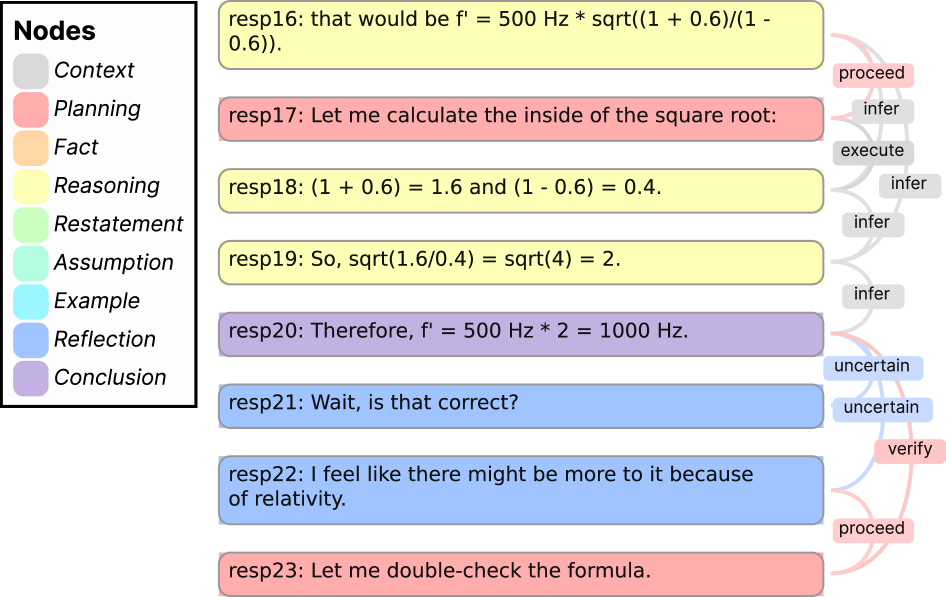
ReasoningFlow converts LLM reasoning traces into fine-grained DAGs with 8 node types and 14 edge types, revealing that most errors in reasoning models never actually affect the final answer
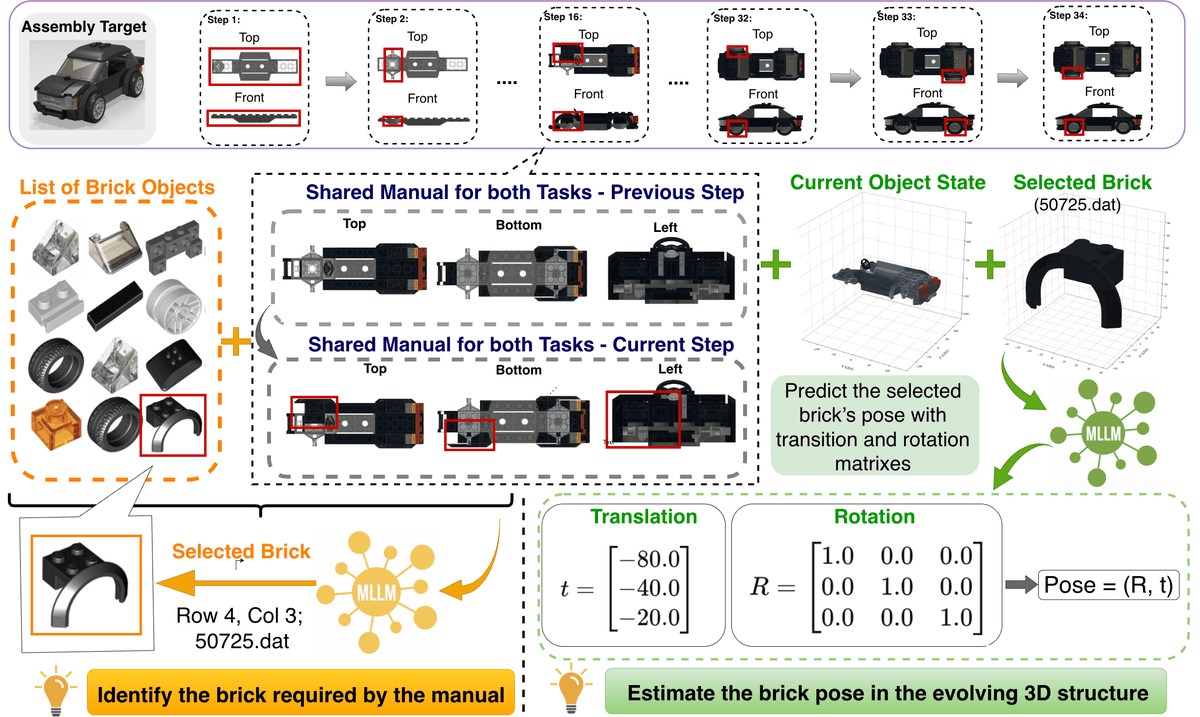
Brick-Composer teaches multimodal LLMs to assemble LEGO-style objects step by step, boosting success rates from near zero to 15% with a new benchmark and three-signal training framework.
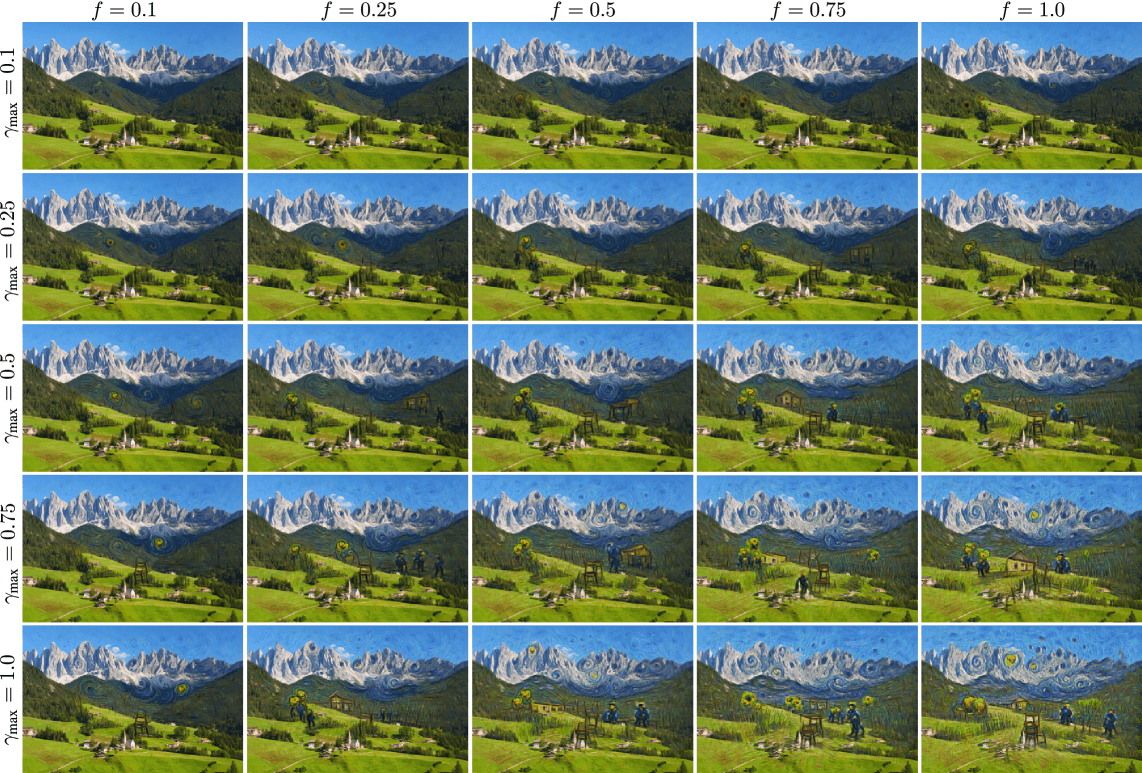
A new arXiv paper replaces hours of single-image diffusion training with a closed-form math formula, matching trained models on quality while generating megapixel images in one second.
LeanMarathon is a multi-agent system that fully formalizes entire research-level math papers into machine-checked Lean 4 proofs, autonomously and without human intervention.
RISC replaces majority voting with a learned ranker that cuts LLM calls by up to 82% while also beating peak self-consistency accuracy on QA benchmarks
A new training-free algorithm exploits a depth-dependent asymmetry in transformer layers to merge task and domain LoRA adapters into a single, better-performing model.
BreastGPT is the first unified multimodal LLM to handle the full breast cancer clinical pipeline, from screening to treatment planning, across five imaging modalities in a single model.
Rakuten Taiwan used LLMs and human annotators to build a product attribute taxonomy from scratch, boosting search retrieval by over 5% across 5.4 million products
PersonaTree introduces a three-level memory tree that turns raw interaction history into grounded, inspectable user models — beating Mem0 and peers across 18 benchmark settings.
APB stress-tests 12 frontier models on planning-only tasks, exposing critical weaknesses in long-horizon reasoning, tool noise, and knowing when to refuse
A new routing agent cuts compute costs by 26% in LLM-based Lean theorem provers without sacrificing solve rates, by learning when to give up on a failing proof.
KIT's IWSLT 2026 system turns short speech datasets into 1M long-form training examples and exposes a critical flaw in how re-ranking is applied across mixed speech tasks
DuDi combines three distillation signals and a cross-lingual verbalizer to dramatically improve sub-billion parameter models on Southeast Asian languages
KAIST researchers replace Mamba's rigid image scan order with a query-driven cross-attention projector, cutting visual tokens and boosting both accuracy and throughput on vision-language benchmarks.