
OpenMono Runs a Full Coding Agent on Your Hardware for Free
OpenMono packs a full agentic coding loop, 20 tools, Docker sandbox, and bundled llama.cpp inference into a single-command install with no per-token cost.
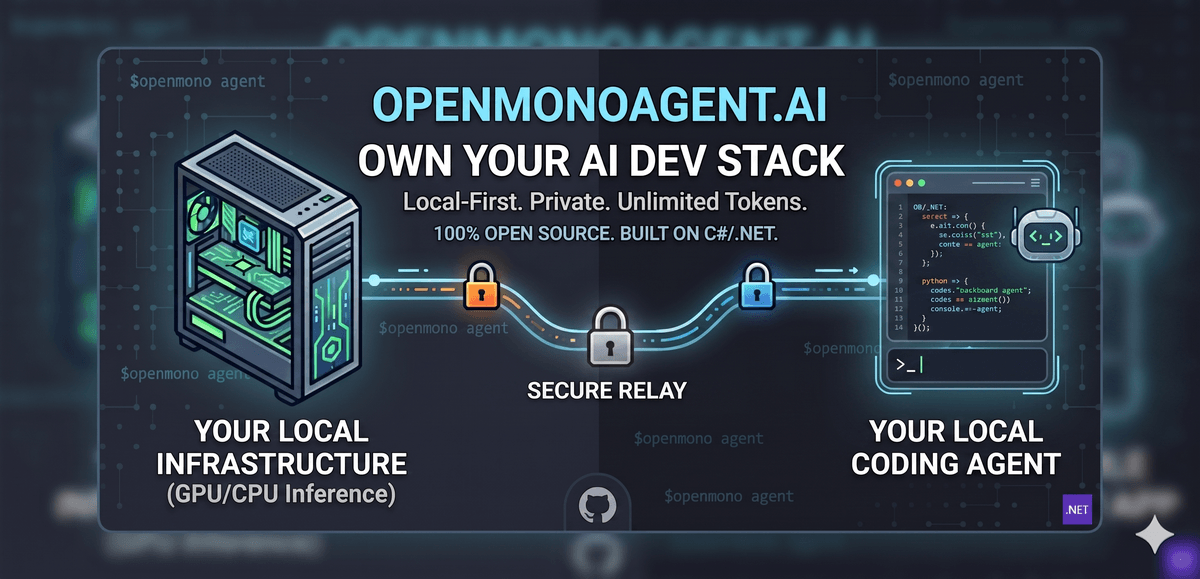
Takeaways
- OpenMono is a terminal-native coding agent that runs entirely on local hardware with zero per-token billing.
- Built on .NET 10 and bundled llama.cpp, it installs with a single command that auto-detects GPU, CPU, or Apple Silicon.
- Ships with 20 built-in tools, a 12-step execution pipeline, Docker sandbox, and doom-loop detection.
- Includes 5 specialist sub-agents (Explore, Plan, Coder, Verify, general-purpose) with locked tool sets.
- Supports distributed inference across two machines and a VS Code / Cursor extension over ACP.
- AGPL-3.0 licensed, currently in public beta, roughly 1.7k stars on GitHub.
A new entrant in the local-first coding agent space is picking up traction on GitHub. OpenMono is a terminal-native coding agent built on C#/.NET that runs the model, the tools, and the sandbox entirely on your own hardware. The pitch is blunt: no subscriptions, no data leaving your network, no per-token billing. After the one-time install, every token you burn is free.
The project sits in public beta under the AGPL-3.0 license and installs with a single curl-piped bash command that auto-detects whether you have an NVIDIA GPU, a CPU-only box, or Apple Silicon, then pulls the right model and Docker containers for your setup.
What you actually get
Under the hood, a .NET 10 CLI is paired with a bundled llama.cpp inference server, giving you a full agentic loop with 20 built-in tools, Docker sandboxing, and deep code intelligence. Your project directory bind-mounts into the container as /workspace, and that mount is the entire blast radius the agent can touch.
Performance is respectable for a local setup:
- GPU Qwen3.6-27B dense: ~60 tok/s
- CPU Qwen3.6-35B-A3B MoE: ~20 tok/s