
Open-Source Company Research Agent Hits 2,000 Stars Automating Hours of Due Diligence
A fully open-source multi-agent pipeline that turns a company name into a structured due-diligence report, powered by LangGraph, Tavily, Gemini 2.5 Flash, and GPT-5.1
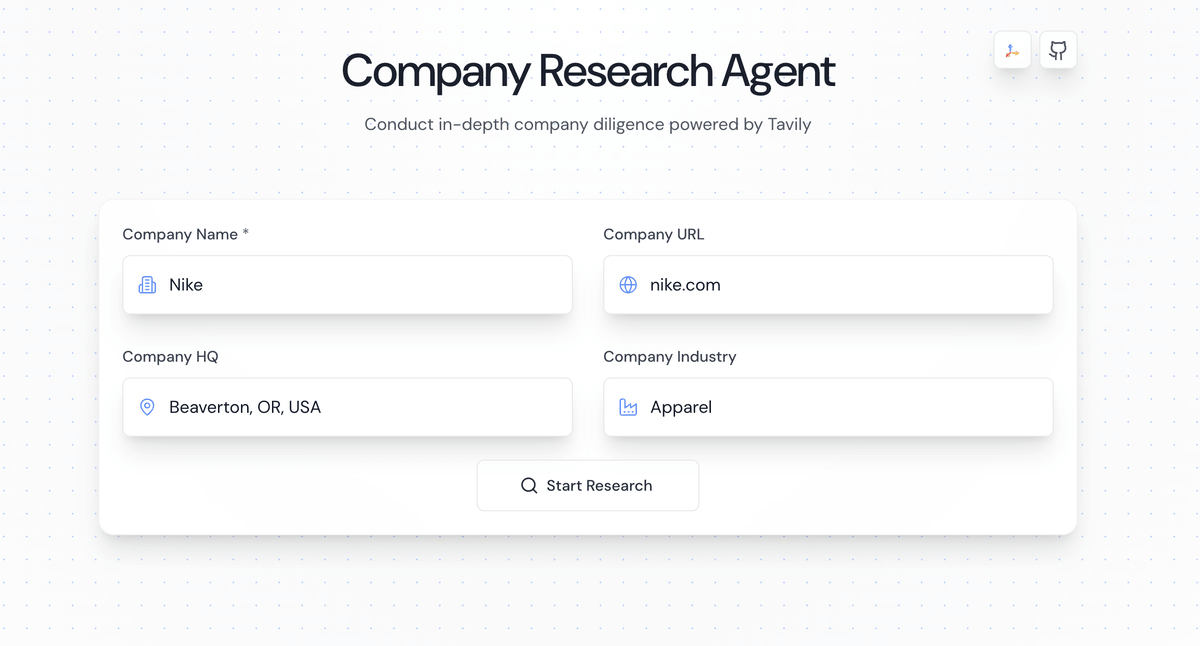
Takeaways
- What it is: Open-source multi-agent pipeline that auto-generates company due-diligence reports using LangGraph, Tavily, Gemini 2.5 Flash, and GPT-5.1.
- Architecture: Four parallel research agents (company, industry, financial, news) feed into curator, briefing, and editor nodes for a clean final report.
- Dual-model design: Gemini 2.5 Flash handles large-context synthesis; GPT-5.1 handles precise formatting and real-time streaming to the frontend.
- Live demo available: Try it at companyresearcher.tavily.com without any setup; self-host via Docker with four API keys.
- Relevance filtering: Tavily scores every retrieved document; anything below 0.4 relevance is dropped before reaching the LLM to reduce hallucinations.
- Traction: 2,000+ GitHub stars, 286 forks, Apache 2.0 license; repo here.
Company Research Agent is an open-source tool that automates the kind of company due diligence that normally takes an analyst hours to assemble. You give it a company name, and a pipeline of specialized AI agents fans out across the web, gathers financial data, news, industry context, and core business information, then synthesizes everything into a structured Markdown report you can download as a PDF. It has crossed 2,000 GitHub stars and 286 forks, with a live hosted demo at companyresearcher.tavily.com you can try right now without setting anything up.
The problem it actually solves
Getting a solid read on a company used to mean stitching together browser tabs: the company website, Crunchbase, recent news, earnings calls, and industry reports. That process is slow, inconsistent, and hard to scale. Before agentic search existed, making an agent web-aware required stitching together four or five tools: a SERP API to get URLs, a scraper to fetch pages, a parser to extract text, a chunker to fit context windows, and maybe an embedding step for relevance filtering. This project collapses all of that into a single automated workflow.
How the pipeline is wired together
The tool is powered by LangGraph and Tavily and conducts deep diligence on companies using a multi-agent framework. LangGraph is a Python library for building stateful, multi-actor applications with LLMs, extending LangChain with the ability to coordinate multiple chains across multiple steps of computation. The pipeline is broken into two stages: research and processing.