
Meta and CMU's MapAnything Replaces 12 Separate 3D Vision Tools With One Model
Meta and CMU released a single transformer that handles 12+ metric 3D reconstruction tasks from any mix of images, poses, depth, and calibration inputs.
 Pro
Takeaways
- Meta and CMU released MapAnything, a feed-forward transformer for universal metric 3D reconstruction.
- A single model handles 12+ tasks: SfM, MVS, depth estimation, depth completion, and localization.
- Accepts any mix of images, intrinsics, poses, and depth as per-view inputs.
- Two checkpoints on Hugging Face: a CC-BY-NC version and an Apache 2.0 commercial variant.
- Scales to 2000 views on 140 GB with memory-efficient mode; code is Apache 2.0.
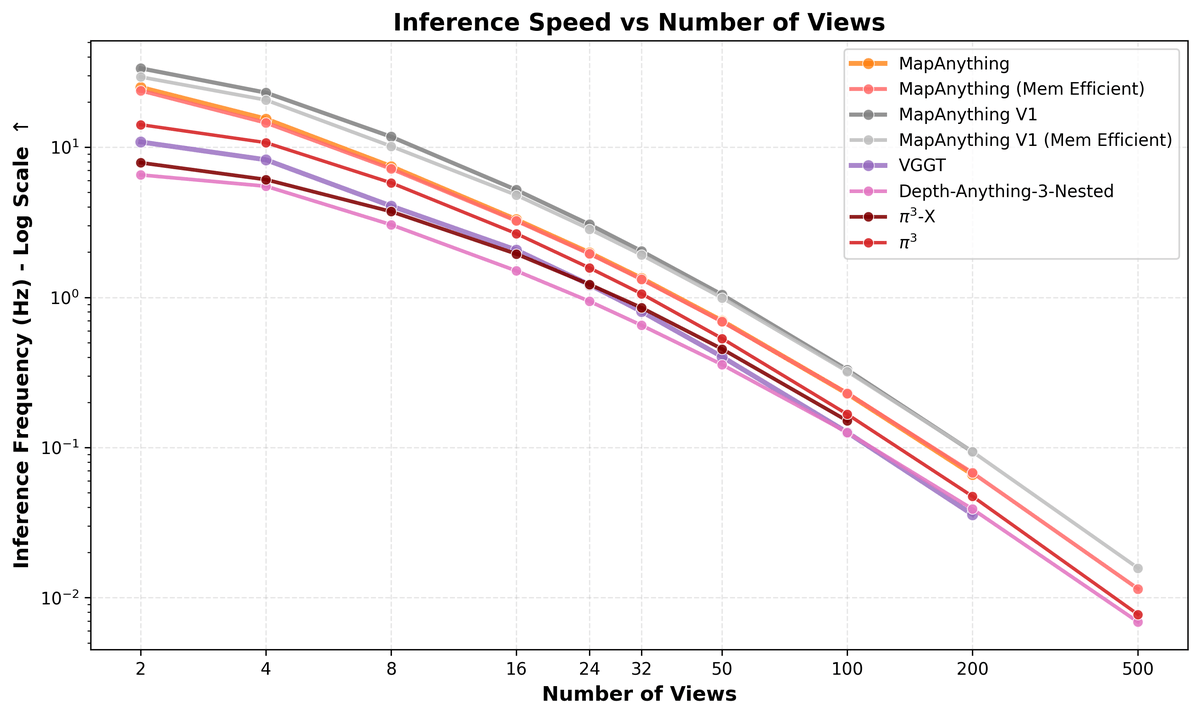
- Modular framework wraps VGGT, DUSt3R, MASt3R, Pi3, and Depth Anything 3 behind one API.
Meta Reality Labs and Carnegie Mellon have released a research framework that collapses a dozen classical 3D vision pipelines into one feed-forward transformer. MapAnything takes any combination of images, camera intrinsics, poses, or depth maps and directly regresses a metric-scale 3D reconstruction of the scene, along with recovered camera parameters. The code is Apache 2.0, two pretrained checkpoints sit on Hugging Face, and there is a hosted demo you can throw pictures at right now.
The paper claims MapAnything matches or beats specialist feed-forward models while offering more efficient joint training behavior, paving the way toward a universal 3D reconstruction backbone. If that holds up in your own tests, the era of one model per 3D task may be ending.

One model, twelve jobs
Traditionally, if you wanted structure-from-motion you reached for COLMAP, if you wanted monocular depth you grabbed a Depth-Anything variant, and if you had calibrated cameras and wanted a dense point cloud you ran multi-view stereo. Each pipeline carried its own assumptions, formats, and failure modes.
MapAnything is an end-to-end trained transformer that directly regresses the factored metric 3D geometry of a scene given various input types (images, calibration, poses, or depth). A single feed-forward pass covers more than 12 reconstruction tasks, including:
- Unconstrained structure-from-motion (just images)
- Calibrated SfM (images plus intrinsics)
- Posed SfM (images plus poses)
- Multi-view stereo (images, intrinsics, and poses)
- RGB-D localization
- Depth completion
- Monocular metric depth estimation
- Single-image camera calibration
The trick: a factored geometry representation
The core design decision is how MapAnything represents a scene internally. Rather than predicting a monolithic point cloud, it decomposes the output into several pieces that can be combined: a collection of depth maps, local ray maps, camera poses, and a metric scale factor that upgrades local reconstructions into a globally consistent metric frame.