
Baidu's PaddleX Ships 270 Open-Source AI Models Into 33 Ready-to-Run Pipelines
PaddleX 3.x is Baidu's open-source all-in-one AI toolkit with 270+ models, 33 ready-to-run pipelines, and SOTA document parsing — all behind a single Python API
Takeaways
- 270+ models, 33 pipelines: PaddleX wraps Baidu's entire AI model catalog into one low-code toolkit accessible via a single Python API.
- SOTA document parsing: PaddleOCR-VL-1.6 hits 96.3% on OmniDocBench v1.6, beating GPT-4o and Gemini on document understanding benchmarks.
- PP-OCRv5 multilingual: 37-language OCR model with 13-point accuracy gain over the previous generation and 30%+ improvement in multilingual scenarios.
- Hardware-agnostic deployment: Supports NVIDIA, Apple M-series, Huawei Ascend, Kunlunxin, Cambricon, and more — critical for Chinese enterprise deployments.
- PDF-to-Markdown pipeline: PP-DocTranslation combines PP-StructureV3 + ERNIE 4.5 Turbo to parse and translate complex PDF layouts into clean Markdown.
- Free and open-source: Apache 2.0 license, Python 3.8–3.13 support, installable via
pip install paddlex[base].
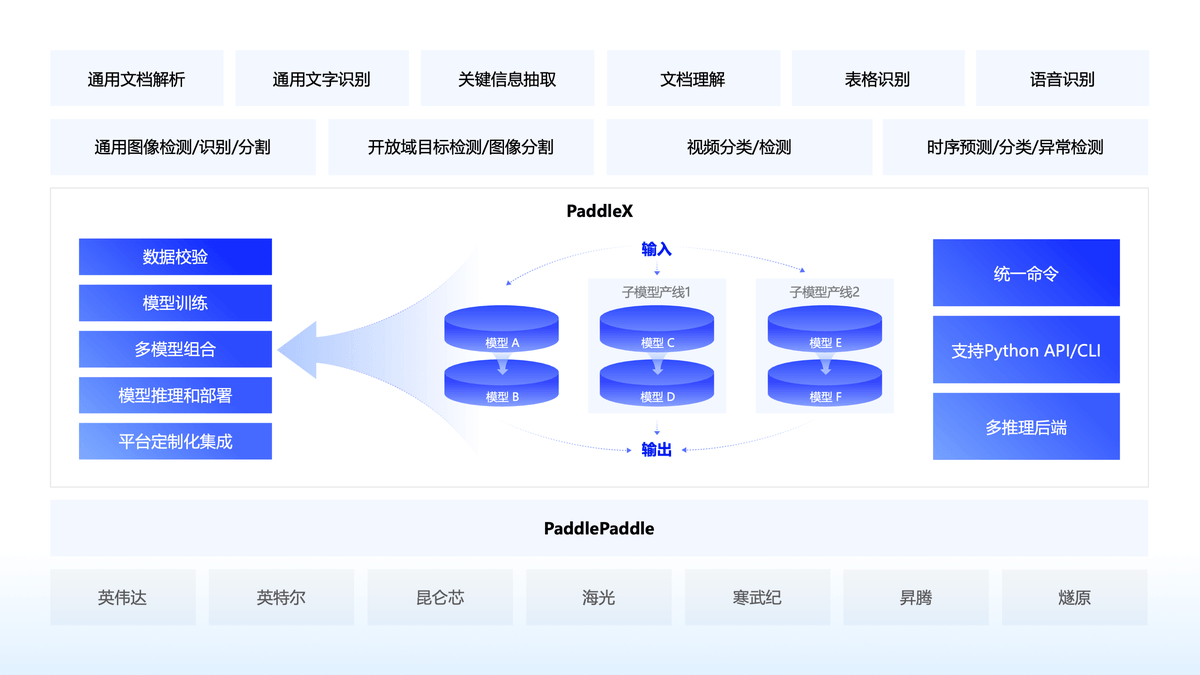
PaddleX is Baidu's open-source, low-code AI development toolkit built on the PaddlePaddle framework. It bundles over 270 pre-trained models into 33 end-to-end pipelines covering OCR, document parsing, object detection, segmentation, time-series analysis, speech recognition, and more. The pitch is simple: go from raw input to production deployment without stitching together a dozen separate libraries.
One API to rule them all
The core design philosophy of PaddleX is the pipeline , a pre-built, composable sequence of models that handles a complete task end-to-end. Over 200 PaddlePaddle models covering OCR, object detection, and time-series forecasting are integrated into 33 pipelines, accessible through easy Python API calls. There are also 39 standalone modules for developers who want to mix and match components.
Running a pipeline takes three lines of Python:
from paddlex import create_pipeline
pipeline = create_pipeline(pipeline="OCR")
output = pipeline.predict("invoice.png")
for res in output:
    res.print()
    res.save_to_json("./output/")
Or from the command line:
paddlex --pipeline OCR \
        --input invoice.png \
        --device gpu:0 \
        --save_path ./output
The document intelligence stack
The headline capability in PaddleX 3.x is its document intelligence suite, built around three flagship models that have been rapidly iterating:
- PP-OCRv5 , a single model that handles five different text types plus complex handwriting, with overall recognition accuracy increased by 13 percentage points over the previous generation. The multilingual version supports training and inference for text recognition in 37 languages including French, Spanish, Portuguese, Russian, and Korean, with average precision increased by over 30%.