
Ant International's RiskWebWorld Exposes How AI Agents Collapse on Real Websites
Ant Group releases a 1,513-task benchmark drawn from real production risk pipelines, exposing a brutal gap between frontier models and specialized GUI agents.
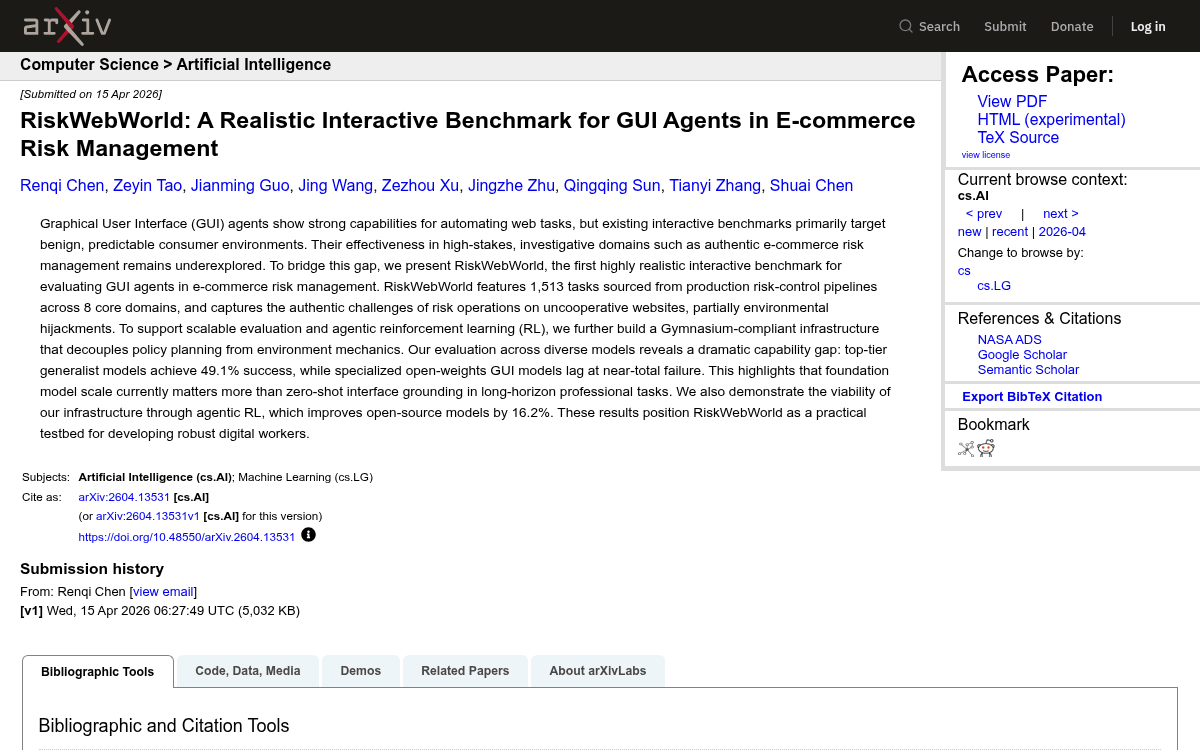
Takeaways
- Ant International releases RiskWebWorld, the first interactive benchmark for GUI agents in e-commerce risk management.
- 1,513 tasks span 8 business domains sourced from real production risk-control pipelines with CAPTCHAs and pop-ups.
- Gemini-3-Pro leads at 49.1% success; GPT-5.2 hits 48.7%; specialized GUI models like UI-TARS-72B score 0%.
- Foundation model scale matters more than zero-shot interface grounding for long-horizon professional web tasks.
- Gymnasium-compliant infrastructure decouples policy from environment, enabling parallel benchmarking and agentic RL training.
- GRPO training in the environment lifts Qwen3-VL-8B by 16.2% and Kimi-VL-A3B by 7.8%.
Most GUI agent benchmarks live in a comfortable world: buy a product, book a flight, fill a form. A team from Ant International just released a benchmark that pushes agents into the opposite kind of environment, where websites refuse to cooperate, pop-ups interrupt flows, and CAPTCHAs guard the data you actually need. RiskWebWorld is billed as the first interactive benchmark tailored for evaluating web agents on e-commerce risk management, and it reveals a much wider capability gap between frontier and specialized models than most public leaderboards suggest.
Why consumer benchmarks miss the point
The team's argument is direct. Current web benchmarks simulate predictable, benign tasks and skip the messier reality of commercial risk operations. Authentic risk analysis introduces severe domain-specific hurdles: agents must gather scattered heterogeneous data across multiple websites to uncover deeply hidden insights, while simultaneously navigating specialized out-of-distribution interfaces and unpredictable environmental constraints like CAPTCHAs and pop-ups. Existing benchmarks cannot adequately verify the real-world applicability of UI agents.
Risk analysts act as investigators, cross-referencing vessel origins, merchant registrations, payment channels, and customs declarations across websites that were never designed to be scraped. If an agent cannot recover when a page 404s or a cookie banner blocks the DOM, it cannot ship to production.
Inside the 1,513 tasks
RiskWebWorld pulls tasks directly from an internal production pipeline at Ant, then filters aggressively for uniqueness, time-invariance, and GUI-agent compatibility. The benchmark splits into two subsets:
- RiskWebWorld-Standard (1,070 tasks): regular production settings, with some items including a human-authored standard operating procedure (SOP) as a reference.
- RiskWebWorld-Challenge (443 tasks): no executable SOPs are available, requiring stronger long-horizon reasoning and exploration from the agent.