

Unsloth Shrinks Baidu's ERNIE-Image-Turbo to 3 GB for Consumer GPUs
Unsloth's GGUF quantizations shrink Baidu's 8B ERNIE-Image-Turbo down to 3GB, letting the 8-step diffusion model run comfortably on consumer GPUs.
 PRO
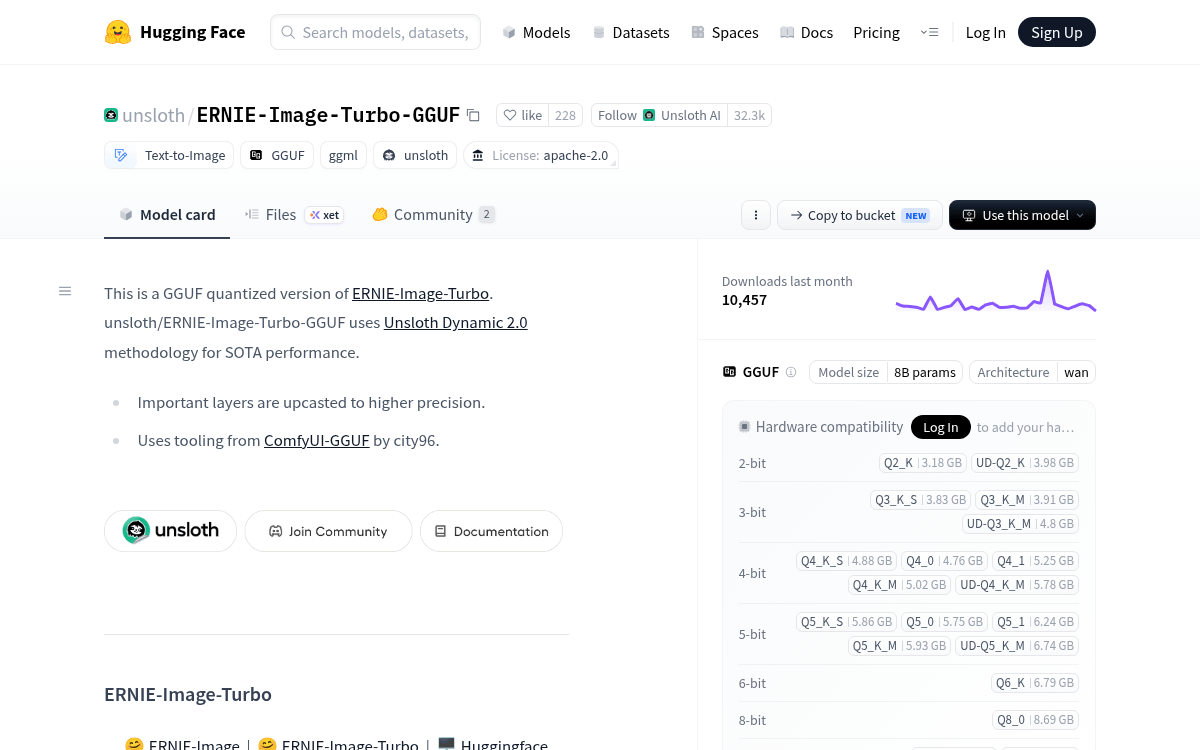
- Unsloth published GGUF quantizations of Baidu's 8B ERNIE-Image-Turbo, ranging from 3.18 GB to 16.1 GB.
- Base model is a distilled Diffusion Transformer generating high-fidelity images in only 8 inference steps.
- Uses Unsloth Dynamic 2.0 methodology, upcasting important layers to preserve quality under aggressive quantization.
- Strong at text rendering, complex prompts, posters, comics, and multi-panel layouts in English and Chinese.
- Runs on 24 GB consumer GPUs at full precision, much less with the smaller GGUF builds.
- Apache 2.0 licensed, works with ComfyUI via ComfyUI-GGUF tooling.
Baidu's ERNIE-Image-Turbo just got a lot easier to run locally. Unsloth has published a full set of GGUF quantizations on Hugging Face, ranging from a 3.18 GB Q2_K build up to the 16.1 GB BF16 weights, along with Dynamic 2.0 mixed-precision variants. If you want a text-to-image model that can render legible text, follow long prompts, and fit on a single consumer GPU, this release makes that practical.
What ERNIE-Image-Turbo actually is
ERNIE-Image-Turbo is an open text-to-image model from the ERNIE-Image team at Baidu, built as the distilled release of ERNIE-Image on the same single-stream Diffusion Transformer (DiT) family. The base is an 8B DiT that reaches state-of-the-art performance among open-weight text-to-image models, and the Turbo variant was distilled with Distribution Matching Distillation and reinforcement learning to produce comparable images in 8 steps instead of the 50 that the full model needs.
Distribution Matching Distillation (DMD) is worth unpacking. Rather than teaching a small student to copy every intermediate denoising step from the teacher, it trains the student so that the distribution of its outputs matches the teacher's. That is what lets Turbo skip from 50 steps to 8 without an obvious quality cliff.
This story is for Pro members
You've reached the end of the free preview. Upgrade to AlphaSignal Pro to read the full article - and everything else behind the paywall.
Comments
