

Unsloth's Qwen3.5-4B Doubles Token Speed Without Changing a Single Weight
Unsloth published GGUF quants of Qwen3.5-4B with multi-token prediction baked in, delivering roughly 1.5x to 2x faster local generation through llama.cpp.
 PRO
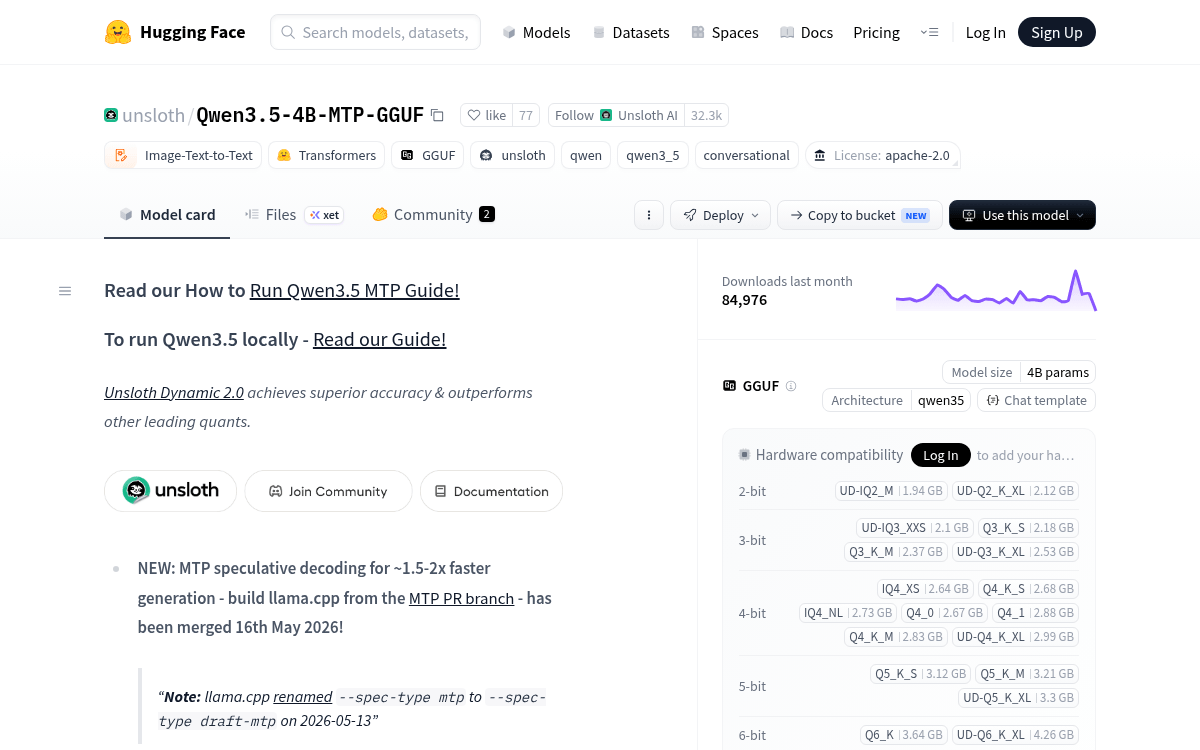
- Unsloth released Qwen3.5-4B-MTP-GGUF with multi-token prediction speculative decoding for local inference.
- Delivers roughly 1.5x to 2x faster generation with no accuracy loss versus the baseline.
- Requires llama.cpp built from source using the new
--spec-type draft-mtpflag. - Model is 4B params, vision-language capable, Apache 2.0, with 262K native context extendable to 1M.
- Quants range from 1.94 GB (UD-IQ2_M) to 8.67 GB (BF16); UD-Q4_K_XL is the recommended default.
- Parallel batching and multimodal projector are not yet compatible with MTP mode in llama.cpp.
Unsloth has shipped Qwen3.5-4B-MTP-GGUF, a set of quantized builds of Alibaba's 4B vision-language model that ship with a multi-token prediction head wired up for speculative decoding. The practical payoff: llama.cpp can now generate output for this model noticeably faster on the same hardware, without changing the weights the main model uses for its final answers.
Where the speedup comes from
Multi-token prediction (MTP) is a small auxiliary head trained alongside the main transformer to guess the next few tokens in one shot. The head proposes several future tokens, then the main model verifies them in parallel, cutting the number of forward passes needed during generation. Accepted guesses yield multiple tokens per decode step for the price of one; wrong guesses fall back to standard decoding. Qwen built the MTP path directly into Qwen3.5, so this is a first-class feature of the model rather than a bolt-on draft.
Unsloth's release note quantifies the gain at roughly 1.5x to 2x faster generation, and the underlying llama.cpp support has now been merged into the main branch. That lines up with what the same team has reported for related Qwen models, where MTP speculative decoding delivers 1.4-2.2x throughput with no change in accuracy, which matters most for local models where every token per second counts.
This story is for Pro members
You've reached the end of the free preview. Upgrade to AlphaSignal Pro to read the full article - and everything else behind the paywall.
Comments
