

Unsloth Brings MiniMax-M2.7's 230B Coding Agent to a Single Mac
Unsloth's Dynamic 2.0 GGUFs shrink MiniMax-M2.7 from 457GB to 108GB, making the 230B agentic coding model run on a single 128GB Mac.
 PRO
- Unsloth released Dynamic 2.0 GGUFs of MiniMax-M2.7, a 230B MoE with 10B active parameters.
- 4-bit UD-IQ4_XS quant is 108GB, runs on a 128GB Mac at 15+ tokens/s.
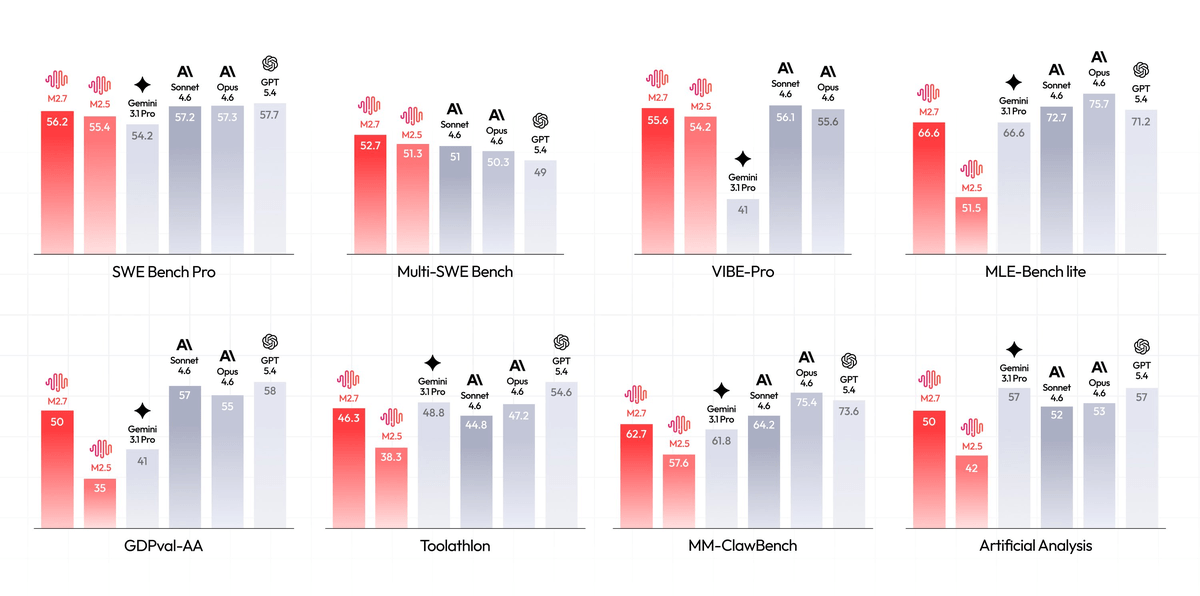
- Benchmarks: 56.22% SWE-Pro, 57.0% Terminal Bench 2, 1495 ELO on GDPval-AA.
- M2.7 introduces self-evolution: model tuned its own coding scaffold for 30% gain.
- Unsloth fixed NaN overflow bugs affecting 21-38% of community GGUF uploads.
- Do not run on CUDA 13.2, NVIDIA is investigating a gibberish-output bug.
MiniMax's newest agentic coding model is now runnable on a single high-memory workstation. Unsloth has published GGUF quantizations of MiniMax-M2.7, a 230B-parameter mixture-of-experts model that was previously out of reach for anyone without a serious GPU cluster. The 4-bit dynamic quant fits in 108GB, so the model runs on a 128GB unified-memory Mac or a modest GPU-plus-RAM combo.
MiniMax-M2 packs 230 billion total parameters but activates only 10 billion at a time, keeping inference fast and cheap while preserving general intelligence. That tiny active footprint is what makes end-to-end tool use viable at this scale. M2.7 is the latest iteration in the series, and MiniMax pitches it as their first model deeply participating in its own evolution, capable of building complex agent harnesses and completing elaborate productivity tasks using Agent Teams, complex Skills, and dynamic tool search.
Benchmarks that actually matter here
M2.7 targets software engineering and office-style productivity rather than open-ended chat. On coding evals, it hits SWE-Pro at 56.22% and Terminal Bench 2 at 57.0%, with additional strong results on SWE Multilingual (76.5) and Multi SWE Bench (52.7). For agentic office work, it scores an ELO of 1495 on GDPval-AA, which MiniMax claims is the highest among open-source models, and maintains a 97% skill adherence rate while working with over 40 complex skills, each exceeding 2,000 tokens.
This story is for Pro members
You've reached the end of the free preview. Upgrade to AlphaSignal Pro to read the full article - and everything else behind the paywall.
Comments
