

Together AI's ParallelKernelBench Reveals Frontier Models Struggle Across Multi-GPU Clusters
Together AI's ParallelKernelBench reveals frontier LLMs solve under a third of 87 real multi-GPU kernel tasks, but occasionally beat every public implementation
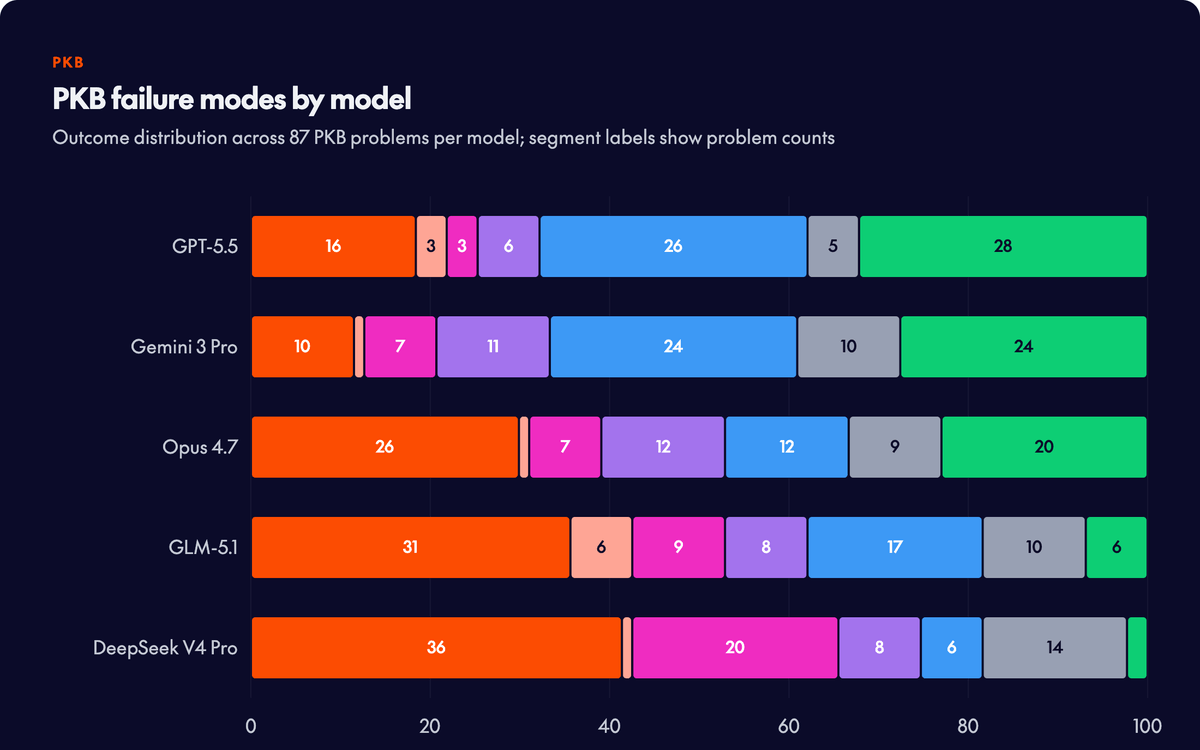
- ParallelKernelBench (PKB) is a new open benchmark of 87 real multi-GPU kernel problems from Megatron-LM, DeepSpeed, NeMo-RL, and others.
- The best frontier model (GPT-5.5) solves only 28/87 problems zero-shot, with 22 beating the PyTorch + NCCL baseline.
- An agentic loop (compile, test, revise) helps Gemini 3 Pro reach 35/87 but plateaus after ~20 steps -- feedback fixes syntax, not rank coordination logic.
- Strong reasoning models compile cleanly but return wrong answers; the hard part is collective ordering and data partitioning, not CUDA syntax.
- Models occasionally generate net-new kernels with no public reference -- one GEMM + All-Gather kernel ran in 87.9µs vs 320.6µs for NCCL.
- Code, problems, and paper are fully open: GitHub, HuggingFace, paper.
LLMs have gotten surprisingly good at writing GPU kernels. Benchmarks like KernelBench have tracked steady progress on single-GPU CUDA generation, and the research community has taken notice. But there is a catch: almost all current benchmarks measuring that progress are single-GPU. In production, models span dozens of GPUs, and the bottleneck is not compute anymore.
Communication overhead can account for over 20% of inference latency, and that gap keeps widening as compute scales faster than interconnect bandwidth. To measure whether LLMs can actually handle that reality, researchers at Together AI built ParallelKernelBench (PKB) -- a benchmark of 87 real-world multi-GPU kernel problems. The verdict: frontier models are not there yet, but a few surprising wins hint at what is coming.
Why multi-GPU is a fundamentally different problem
Writing a fast single-GPU kernel is hard. Writing a fast multi-GPU kernel is a different category of hard. The design space expands combinatorially as practitioners compose tensor, expert, data, context, and sequence parallelism. The performance model changes -- a single-GPU roofline is built around compute and memory bandwidth, but in multi-GPU code, the bottleneck is often the interconnect. And there is a critical new design choice: how to move data between GPUs -- through the copy engine, TMA, SM load/store, or NVLS -- and whether to fuse that movement with compute.
NCCL (NVIDIA Collective Communications Library) is the standard tool for this today. It handles collectives like all-reduce and all-gather across GPUs, but it operates at a high level of abstraction. Reducing communication overheads for small message sizes in the decode phase is important, particularly if data dependencies prevent compute-communication overlap. Collective algorithms optimized for higher throughput and larger message sizes do not scale well to smaller communication payloads. These algorithms can be tuned through custom implementation kernels, which enable fusing or interleaving communication chunks with compute. That is exactly what PKB asks models to do.
The benchmark: 87 problems from real codebases
PKB offers a benchmark and evaluation framework for multi-GPU kernel generation. Each problem starts from a standard PyTorch + NCCL implementation and a description of the hardware topology. The model then has to replace that reference with a CUDA kernel that communicates directly across GPUs using symmetric memory. Symmetric memory here means memory that is simultaneously addressable by multiple GPUs over NVLink -- it lets a kernel on GPU 0 directly read or write GPU 1's memory without going through the OS or a separate copy engine.
To make sure the 87 problems cover the real space of production parallelism types, the team built them from a taxonomy of distributed workloads, identifying the major ways models get sharded -- tensor, context, data, expert, sequence, and FSDP/ZeRO -- along with the communication patterns each one creates. The problems were pulled from:
- Megatron-LM (tensor and pipeline parallelism)
- DeepSpeed and DeepEP (expert parallelism, ZeRO)
- TensorRT-LLM and NeMo-RL (production inference and RL training)
- Non-LLM workloads: GNN routing, distributed FFTs, Gaussian splatting
Because PKB references are written in standard PyTorch + NCCL, the benchmark is not tied to any single hardware generation and is designed to naturally evolve alongside next-generation hardware architectures. The benchmark also accepts solutions in Triton and ParallelKittens, not just raw CUDA.
How the evaluation pipeline works
Each PKB task follows a structured pipeline:
- The model receives a task description, hardware topology (e.g., 4x H100 connected via NVLink), and the PyTorch + NCCL reference implementation.
- It generates a custom CUDA (or Triton) kernel that bypasses NCCL and communicates directly using symmetric memory.
- The kernel is compiled, run against randomized inputs across multiple ranks, and compared to the reference for correctness.
- If correct, wall-clock speedup is measured against the PyTorch + NCCL baseline using rigorous benchmarking: 500 warmup iterations and 100 timed iterations.
- Performance is also compared against a communication-aware roofline -- the theoretical NVLink ceiling -- to show how much headroom remains.
The primary metrics are pass@k (fraction of problems solved correctly in k attempts) and fast1@k (fraction of problems where at least one of k attempts is both correct and faster than the NCCL baseline). Before evaluating models, the team first checked whether the PyTorch + NCCL baselines leave real headroom. A communication-aware roofline confirms yes: most PKB problems are bottlenecked by NVLink, and the baselines run far below the hardware ceiling.
Frontier models struggle
In the zero-shot setting, the best model solves 28 of 87 problems, and only 22 of those solutions are faster than the PyTorch + NCCL baseline. Sampling three attempts improves the best result to 36 correct solutions and 27 faster-than-baseline solutions, but fast1@3 still tops out at 31%.
| Model | pass@1 | pass@3 | fast1@1 | fast1@3 |
|---|---|---|---|---|
| GPT-5.5 | 28/87 | 36/87 | 22/87 | 27/87 |
| Claude Opus 4.7 | 20/87 | 31/87 | 12/87 | 20/87 |
| Gemini 3 Pro | 24/87 | 30/87 | 12/87 | 19/87 |
| GLM-5.1 | 6/87 | 7/87 | 2/87 | 3/87 |
| DeepSeek V4 Pro | 2/87 | 3/87 | 0/87 | 1/87 |
The successes are concentrated in familiar patterns: collective primitives, tensor-parallel GEMMs, and Ulysses-style context parallelism. These are the parts of the multi-GPU stack most visible in open-source code, so models likely have stronger priors for them.
The failures suggest a deeper issue than CUDA syntax. Weaker models often fail to compile, but stronger reasoning models frequently produce kernels that compile and return incorrect results. The hard part is reasoning about rank coordination, data partitioning, and collective ordering.
Generated kernels also use a very narrow set of communication mechanisms. Most rely on copy engines or SM load/store instructions, while more specialized mechanisms such as TMA and NVLS are almost absent. In many cases, models do not choose the mechanism needed for peak performance. TMA (Tensor Memory Accelerator) is a hardware unit on Hopper GPUs for asynchronous bulk memory copies; NVLS (NVLink SHARP) is a collective operation that runs directly on the NVLink switch fabric, bypassing GPU SMs entirely. Both are critical for peak performance and both are nearly invisible in the training data.
Does an agentic loop help?
The natural fix is to give the model a feedback loop -- the same compile-test-profile cycle a human kernel engineer would use. The team wrapped Gemini 3 Pro in an agentic harness with access to the repository, a terminal, compiler output, correctness tests, speed measurements, and its previous attempts. Instead of producing one kernel and stopping, the model could compile, run the benchmark, inspect failures, and revise.
This helped, but the practical gains are modest. Gemini 3 Pro improved from 24 correct solutions in the single-shot setting to 35 out of 87, with 26 kernels beating the PyTorch + NCCL baseline. The gains came from fixing syntax errors, shape mistakes, and simple runtime bugs. After roughly 20 refinement steps, performance plateaued.
The ceiling is not compilation errors. Feedback helps models debug distributed kernels, but the remaining failures highlight a much bigger gap: an inability to reason about rank coordination, communication ordering, and the optimal choice of GPU-to-GPU transfer mechanisms. More iterations do not fix a wrong mental model of how ranks should coordinate.
The surprising wins: net-new kernels
The most striking result is not the failure rate -- it is what happens when models do succeed on hard problems. Single-shot generation occasionally surfaces genuinely new high-performance kernels for workloads with no optimized public reference. Wins are not limited to Transformers, as models can do well on state-space models, genomic pipelines, and multimodal RL loops. Three standout examples:
- NeMo vocab-parallel log-probs (Gemini 3 Pro): A core step in NVIDIA NeMo-RL's GRPO training loop. The generated kernel skips NCCL collectives entirely, using symmetric memory to permute shards inline while fusing log-softmax, token extraction, and target gather into a single warp-shuffle reduction. No prior optimized public implementation existed.
- Hyena context parallelism (GPT-5.5): The reference alternates between sequence- and channel-sharded layouts via repeated all_to_all calls; the generated kernel packs inputs into one symmetric allocation and streams remote slices over NVLink, computing gating and reindexing in a unified pass.
- SAM 3 mask IoU suppression (GPT-5.5): The baseline uses variable-length all_gather collectives plus a dense matmul; the generated solution collapses this into a pipeline of symmetric-memory kernels that bitpack masks and compute pairwise overlap with hardware popcount.
The headline number from the GEMM + All-Gather problem says it all: a generated CUDA kernel ran in 87.9 microseconds versus 320.6 microseconds for the PyTorch + NCCL reference -- a 3.6x speedup -- on a problem with no prior optimized public implementation. The theoretical roofline sits at 4.99 microseconds, so there is still significant room to improve, but the model found something real.
What this means in practice
PKB is most useful as a diagnostic tool right now. If you are building a distributed training or inference system and want to know whether an LLM can help you optimize a specific collective, the benchmark gives you a realistic baseline for expectations. The answer today is: maybe, if the pattern is common (all-reduce, tensor-parallel GEMM, Ulysses attention), and probably not if it involves pipeline parallelism, FSDP, or anything requiring careful rank coordination.
The longer-term implication is more interesting. The broader goal is a concrete target for the harder problem: LLM systems that can autonomously optimize and manage large-scale distributed infrastructure. For infrastructure custom-built for language model training and inference, achieving this autonomy could ultimately bridge the gap to AI agents capable of handling their own end-to-end research engineering.
PKB is intentionally scoped to intra-node NVLink today. The natural extensions are inter-node fabrics -- RoCE, InfiniBand -- where the device-side API landscape is younger, and other accelerators and topologies like TPUs. The team is also interested in whether higher-level abstractions like NCCL GIN and NVSHMEM make the task easier or harder for models.
Getting started
The benchmark code is fully open. You can run evaluations locally with torchrun on any multi-GPU machine, or use Together AI's cloud container service if you do not have an 8xH100 node handy. The problems are also on HuggingFace. A quick local eval looks like this:
# Generate a kernel for problem 1 (allreduce) using GPT-5.5
python kernelgen/generate_kernel.py \
  --precision bf16 \
  --hardware h100_8 \
  --problem 1 \
  --model gpt-5.5 \
  --backend cuda
# Evaluate correctness and speedup vs PyTorch + NCCL
python run_local.py \
  --nproc-per-node 4 \
  --mode eval \
  --problem 1 \
  --dtype bfloat16 \
  --solution cuda \
  --measure-perf
The benchmark is open for contributions, especially inter-node problems involving prefill-decode disaggregation and InfiniBand. The gap between what models can do on a single GPU and what they can do across a cluster is one of the clearest remaining frontiers in AI-assisted systems programming.
Comments
