

Tencent's AngelSlim Squeezes 235B Models onto a Single GPU
Tencent's AngelSlim open-sources a full LLM compression stack covering quantization down to 1.25-bit, Eagle3 speculative decoding, and sparse attention — all in one pip install.
 PRO
- Tencent open-sourced AngelSlim, a unified LLM compression toolkit covering quantization, speculative decoding, sparse attention, and token pruning.
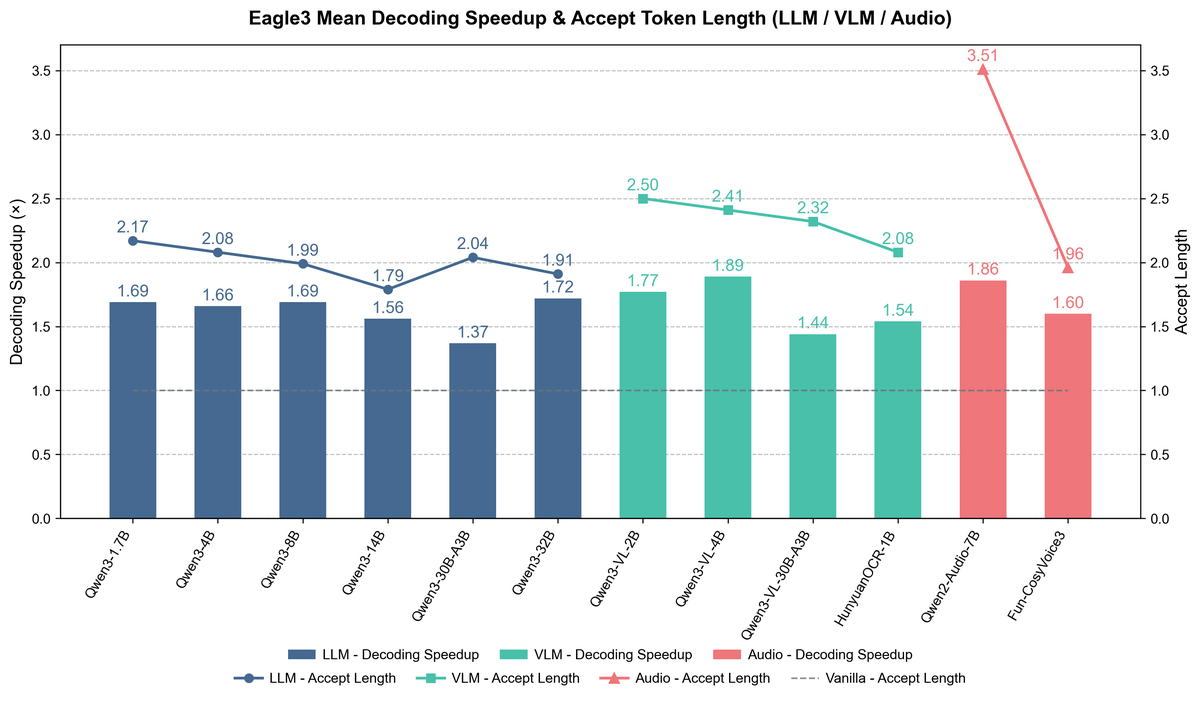
- Eagle3 speculative decoding delivers 1.4–1.9× throughput gains on LLMs, VLMs, and audio models; pre-trained weights available on Hugging Face.
- Quantization spans FP8/INT8/INT4/NVFP4 down to 1.25-bit (Sherry, ACL 2026), enabling Qwen3-235B and DeepSeek-R1 on a single GPU.
- New algorithms ship frequently: Stem (sparse prefill), DFlare (5.52× diffusion speedup), SpecExit (early exit), DAQ, and D-Cut.
- Real-world output: a 440MB on-device translation model covering 33 languages, built with the Sherry 1.25-bit algorithm.
- Install via
pip install angelslim; deploys via vLLM or SGLang; technical report at arXiv:2602.21233.
Squeezing a 235-billion-parameter model onto a single GPU used to require a team of engineers and months of custom work. AngelSlim, the compression toolkit from Tencent's Hunyuan AI Infra team, is trying to make that a one-liner. The project has been iterating rapidly since its initial release, and it now covers the full compression pipeline , quantization, speculative decoding, sparse attention, token pruning, and diffusion model optimization , across LLMs, vision-language models, and audio models.
One toolkit, every compression knob
AngelSlim is a comprehensive toolkit for large model compression developed by the Tencent Hunyuan team, consolidating cutting-edge algorithms including quantization, speculative decoding, token pruning, and distillation into a unified pipeline that streamlines the transition from model compression to industrial-scale deployment. The scope is unusually broad: it supports LLMs, VLMs, diffusion models (image, video, 3D), and speech models (TTS/ASR) under a single API.
The model coverage is similarly wide. Out of the box, AngelSlim supports:
- LLMs: Hunyuan Dense/MoE, Qwen3, DeepSeek-R1/V3, GLM-4.6, Qwen2.5, Kimi-K2
- VLMs: Hunyuan-VL, HunyuanOCR, Qwen3-VL, Qwen2.5-VL
- Diffusion: Hunyuan-Image/Video/3D, FLUX, Wan, SDXL
- Audio: Qwen3-Omni, Qwen2-Audio, Fun-CosyVoice3
Quantization from FP8 down to 1.25-bit
AngelSlim integrates state-of-the-art FP8 and INT8 Post-Training Quantization (PTQ) algorithms alongside pioneering research in ultra-low-bit regimes, featuring HY-1.8B-int2 as the first industrially viable 2-bit large model. The quantization menu spans a wide range of formats:
- FP8-Static / FP8-Dynamic , the workhorse for production deployments
- INT8-Dynamic, INT4-GPTQ, INT4-AWQ, NVFP4 , for aggressive size reduction
- LeptoQuant , a custom FP8 algorithm. LeptoQuant introduces Dynamic Outlier Isolation Scale, observing that weight distributions often follow a Laplacian-like peak with significant outliers, and searches for optimal scaling values to isolate those outliers and preserve the representational fidelity of the original distribution.
This story is for Pro members
You've reached the end of the free preview. Upgrade to AlphaSignal Pro to read the full article - and everything else behind the paywall.
Comments
