

Reka's WorldModelGym Tests If AI World Models Actually Help Agents Win
Reka's WorldModelGym benchmarks world models on what actually matters: do they help agents make better decisions in the real world?
- New benchmark: Reka released WorldModelGym, measuring whether world models help agents make better real-world decisions.
- Decision-based fidelity: Unlike visual benchmarks, it scores world models on whether they correctly rank action sequences by real-world outcome.
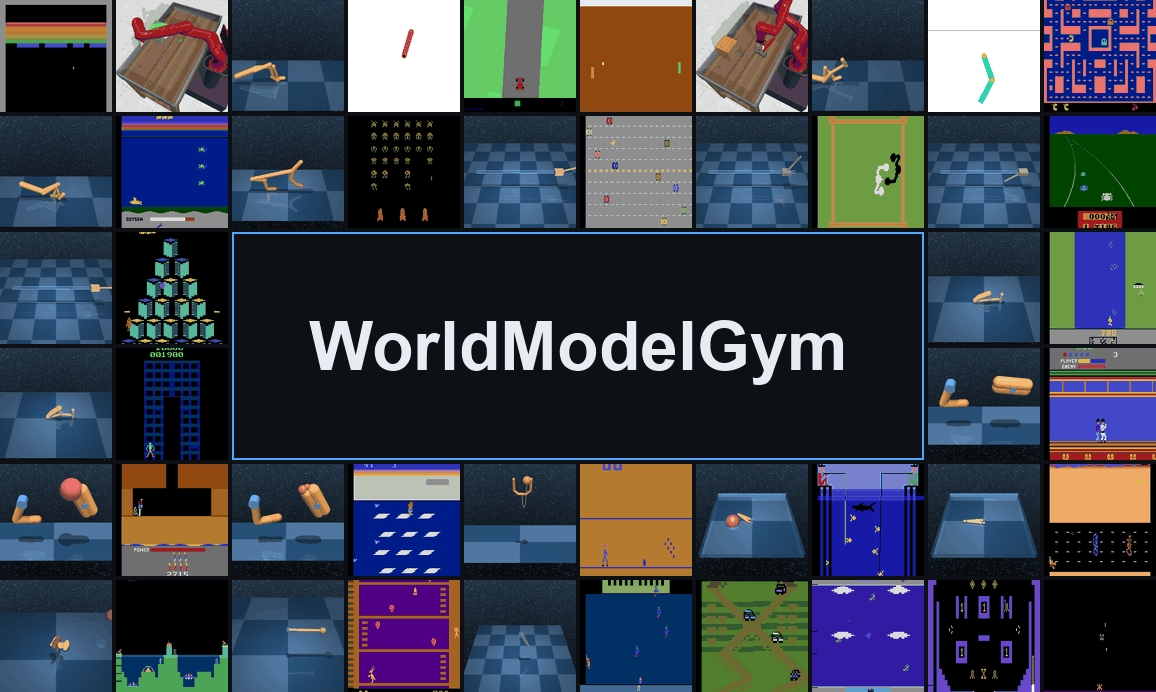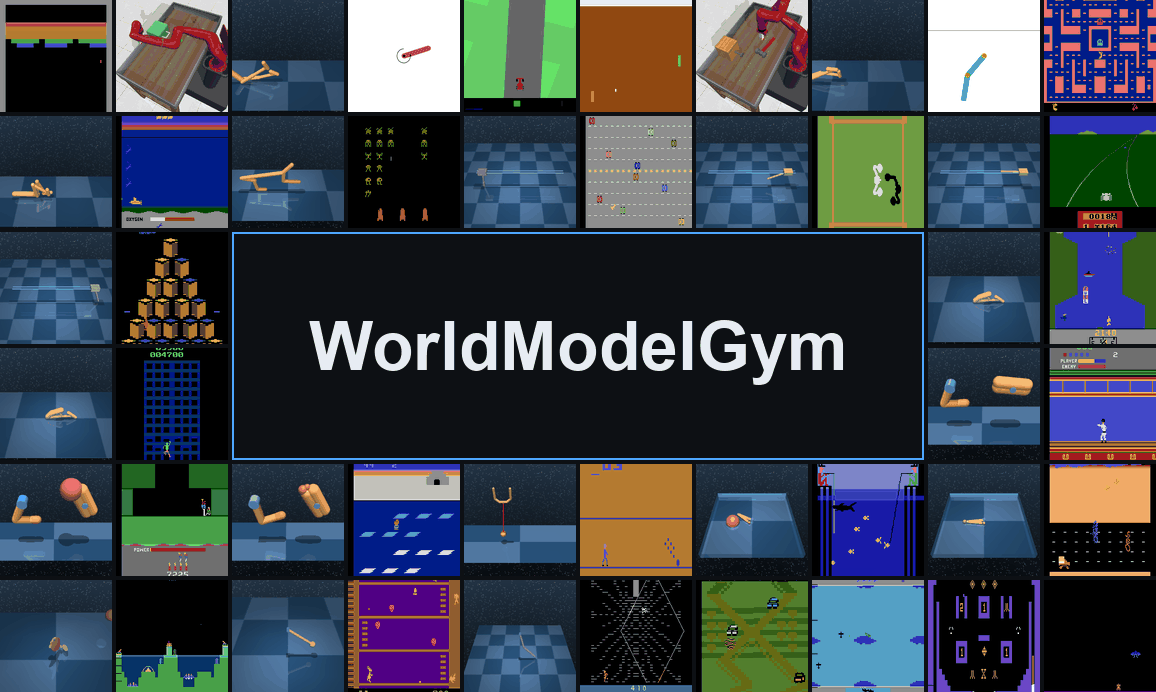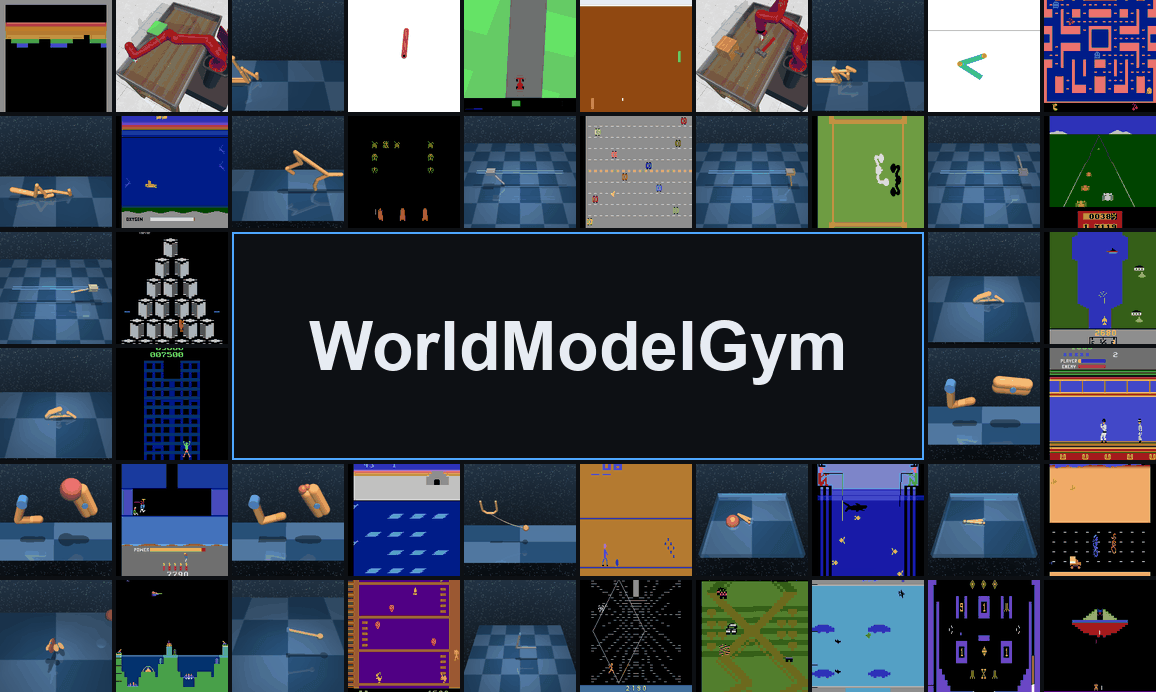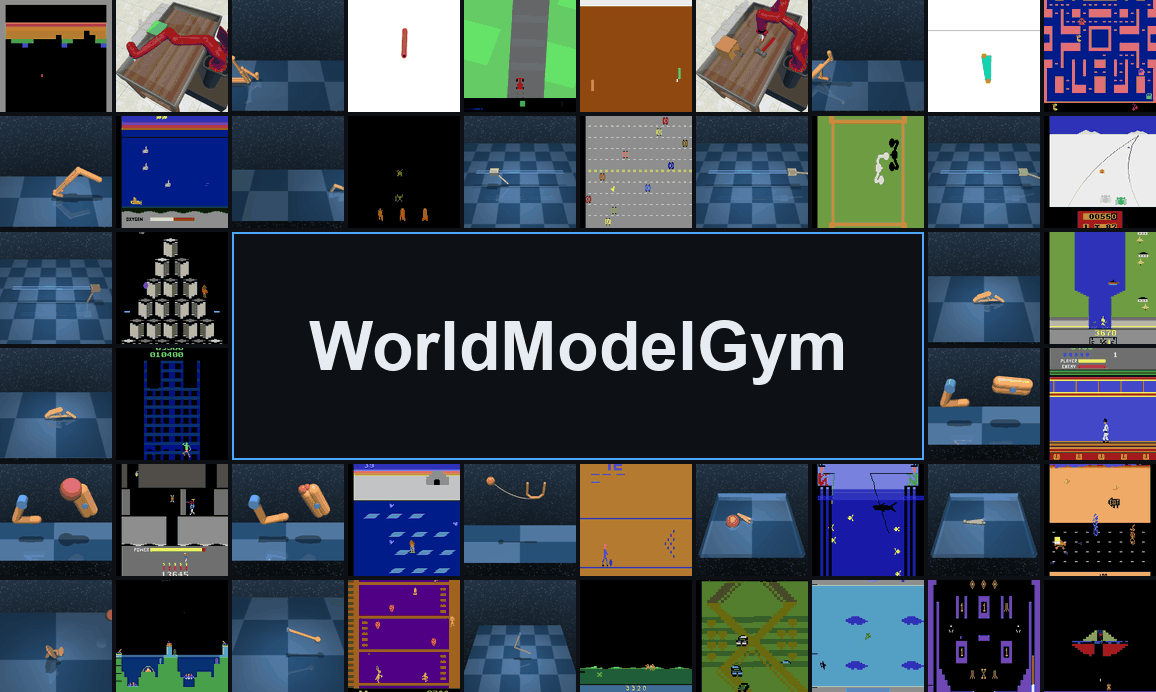
- 100+ tracks: Covers Atari, Meta-World, DeepMind Control, and classic control environments with a standardized evaluation protocol.
- Key metric: Normalized regret (0 = picked the best action, 1 = no better than random) plus reward-prediction error to catch lucky guesses.
- Model-agnostic: Supports latent, pixel-based, and token-based world models via a minimal two-method interface compatible with Gymnasium.
- Free to use: Available now; public leaderboard coming soon, evaluation requests via [email protected].
WorldModelGym is a new benchmark from Reka that asks a deceptively simple question about world models: if an agent uses one to choose between possible actions, does it pick the right one? Not "does it generate realistic-looking video?" or "does it reconstruct the input accurately?" -- just: does it actually help the agent win?
The distinction matters more than it might seem. Most existing world model benchmarks measure visual quality, physical plausibility, or reconstruction accuracy. These benchmarks largely treat world models as video generators and do not assess their functional roles in agent decision-making. WorldModelGym fills that gap with a concept Reka calls decision-based fidelity.
The Gap Nobody Was Measuring
A world model, in the RL sense, is a learned simulator: given a state and an action, it predicts the next state and reward. By unrolling these predictions, the model simulates how the world evolves, effectively allowing the agent to "see" the future. The problem is that a model can look great on perceptual benchmarks while still steering an agent toward terrible decisions -- its errors might cancel out visually but compound catastrophically when used for planning.
WorldModelGym is designed to catch exactly that failure mode. It indirectly evaluates world models through the lens of decision-based fidelity: how useful is the world model in relation to the real world, by measuring the consequence, in the real world, of acting based on the model's predictions.
How the Evaluation Works
The protocol is elegant. Rather than running a full agent rollout (expensive and slow), the benchmark presents a world model with a multiple-choice test at a critical decision point. For each question, it provides five different choices (action sequences) for the world model, including one random choice. Since all five have already been run in the real environment, the benchmark knows each one's true outcome.
The world model's job is to simulate each sequence and pick the one it predicts will yield the highest reward. The real environment then scores that choice. This is the core insight: you don't need to watch the agent play a full game to know if its world model is useful -- you just need to see if it can rank action sequences correctly at a decision fork.
The headline metric is normalized regret:
normalized_regret = (best_return - true_return_of_picked_sequence)
                    / (best_return - worst_return)
A score of 0 means the model successfully identified the optimal plan, whereas a score of 1 represents performance no better than the worst choice. There's also a secondary metric -- reward-prediction error -- which checks whether the model's predicted reward numbers were actually accurate, not just lucky. This separates models that make good decisions through genuine understanding from those that get the right answer by coincidence.

What It Covers
WorldModelGym launches with 100+ tracks across multiple environment families including Atari games, Meta-World manipulation tasks, DeepMind Control tasks, and classic control. The environment selection was deliberate -- not every good RL task makes a good world-model benchmark. The suite prioritizes environments with fixed observation windows, reproducible resets, and horizons long enough for prediction errors to compound meaningfully.
The benchmark supports all major world model architectures through a single standardized interface. Because the state representation is treated as an opaque object by the evaluator, the model can use any format (e.g. JEPA-style latent vectors, tokens, or video world models in pixels), making the protocol highly flexible. The only requirement is that the model can predict rewards and support branching from a frozen state to evaluate multiple plans.
The API contract is minimal:
class WorldModel:
    def init(self, obs_history, context=None):  # encode history into a state
    def step(self, state, action):              # predict next state and reward
What It Won't Tell You
Reka is upfront about the limitations. WorldModelGym focuses on decision-relevant accuracy. It does not judge how realistic a model's imagined frames look, which is a separate perceptual question. It does not capture the long-horizon, closed-loop behavior a deployed agent would face, since the test is open-loop. Think of it as a targeted probe, not a complete evaluation suite -- it's designed to complement existing benchmarks, not replace them.
The Bigger Picture at Reka
This release fits into a broader research push at Reka. The company has expanded beyond foundation models into product offerings such as Reka Nexus, Reka Vision, and Reka Research, and in June 2026 it merged with the physical-AI startup Moonvalley to push into world models and robotics. The merger brought a team of former DeepMind, Meta, Amazon, Microsoft, Google, Wayve, and Runway researchers to Reka, including key contributors to models that became Google's Veo.
WorldModelGym sits alongside Reka's PhysicalRealismBench, which tests whether vision-language models can spot physics violations in video. The two benchmarks are complementary: one asks if a model understands the physical world, the other asks if it can simulate it well enough to act in it. PhysicalRealismBench asked frontier VLMs to detect basic physics violations in synthetic video -- objects vanishing, passing through walls, floating without support. Nine frontier models were tested, and the best scored only 57.7%.
Who Should Care
If you're building or evaluating world models for any of the following, this benchmark is directly relevant:
- Model-based RL -- latent dynamics models like DreamerV3 or TD-MPC2 can plug in directly via the adapter interface
- Robotics simulation -- manipulation tasks from Meta-World test whether a world model can guide a robot arm through precise sequences
- Game AI -- Atari tracks provide a familiar, well-understood testbed for measuring planning quality
- World model research -- the two-metric design (normalized regret + reward-prediction error) gives a cleaner signal than perceptual benchmarks alone
If your world model can encode an observation history, take an action, and predict the resulting reward, it can be scored. Each track ships its questions and answers, its menus, and the precomputed true returns; a submission is graded by normalized regret across the suite. The benchmark is available now, with a public leaderboard coming soon. For early evaluation access, Reka can be reached at [email protected].
The field has spent years getting better at making world models look good. WorldModelGym is a push to make them actually useful.
Comments
