

Qwen3.8 Hits 49 Tokens per Second on AMD's Budget APU
A community quantization pairs a 27B Qwen model with multi-token prediction and AMD's IU4 matrix path, hitting ~49 tokens per second on a single Strix Halo APU.

 PRO
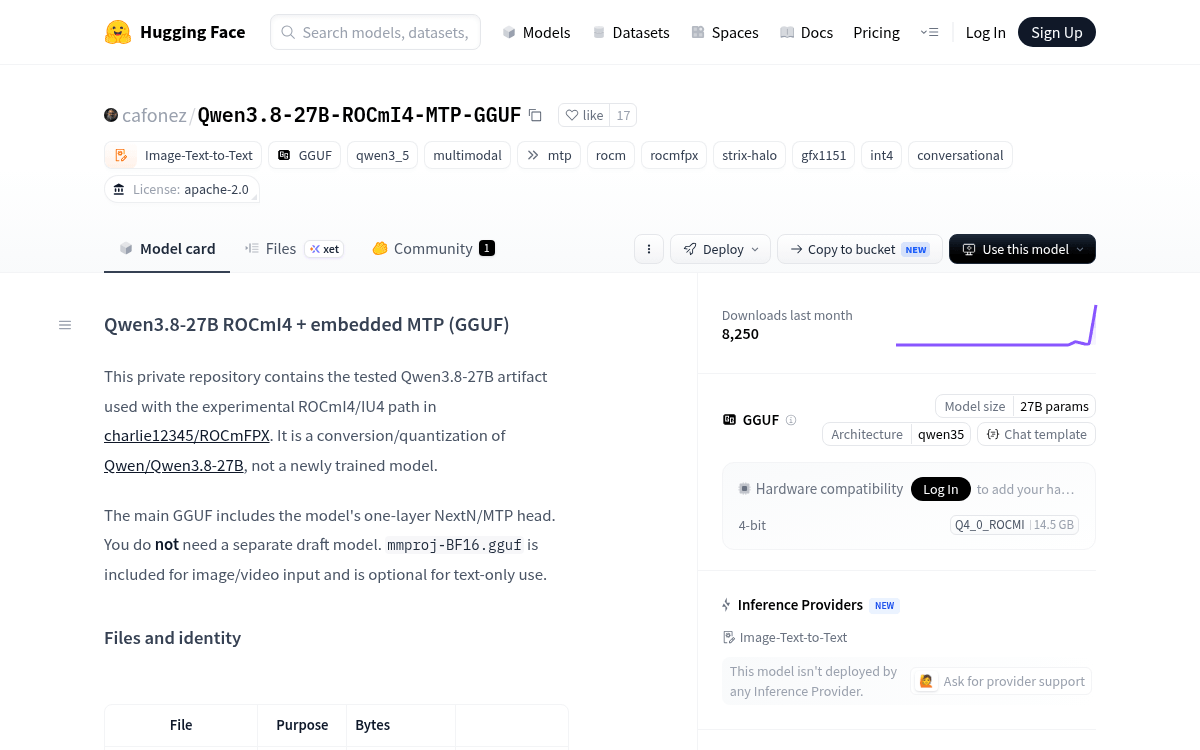
- Qwen3.8-27B-ROCmI4-MTP-GGUF hits ~49 tok/s on Strix Halo using W4A4 IU4 plus embedded MTP.
- Uses a custom Q4_0_ROCMI4 weight format not readable by stock llama.cpp.
- Requires the ROCmFPX fork pinned to a specific commit, HIP-only build.
- Reports 94.5% HumanEval pass@1 with speculative decoding enabled.
- Perplexity rises ~6% versus Q4_K_M reference; W4A4 adds ~5.4% more.
- Apache 2.0 license, includes optional BF16 multimodal projector for image input.
A community upload on Hugging Face is drawing attention from people trying to squeeze real throughput out of AMD's Strix Halo APUs. The Qwen3.8-27B-ROCmI4-MTP-GGUF release bundles a 4-bit quantized 27B model with an embedded speculative decoder, and reports decode speeds around 49 tokens per second on a single Ryzen AI MAX+ 395 with integrated Radeon 8060S graphics.
This is a conversion and quantization of Qwen/Qwen3.8-27B rather than a fresh training run. The main GGUF includes the model's one-layer NextN/MTP head, so no separate draft model is required. The interesting behavior shows up once you feed it into the right runtime.
Why the ROCmI4 label matters
The file uses a custom GGUF weight type called Q4_0_ROCMI4, which stock llama.cpp does not understand. Running it requires the ROCmFPX fork at a specific pinned commit, since neither the custom ROCmI4 type nor the qualified IU4/MTP path exist in mainline builds.
A quick glossary helps here:
- ROCmI4: the GGUF weight format with signed four-bit weight codes packed two per byte with block scales.
- INT4: the generic four-bit integer width.
- IU4: AMD's
v_wmma_i32_16x16x16_iu4matrix instruction on gfx1151. - W4A4: four-bit weights and four-bit activations during accelerated matrix multiplication.
This story is for Pro members
You've reached the end of the free preview. Upgrade to AlphaSignal Pro to read the full article - and everything else behind the paywall.
Comments
