

Qwen3.8-27B Unleashed Hits 83% MMLU Uncensored on a Single 24GB GPU
A per-tensor dynamic quantization of an abliterated Qwen3.8-27B lands on Hugging Face, delivering 82.98% MMLU and 262k context on a single RTX 4090.

 PRO
- Uncensored Qwen3.8-27B GGUF with per-tensor Unsloth Dynamic 3.0 quantization, Apache 2.0.
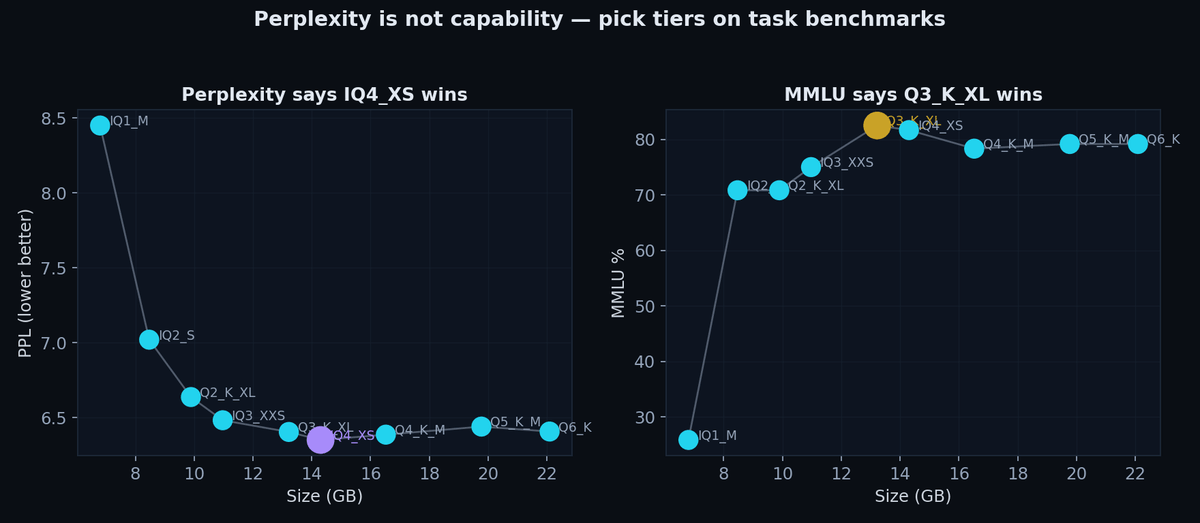
- Recommended UD-Q3_K_XL is 13.2 GB and hits 82.98% MMLU versus 85.3% for stock bf16.
- Full 262,144-token context fits on a single 24 GB RTX 4090 thanks to hybrid DeltaNet (17/65 full-attention layers).
- 0% refusal rate at every usable tier on a 20-prompt boundary battery; abliteration survives 3-bit quantization.
- Bundled vision projector (mmproj-Unleashed-f16.gguf, 0.93 GB) plus optional DFlash2 speculative decoding for ~50% draft acceptance.
- Base weights from JonathanColetti's uncensored fork; IQ1_M tier scored at chance and should be avoided.
A new drop on Hugging Face is turning heads for how carefully it was measured. Qwen3.8-27B-Unleashed-GGUF is an uncensored, dynamically quantized build of Qwen3.8-27B that has already pulled in more than 43,000 downloads. It targets people who want to run a top-tier open model locally, with no refusals, no cloud calls, and the full 262,144-token context window on a single 24 GB GPU.
The base weights come from JonathanColetti/Qwen3.8-27B-Uncensored, an abliterated variant produced with the Heretic method that also re-grafts the multi-token-prediction head. What outsourc-e added is the quantization recipe: the per-tensor quant map was extracted from unsloth/Qwen3.8-27B-GGUF by reading the tensor-type table from their published files, then applied to JonathanColetti's uncensored weights using that repo's imatrix. The result is nine GGUF tiers, all Apache 2.0, ranging from 6.8 GB to 22.1 GB.
Why per-tensor quantization pays off
Most uncensored GGUFs apply the same bit-width uniformly to every layer. This one uses a per-tensor type map derived from Unsloth's Dynamic 3.0 recipe, so sensitive tensors keep precision while tolerant ones compress hard. The clearest evidence sits in the tensor allocation itself: across every tier from IQ1_S to Q8_K_XL, the roughly 96 ssm_alpha and ssm_beta tensors that gate Qwen3.8's DeltaNet path are held at Q8_0, even in the 1-bit builds. A hand-rolled uniform variant scored worse on perplexity than any of the dynamic quants.
This story is for Pro members
You've reached the end of the free preview. Upgrade to AlphaSignal Pro to read the full article - and everything else behind the paywall.
Comments
