

Qwen3.8-27B Uncensored Cyber Build Hits 100% Openness for Security Labs
A 27B Qwen3.8 finetune strips refusals on cybersecurity questions while keeping vision and speculative decoding intact, shipped as llama.cpp quants.
 PRO
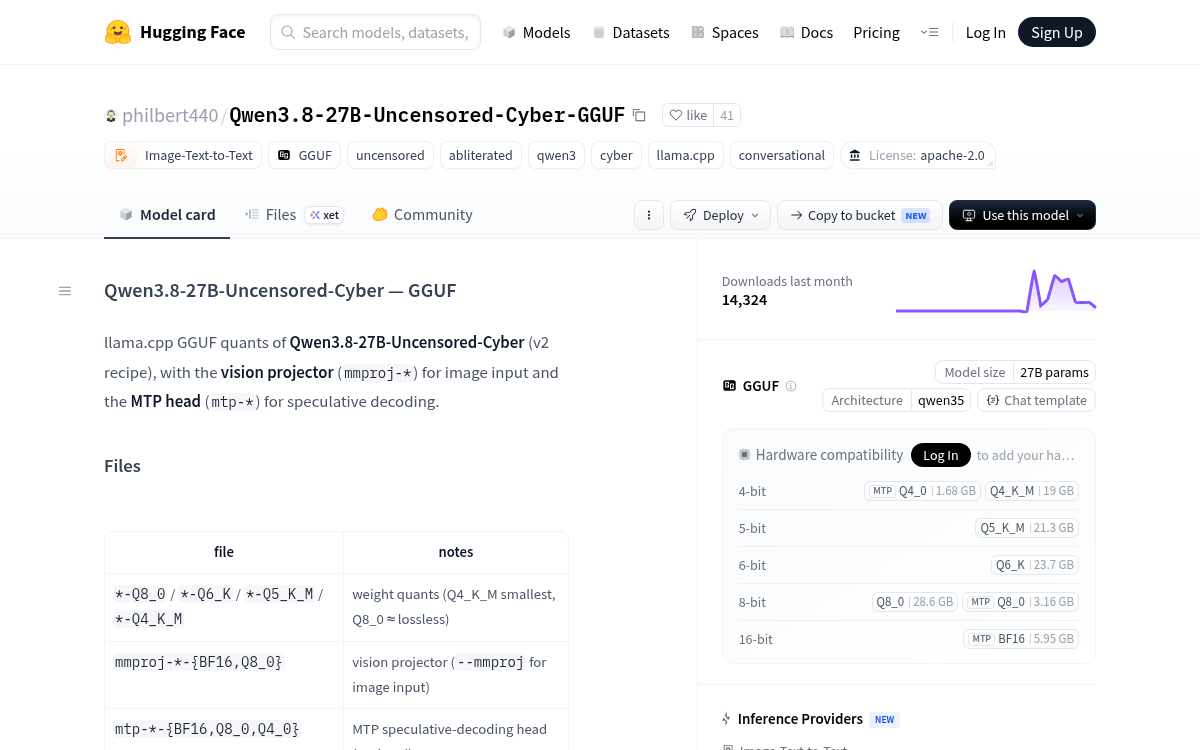
- Qwen3.8-27B-Uncensored-Cyber-GGUF ships as Apache 2.0 llama.cpp quants for local offensive-security work: HF repo
- Scores 100/100 on held-out cyber-offensive prompts, up from 93 in the prior build
- Uses residual-cyber peel: refusal direction projected out of layers 4 and deeper
- Vision projector and MTP speculative-decoding head preserved in the release
- Quant ladder from Q4_K_M (19 GB) to Q8_0 (28.6 GB) fits consumer GPUs
- Runs via llama.cpp, Ollama, LM Studio, vLLM with a single command
A new GGUF release on Hugging Face is aimed squarely at security labs that keep hitting the wall of built-in refusals. Qwen3.8-27B-Uncensored-Cyber-GGUF ships a llama.cpp-ready pack of quantized weights derived from Qwen3.8-27B, tuned to answer offensive-security questions instead of deflecting them. It arrives under Apache 2.0, keeps the vision tower and a speculative-decoding head intact, and has already crossed 14,000 downloads.
Inside the repo
The upload is a full quantization ladder rather than a single file. The package contains llama.cpp GGUF quants of Qwen3.8-27B-Uncensored-Cyber (v2 recipe), along with the vision projector (mmproj) for image input and the MTP head for speculative decoding. The base architecture is worth understanding: Qwen3.8-27B is a 27B dense hybrid-attention model (Gated DeltaNet linear plus full attention) with native vision-language support, reasoning, tool-calling, and an MTP speculative-decoding head.
File sizes span typical consumer-hardware territory:
- Q4_K_M weights at 19 GB (fits a 24 GB GPU)
- Q5_K_M at 21.3 GB
- Q6_K at 23.7 GB
- Q8_0 at 28.6 GB (near-lossless)
This story is for Pro members
You've reached the end of the free preview. Upgrade to AlphaSignal Pro to read the full article - and everything else behind the paywall.
Comments
