

Qwen3.8-27B Hits 417 tok/s on a Single RTX 3090 With 150k Context
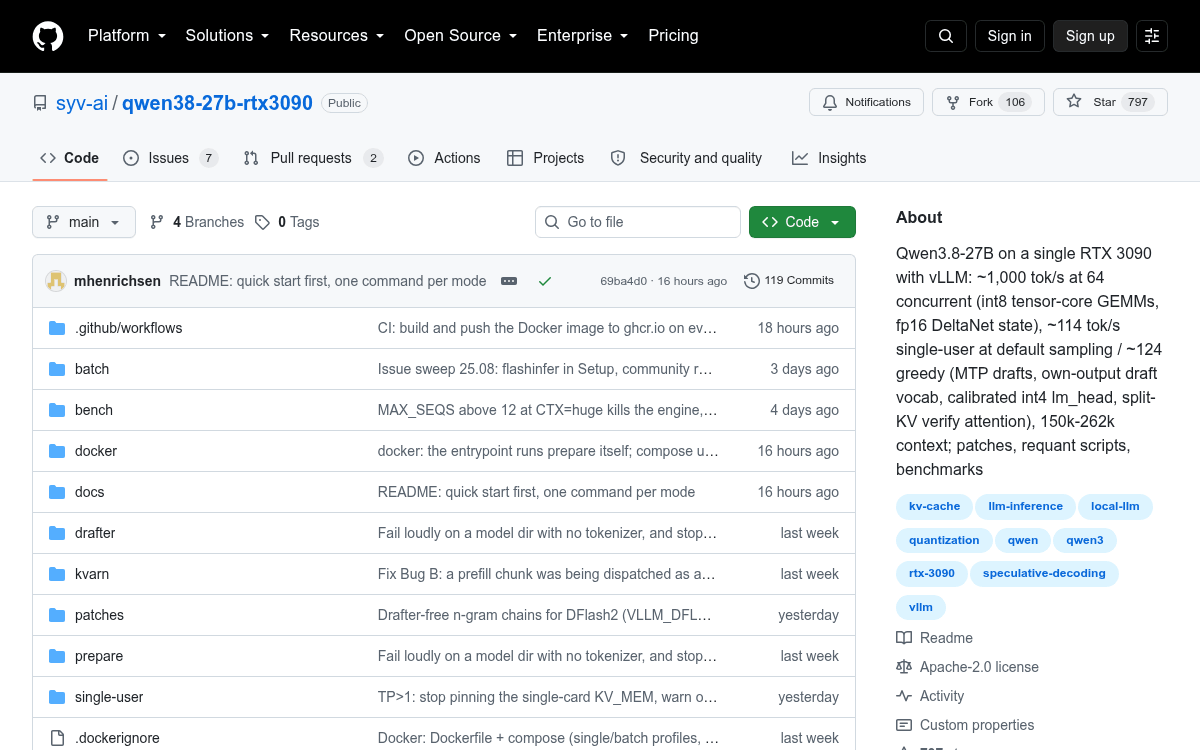
A community project squeezes Qwen3.8-27B onto a 24GB gaming card with vLLM, hitting 417 tok/s batched or 82 tok/s single-user at 150k context.

 PRO
- New repo qwen38-27b-rtx3090 serves Qwen3.8-27B on a single 24GB RTX 3090 via vLLM.
- Hits 417 tok/s at 64 concurrent users, or 82 tok/s single-stream with MTP speculative decoding.
- Requantizes untied lm_head and embed_tokens to int8, reclaiming 2.6 GB of VRAM for batch capacity.
- Supports 150k token context by default, with room to raise toward 195k on request.
- Ships two-line vLLM patch wiring up an unused dequant-on-gather kernel for quantized embeddings.
- Beats prior ninfer-3090 engine by 17 to 149 percent across matched cohort benchmarks.
Running a 27B parameter model on a single consumer GPU used to mean choosing between crippling context length and painful token rates. A new open source project called qwen38-27b-rtx3090 discards that tradeoff with a tightly tuned vLLM setup that fits Qwen3.8-27B into 24 GB of VRAM while serving a 150k token context window.
The repo bundles two ready-made configurations, a pair of requantization scripts, a small vLLM patch, and a set of benchmark harnesses. It targets a 24 GB Ampere or newer NVIDIA card, a recent driver, Python 3.12, and about 40 GB of disk. Everything ships under Apache 2.0 and is available today from the GitHub repository, with the underlying W4A16 AutoRound weights pulled from Hugging Face.
Two modes, one install
The setup ships as a single install with a mode toggle. Batch mode targets API backends, pipelines, and many concurrent requests. Single-user mode is tuned for one or a few people chatting. The crossover sits around eight concurrent users: below that, speculation wins; above, plain batching pulls ahead.
The headline numbers, all measured with vllm bench serve on an RTX 3090 held at a conservative 250 W power limit:
- Batch mode: 417 tok/s aggregate at 64 concurrent, with 672 tok/s peak
- Single-user mode: 82 tok/s single-stream on 1,024-token generations
- Prefill: about 1,210 tok/s at 1k inputs, degrading only to 795 tok/s at 100k
- Median TPOT of 21.4 ms for single-concurrent 256/256 workloads
This story is for Pro members
You've reached the end of the free preview. Upgrade to AlphaSignal Pro to read the full article - and everything else behind the paywall.
Comments
