

Prism ML's Bonsai-8B Runs 6x Faster at 1.15 GB on Any Device
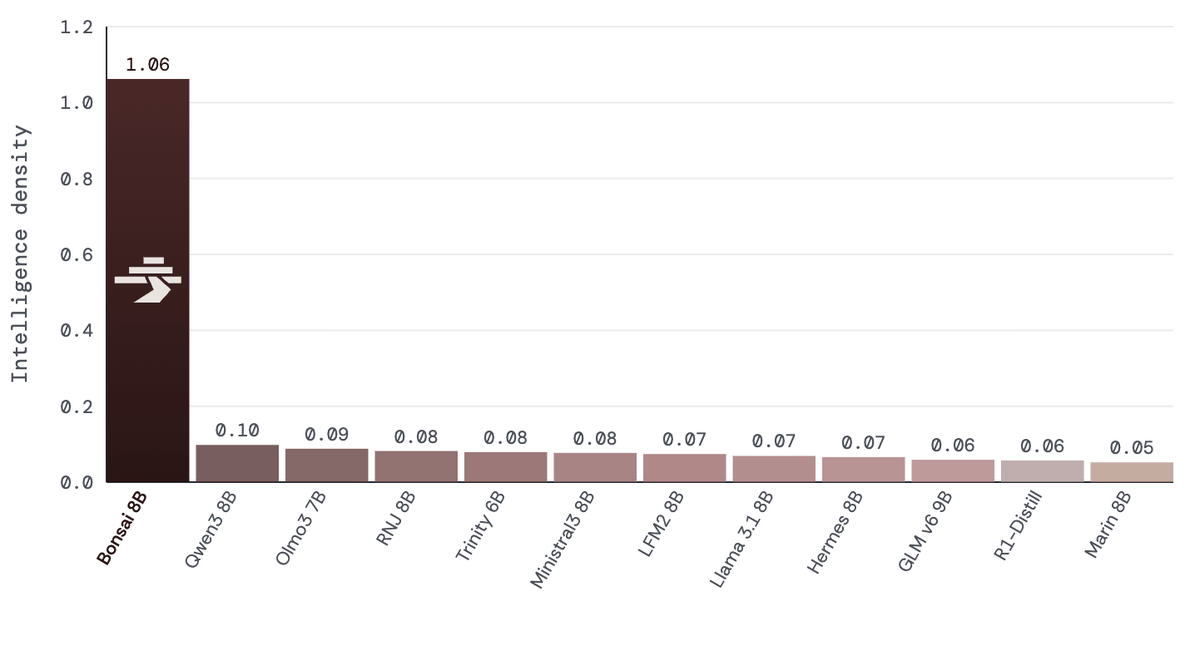
Prism ML's Bonsai-8B squeezes a full 8B language model into 1.15 GB using end-to-end 1-bit quantization, running 6x faster on RTX 4090 and reaching iPhone-class deployment.
 PRO
- Prism ML released Bonsai-8B-GGUF, an end-to-end 1-bit quantization of Qwen3-8B in 1.15 GB.
- Runs 6.2x faster than FP16 on RTX 4090, hitting 368 tokens per second in generation.
- Scores 70.5 average across 6 benchmarks, competitive with full-precision 8B instruct models.
- Uses 4-5x less energy per token on both CUDA and Apple Metal backends.
- Works with llama.cpp, LM Studio, Ollama, MLX and iOS via Locally AI, under Apache 2.0.
- Weakest on multi-step reasoning (MuSR 50); strongest at GSM8K math and instruction following.
Prism ML has released Bonsai-8B-GGUF, an 8-billion parameter language model where every major weight tensor has been reduced to a single bit. The result is a model that weighs 1.15 GB on disk, runs several times faster than its FP16 counterpart on the same hardware, and scores within a few points of leading full-precision 8B instruct models on standard benchmarks.
The headline numbers: 14.1x smaller than FP16, 6.2x faster on an RTX 4090, and 4-5x lower energy per token. If those figures hold in your workloads, they shift the economics of running a capable general-purpose LLM on laptops, phones, and edge devices.
One bit per weight, end to end
Bonsai uses a custom GGUF quantization format called Q1_0. Each weight is a single bit: 0 maps to minus-scale, 1 maps to plus-scale, and every group of 128 weights shares one FP16 scale factor. Amortized across the group, that works out to roughly 1.125 bits per weight.
The quantization covers embeddings, attention projections, MLP projections, and the LM head. Many prior extreme-quantization approaches leave embeddings or the output head in higher precision, which inflates the on-disk size. Bonsai covers all of them, and inline dequantization kernels mean weights are never materialized to FP16 during inference.
The underlying architecture is Qwen3-8B dense with grouped-query attention (32 query heads, 8 KV heads), SwiGLU MLP, RoPE, RMSNorm, 36 decoder layers, and a 65,536-token context window. This is a quantization approach applied to a strong open base, not a new architecture.
This story is for Pro members
You've reached the end of the free preview. Upgrade to AlphaSignal Pro to read the full article - and everything else behind the paywall.
Comments
