

Princeton's SD-Zero Teaches AI to Fix Its Own Mistakes Without a Teacher
Princeton researchers train models to grade their own homework, turning binary correct/incorrect signals into dense token-level supervision without external teachers.
 PRO
- SD-Zero trains one model as both generator and reviser, turning binary rewards into dense token-level supervision.
- No external teacher or gold solutions needed, only a correctness checker and the model itself.
- Gains of 10.5% on Qwen3-4B and 10.4% on Olmo-3-7B across eight math and code benchmarks.
- Beats GRPO, SDFT, and RFT under matched sampling budgets while cutting response length by roughly half.
- Reviser produces highly localized token feedback, functioning like a free process reward model.
- Code available at princeton-pli/Self-Distillation-Zero; paper on arXiv.
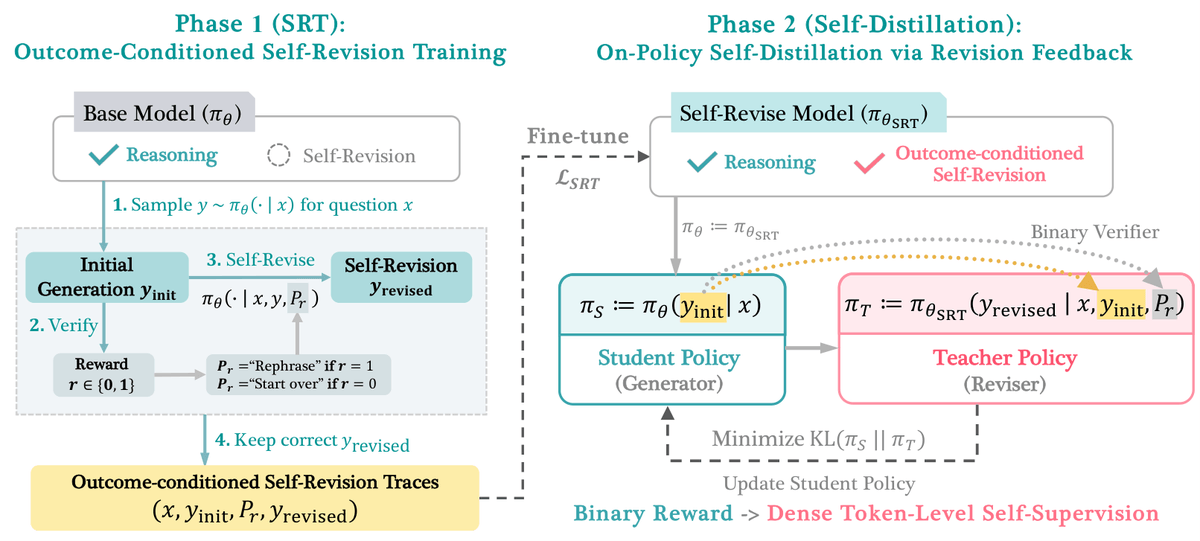
Reinforcement learning with verifiable rewards (RLVR) has become the default recipe for teaching language models to reason, but it has a well-known efficiency problem: a single right-or-wrong signal per response tells the model nothing about which of its thousands of tokens actually caused the failure. A new method called Self-Distillation Zero (SD-Zero) from Princeton, CMU, and Toronto proposes a fix that needs no external teacher and no gold-standard solutions, just the model itself and a binary correctness check.
SD-Zero trains a single model to play two roles: a Generator that produces an initial response, and a Reviser that conditions on that response and its binary reward to produce an improved one. It then performs on-policy self-distillation to fold the reviser back into the generator, using the reviser's token distributions as supervision. The model learns to convert a scalar 0/1 signal into per-token feedback by asking itself what it would do differently if told the answer was wrong.

The sparse-versus-dense trade-off
Post-training in verifiable domains has generally split into two camps. RLVR methods like GRPO are broadly applicable because they only need a checker, but they force the model to figure out good reasoning by contrasting many self-generated rollouts. Distillation methods give rich token-level targets but need either a stronger external teacher or high-quality demonstrations. More recent self-distillation approaches, including OPSD, SDFT, and SDPO, drop the external teacher yet still lean on demonstrations that must be much better than what the model produces on its own.
This story is for Pro members
You've reached the end of the free preview. Upgrade to AlphaSignal Pro to read the full article - and everything else behind the paywall.
Comments
