

Poolside's Laguna S 2.1 Beats 1.6T Models at Coding on a Single Desktop
Poolside's 118B open-weight coding model beats models 5-25x its size on long-horizon agentic tasks, runs on a single DGX Spark, and ships free under OpenMDW-1.1
- Poolside releases Laguna S 2.1, a 118B MoE model (8B active params/token) with a 1M token context window, fully open under OpenMDW-1.1.
- Scores 70.2% on Terminal-Bench 2.1 and 78.5% on SWE-Bench Multilingual, beating models up to 25x its size including DeepSeek-V4-Pro Max and NVIDIA Nemotron 3 Ultra.
- On DeepSWE (the hardest long-horizon benchmark), scores 40.4% -- compared to DeepSeek-V4-Pro Max's 9.0% despite having 13x fewer parameters.
- Trained in under 9 weeks on 4,096 H200 GPUs; key gains came from RL with longer rollout budgets, multi-harness rollouts, and FP8 RL training.
- Ships in BF16, FP8, INT4, NVFP4, GGUF, and MLX; runs on a single NVIDIA DGX Spark; available via OpenRouter at $0.10/$0.20 per 1M tokens or free at 256K context.
- Known limitations: overthinking on hard math, occasional tool schema drift in third-party harnesses, and no intermediate effort control yet.
Laguna S 2.1 is Poolside's largest open-weight release: a 118 billion parameter Mixture-of-Experts (MoE) model that activates only 8 billion parameters per token, supports a 1 million token context window, and is built for long-horizon agentic coding. The weights are live on Hugging Face under the permissive OpenMDW-1.1 license, free to download and use commercially.
Poolside went from the start of training to launch in under nine weeks. On long-horizon coding benchmarks, the model holds its own against models many times its size, and it runs on a single desktop.
Benchmark results
Poolside ran Laguna S 2.1 across six agentic coding benchmarks. The results are notable for a model this size:
- Terminal-Bench 2.1: 70.2% — ahead of DeepSeek-V4-Pro Max (1.6T params, 64.0%), NVIDIA Nemotron 3 Ultra (550B, 56.4%), and Thinking Machines' Inkling (975B, 63.8%)
- SWE-Bench Multilingual: 78.5% — beating Tencent Hy3 (295B, 75.8%) and Nemotron 3 Ultra (67.7%)
- SWE-Bench Pro: 59.4% — ahead of DeepSeek-V4-Pro Max (55.4%) and Inkling (54.3%)
- DeepSWE v1.1: 40.4% — outperforming DeepSeek-V4-Pro Max, which scored 9.0% on this benchmark
DeepSWE v1.1 is worth paying attention to as a signal. Its tasks are long-horizon and hard to partially solve, so scores spread widely: frontier models range from 54% to 73%, while some 1T+ parameter open models score below 10%. That spread makes it more meaningful than saturated benchmarks where top models cluster within a few points of each other.
Thinking mode drives a large share of those gains. Enabling max thinking lifts S 2.1's Terminal-Bench 2.1 score from 60.4% to 70.2% and its DeepSWE score from 16.5% to 40.4%. The tradeoff is token cost: thinking mode uses roughly 129K tokens per trajectory on Terminal-Bench versus 80K without it.
What the model actually does
Poolside published three unedited case studies showing the model working autonomously. They're worth reading to understand what the benchmarks are measuring.
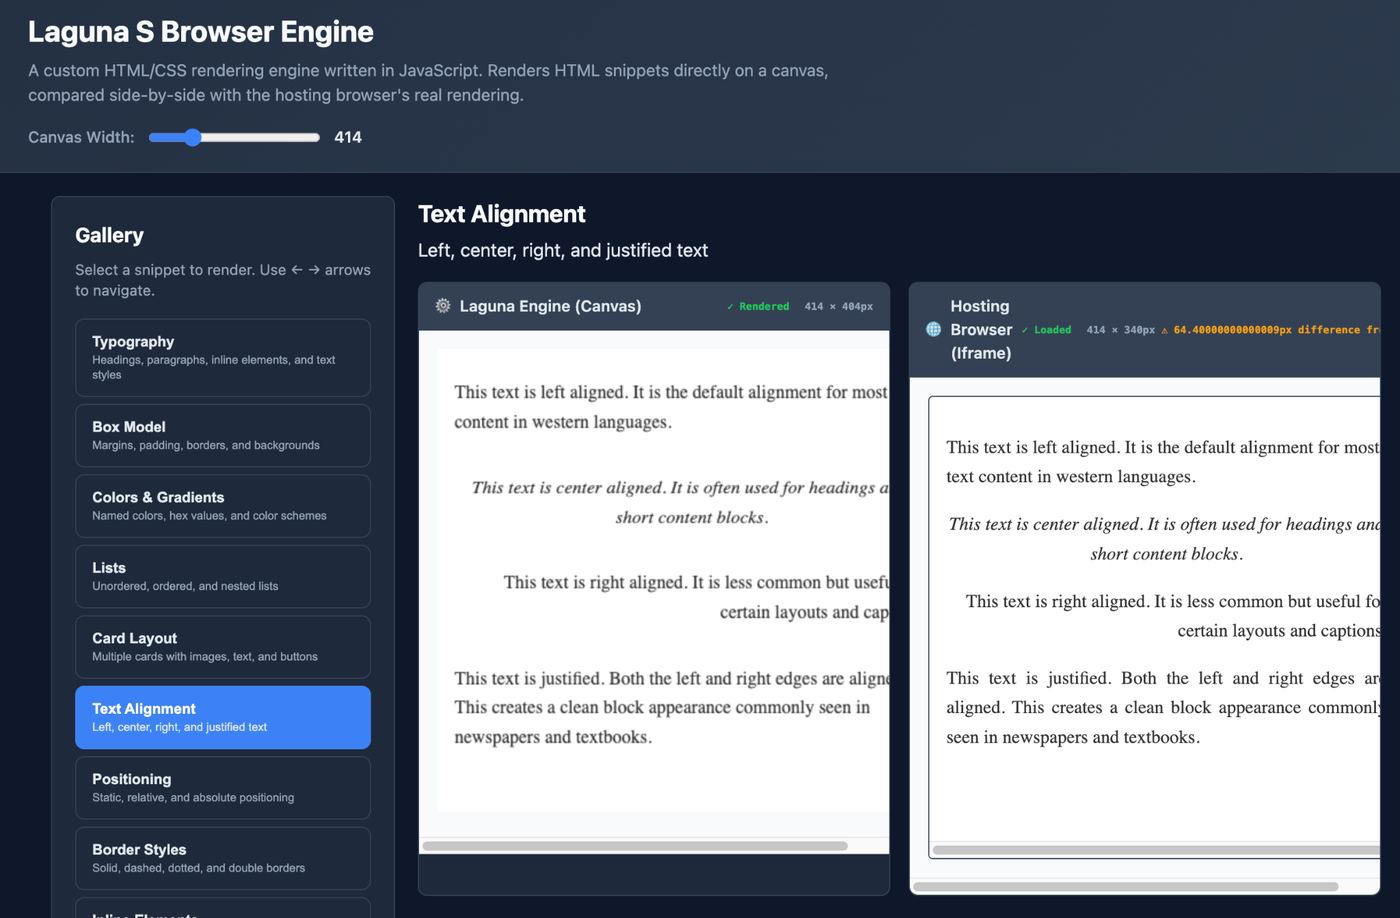
- Browser engine from scratch: In a 50-minute session of 181 steps, with no human intervention, Laguna S 2.1 built a working HTML/CSS rendering engine from an empty folder, then verified its output by spinning up headless Chromium and comparing screenshots numerically.
- Self-optimization loop: Pointed at Poolside's own agent harness, the model ran 20 optimization attempts over several hours, found O(n²) string concatenation in streaming-token accumulation, replaced it with buffers, and made the harness 5.2% faster while cutting memory allocation by roughly 71%. When wall-clock gains became too small to measure reliably, it shifted focus to memory rather than stopping.
- Math proof re-discovery: Poolside publishes a complete trajectory of the model independently proving Erdős Problem #397, a combinatorics problem that until recently only the largest frontier reasoning models had resolved. Working without Python, the model found Perl and derived a structurally different infinite family of solutions than the previously known proof.
Architecture and training
Laguna S 2.1 scales up the Laguna XS family using the same pre-training data as XS 2.1. The step from XS 2.1 to S 2.1 came from scale, training-code fixes, and small recipe changes. The MoE architecture uses 256 routed experts (top-10 selection) plus one shared expert, grouped-query attention with 8 KV heads, and an interleaved layout of 12 global attention layers and 36 sliding-window attention layers. That hybrid design enables the 1M context window.
Post-training happened in two stages. First, supervised fine-tuning (SFT) on labeled examples, partly synthetic, to bootstrap capabilities. Then reinforcement learning (RL), reserved for tasks the model couldn't yet solve reliably, using longer rollout budgets, improved sandbox infrastructure, and multi-harness rollouts so learned behavior transfers across agent scaffolds. S 2.1 is also Poolside's first model to run RL in FP8 precision, which accelerated that phase.
The training corpus spans 409K agentic and non-agentic environments: 83K setups target terminal use cases, 168K target standard software engineering workflows, and the software engineering tasks are grounded in real commit history, merged pull requests, and bug-injection tasks across roughly 17,000 repositories.
Poolside's Co-head of Applied Research described the goal as improving the behaviors that lead to capability: more verification, less taking things for granted, not declaring victory early, and more persistence. Earlier Laguna models would declare victory on a partially-passing test suite or abandon an approach two steps before it worked. S 2.1 keeps going.
Known limitations
Poolside ships with documented rough edges:
- Overthinking on hard math: The model can run very long sequences before making progress on competition-level mathematics. There is currently no middle ground between no-thinking and max — effort control is on the roadmap.
- Harness overfitting: The model sometimes struggles with tool schema definitions in third-party agent harnesses that closely resemble but differ slightly from the native harness. A rejected call and retry usually corrects it.
- JSON array escaping: Tool arguments expecting JSON arrays can be incorrectly escaped or invalid.
Release cadence
Laguna M.1 and XS.2 launched together, XS 2.1 shipped three weeks ago, and S 2.1 follows — all within a single quarter. Pre-training on 4,096 NVIDIA H200 GPUs began May 22, 2026, 60 days before launch. Poolside also confirmed that a larger Laguna model began pre-training last week, so S 2.1 is a waypoint.
The release lands as the question of who supplies the West's open-weight models has moved from research circles into boardrooms and policy discussions. Poolside positions S 2.1 as a Western-built alternative to models like DeepSeek, and the OpenMDW-1.1 license — backed by NVIDIA and the Linux Foundation — is designed to give enterprise legal teams cleaner standing than Apache 2.0.
How to run it
The model ships in BF16, FP8, INT4, and NVFP4 formats, with official GGUF and MLX conversions. The BF16 checkpoint requires multiple GPUs (~236GB of weights), but quantized variants reduce this substantially. Day-one support is available across the major serving stacks:
- vLLM / SGLang / llama.cpp: Full support with
--tool-call-parser poolside_v1and--reasoning-parser poolside_v1flags - Ollama: Available directly
- NVIDIA TRT-LLM: Optimized for DGX Spark, single-machine deployment
- OpenRouter: Free endpoint at 256K context; dedicated paid endpoint at full 1M context priced at $0.10 / $0.20 / $0.01 per 1M input / output / cache-read tokens
- Vercel AI Gateway: Available directly
- Baseten: Dedicated inference via their Frontier Gateway
To enable thinking in vLLM:
vllm serve \
    --model poolside/Laguna-S-2.1 \
    --tensor-parallel-size 4 \
    --tool-call-parser poolside_v1 \
    --reasoning-parser poolside_v1 \
    --enable-auto-tool-choice \
    --default-chat-template-kwargs '{"enable_thinking": true}'
To toggle thinking per request at inference time:
extra_body={"chat_template_kwargs": {"enable_thinking": False}}The simplest entry point is chat.poolside.ai — no login required. For agentic use, Poolside's own pool terminal agent is the recommended interface. The weights on Hugging Face are live now, and full evaluation trajectories for every benchmark run are published at trajectories.poolside.ai, letting anyone audit how the scores were achieved.
Comments
