

NVIDIA Opens Megatron-LM to the World, Hitting 1,233 TFLOPS on GB300
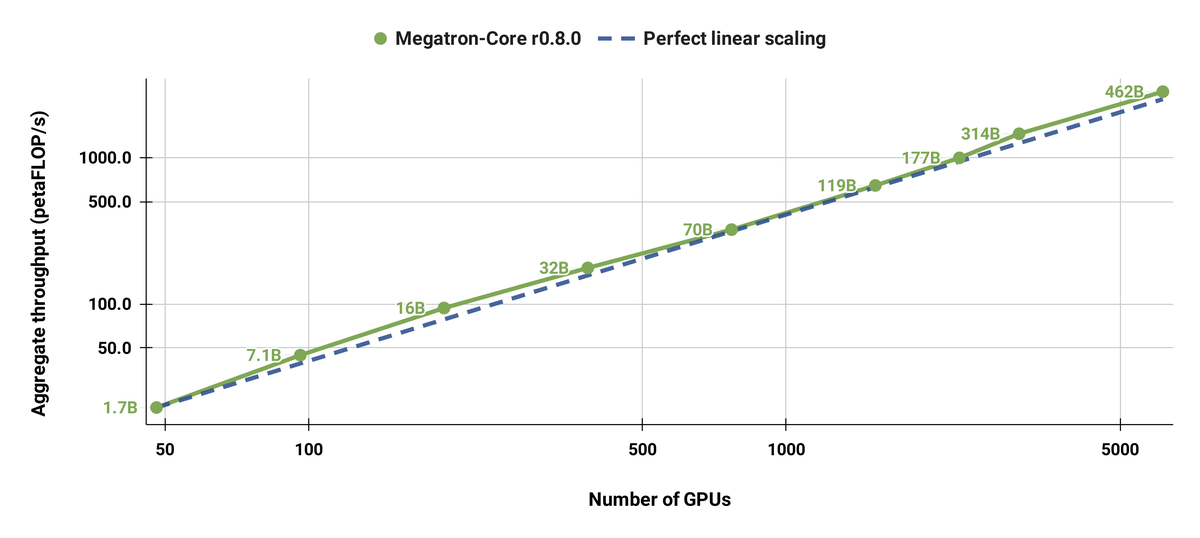
Megatron Core's full development is now open on GitHub, with a new MoE technical report, Dynamic Context Parallelism, and benchmarks scaling to 462B parameters on 6,144 H100s.
 PRO
- Open development: Megatron Core's full development and CI have moved to GitHub, opening contributions to the community.
- MoE technical report: NVIDIA published a paper detailing scalable MoE training, achieving 1,233 TFLOPS/GPU on GB300 for DeepSeek-V3-685B.
- Dynamic Context Parallelism: New scheduling approach delivers up to 1.48x speedup for variable-length sequence training by adapting CP size per microbatch.
- Dense model scale: Benchmarks cover 2B–462B parameter models on up to 6,144 H100 GPUs, reaching 47% MFU.
- Active MoE roadmap: Public roadmap targets DeepSeek-V3, Qwen3, FP8/NVFP4, and Blackwell GPU optimizations.
- Megatron Bridge: Separate tool provides bidirectional HuggingFace ↔ Megatron checkpoint conversion with production-ready recipes.
If you've been training large models and wondering what the most battle-tested open-source infrastructure underneath them looks like, NVIDIA's Megatron-LM repository is worth a close look right now. The project has been around since 2019, but it has quietly become one of the most significant shifts in how frontier model training infrastructure is developed and shared: Megatron Core's development and CI have fully moved to GitHub, opening the entire engineering process to the community.
Megatron Core development has moved to GitHub, meaning all development and CI now happens in the open, and community contributions are actively welcomed. This is a meaningful change from how NVIDIA previously ran internal development. The practical effect: you can now track commits, file issues, submit PRs, and follow the roadmap in real time.
Two things in one repo
The repository actually contains two distinct components that are easy to conflate:
- Megatron-LM , a reference training framework with pre-configured scripts. Best for research teams and quick experimentation.
- Megatron Core , a composable, modular library of GPU-optimized building blocks. Megatron Core is an open-source PyTorch-based library that contains GPU-optimized techniques and cutting-edge system-level optimizations, abstracting them into composable and modular APIs that allow full flexibility for developers and model researchers to train custom transformers at scale on NVIDIA accelerated computing infrastructure.
Megatron Core is a library of GPU-optimized training techniques that comes with formal product support including versioned APIs and regular releases. The latest release is v0.16.1. You can install it directly from PyPI:
uv pip install megatron-coreThe MoE paper that explains how it all works
This story is for Pro members
You've reached the end of the free preview. Upgrade to AlphaSignal Pro to read the full article - and everything else behind the paywall.
Comments
