

Mistral Medium 3.5 Retires Three Separate Models Into One 128B Open Weight
Mistral folds chat, reasoning, and coding into one 128B dense open-weight model with 256K context and a per-request reasoning toggle.
 PRO
- Mistral Medium 3.5 is a dense 128B open-weight model with a 256K context window under a Modified MIT license.
- Single model replaces Medium 3.1, Magistral, and Devstral 2 with a per-request
reasoning_efforttoggle. - Scores 77.6% on SWE-Bench Verified and 91.4% on τ³-Telecom, beating all prior Mistral coding models.
- Priced at $1.50 input / $7.50 output per million tokens, roughly half of Claude Sonnet 4.6.
- Self-hostable on 4 GPUs with FP8, day-zero support in vLLM, SGLang, and Ollama.
- Companion EAGLE draft model released for speculative decoding speedups.
Mistral just did something the other frontier labs have been doing quietly: they collapsed their entire model lineup into a single set of weights. Mistral Medium 3.5 is a dense 128B parameter model with a 256K context window that replaces three previously separate models in the stack, and it ships under a Modified MIT license so you can actually run it yourself.
Shipping Medium 3.5 also quietly retired Magistral (reasoning), Devstral 2 (coding), and Medium 3.1 (chat). Three product lines folded into one 128B dense model with a reasoning toggle. That consolidation is worth more attention than any single benchmark number.
One model, one toggle, two personalities
The core trick is a reasoning_effort parameter you set per request. Set it to none for fast instruction-following, or high to unlock chain-of-thought traces wrapped in [THINK] tags for hard problems. Same weights, different behavior, chosen at call time.
Compare that to what the industry has been doing. There's a "fast" or "instant" checkpoint trained primarily for chat-style instruction following, and a separate "thinking" checkpoint heavily post-trained on chain-of-thought traces. When you toggle "thinking" in ChatGPT or Claude, you route your prompt to a different set of weights. Medium 3.5 collapses this entirely: one weight file, two modes, no router in front.
The benchmark story
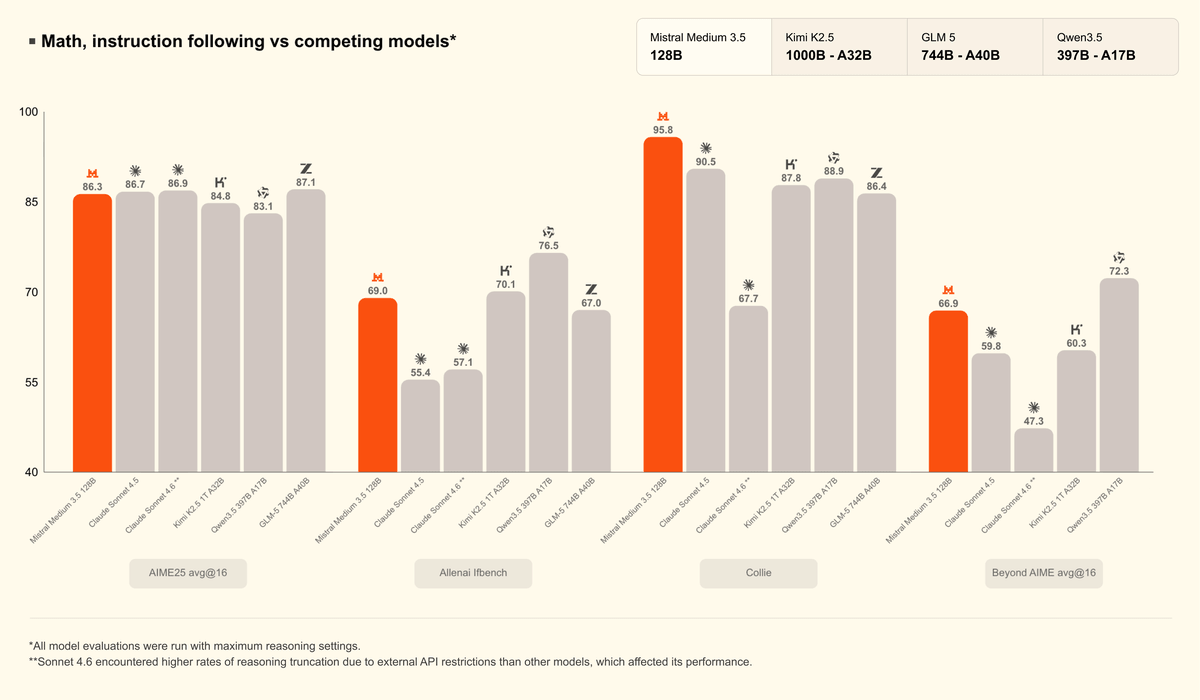
Medium 3.5 supersedes all of Mistral's previous coding models across benchmarks, scoring 91.4% on τ³-Telecom and 77.6% on SWE-Bench Verified. The τ³ (tau-cubed) suite measures multi-turn tool use across telecom, airlines, retail, and banking, so it works as a proxy for agentic reliability rather than a static QA score. On the strength of those numbers, Medium 3.5 also takes over from Devstral 2 inside Mistral's Vibe CLI.
This story is for Pro members
You've reached the end of the free preview. Upgrade to AlphaSignal Pro to read the full article - and everything else behind the paywall.
Comments
