

Microsoft's Sico-Evolution Beats GPT-5.4 at GUI Tasks With a Tiny 4B Open Model
Microsoft's Sico-Evolution doubles task success rate to 82.9% on a 4B model, beating GPT-5.4 and Claude Opus 4.7 on Edge and Copilot UI tasks
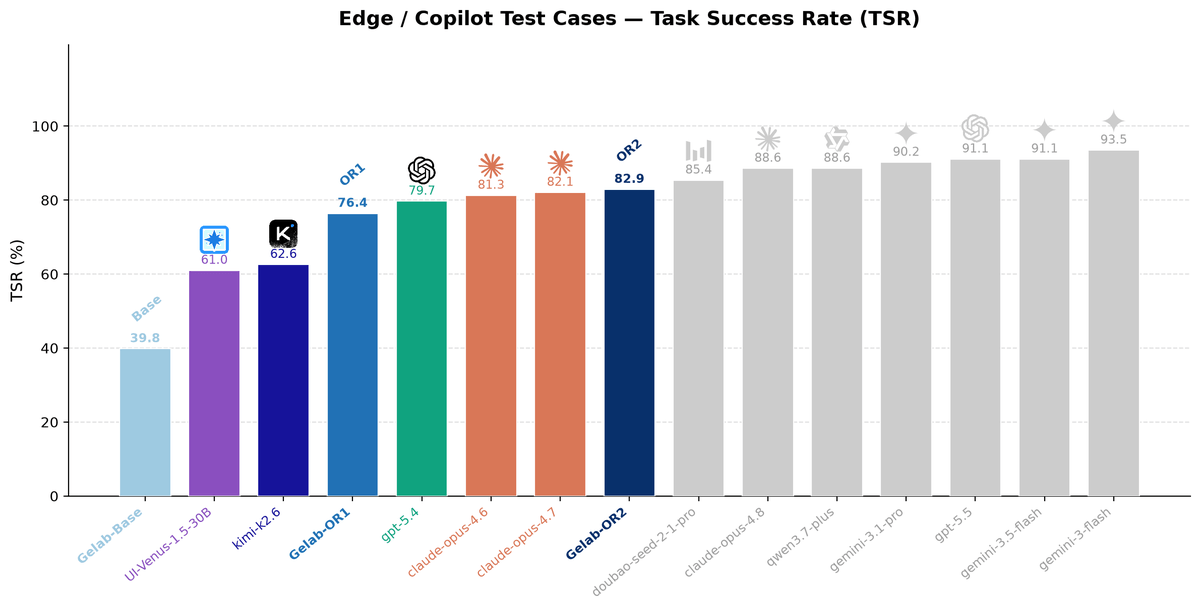 PRO
- 82.9% Task Success Rate: Microsoft's Sico-Evolution jumps +43.1 points from its 39.8% baseline on Edge and Copilot UI tasks.
- Beats proprietary giants: Outperforms GPT-5.4 (79.7%), Claude Opus 4.6 (81.3%), and Claude Opus 4.7 (82.1%) at just 4B parameters.
- LoRA fine-tune on real trajectories: Built on GELab-Zero-4B-preview (Qwen3-VL-4B) using Microsoft Edge and Copilot UI interaction data.
- Iterative evolution pipeline: Project Sico uses a round-by-round improvement loop designed to transfer to any GUI app.
- Fully open-source: Available now on Hugging Face under Apache 2.0, compatible with Transformers, vLLM, and SGLang.
- First of more to come: Microsoft describes this as the first public release from the Sico evolution pipeline, with additional evolved models planned.
GUI agents -- AI systems that can look at a screen and autonomously click, type, and navigate software -- have been a frontier mostly dominated by large, expensive proprietary models. Microsoft just flipped that script. The team behind Project Sico released GELab-Zero-4B-preview-Sico-Evolution, a 4-billion-parameter GUI agent that outperforms GPT-5.4, Claude Opus 4.6, and Claude Opus 4.7 on real Microsoft Edge and Copilot UI tasks -- all while being fully open-source under Apache 2.0.
From 39.8% to 82.9% in one pipeline
Sico-Evolution achieves a dominant 82.9% Task Success Rate, a massive +43.1% absolute surge over the 39.8% base-model baseline. To put that in perspective, it edges out top proprietary giants like GPT-5.4 (79.7%), Claude Opus 4.6 (81.3%), and Claude Opus 4.7 (82.1%). It also vastly exceeds leading open-source competitors including kimi-k2.6 (62.6%) and UI-Venus-1.5-30B (61.0%).
The benchmark here is Task Success Rate (TSR) on real Edge and Copilot UI trajectories -- meaning the agent is scored on whether it actually completes a task end-to-end, not just whether individual clicks look right. That's a much harder bar than static localization benchmarks, and it's the one that matters for real deployments.
What's actually powering this jump
Sico-Evolution is a 4B GUI agent fine-tuned with LoRA from the open-source GELab-Zero-4B-preview base model on Microsoft Edge and Copilot UI trajectories, built with a general-purpose GUI model evolution pipeline -- an iterative mechanism that keeps lifting an agent's real task success rate round after round, and transfers to any GUI app.
The base model itself, GELab-Zero-4B-preview, is built on Qwen3-VL-4B and was developed by StepFun's GELab team. It already had strong GUI fundamentals: GELab-Zero-4B-preview achieves 75.86% success rate on AndroidWorld testing, demonstrating excellent performance on complex mobile tasks. Microsoft's Sico pipeline then takes that foundation and evolves it specifically for Windows-native UI environments.
This story is for Pro members
You've reached the end of the free preview. Upgrade to AlphaSignal Pro to read the full article - and everything else behind the paywall.
Comments
