

lordx64's Open Qwen3.6 Learns Claude Opus 4.7 Reasoning on a Single GPU
An open-weights Mixture-of-Experts model gets fine-tuned on 8,000 Claude Opus 4.7 reasoning traces, porting frontier chain-of-thought style into Apache 2.0 weights.
 PRO
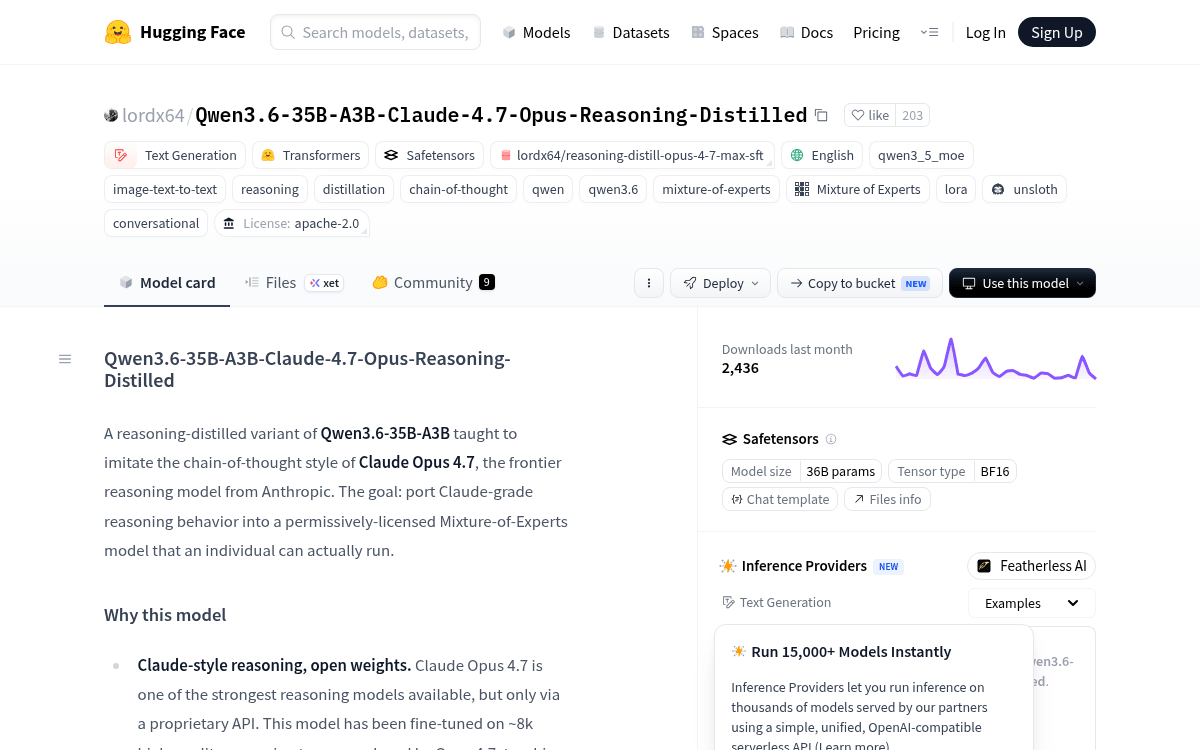
- Qwen3.6-35B-A3B distilled on ~8k Claude Opus 4.7 reasoning traces, released under Apache 2.0 on Hugging Face.
- 35B MoE with 256 experts, only ~3B parameters active per token; runs on a single 80GB GPU.
- Scores 74.9% on MMLU-Pro and 84.3% on GSM8K CoT; strong on STEM subjects.
- Trained with a tiny attention-only LoRA (3.44M params, 0.01% of the model) using Unsloth and TRL SFT.
- GGUF quants from IQ4_XS (18.9 GB) to Q8_0 (~35 GB) available for llama.cpp and LM Studio.
- Author upstreamed a fix to unsloth-zoo PR #601 to make MoE+LoRA work on Qwen3.6's 256-expert layout.
A community developer known as lordx64 has released a reasoning-distilled variant of Qwen3.6-35B-A3B trained to think like Anthropic's Claude Opus 4.7. The checkpoint ships under Apache 2.0, runs on a single 80GB GPU in bf16, and has crossed 70,000 downloads on Hugging Face. It is one of the more interesting recent attempts to close the gap between closed API reasoning models and what you can actually deploy on your own hardware.
Claude-flavored thinking, open weights
Qwen3.6-35B-A3B has been taught to imitate the chain-of-thought style of Claude Opus 4.7, Anthropic's frontier reasoning model. Where Opus sits behind a proprietary API, this checkpoint lives on Hugging Face with permissive licensing. The base was fine-tuned on roughly 8k high-quality reasoning traces produced by Opus 4.7, teaching it to think before answering with explicit think blocks in Claude's structure and cadence.
The underlying architecture is what makes this practical. It is a 35B parameter Mixture-of-Experts model with 256 experts (8 routed plus 1 shared per token), and only about 3B parameters activate on any forward pass. You get the knowledge footprint of a 35B model at roughly the inference cost of a 3B dense model. Full bf16 inference fits on a single 80GB A100 or H200, and the context window is 64k tokens, which matters because reasoning traces on hard problems routinely balloon to 5,000-30,000 tokens of think content before the model commits to an answer.
The training recipe, in full
The training recipe is deliberately minimal, and that is part of the story. Rather than touching the MoE expert feedforward layers, the author trained an attention-only LoRA adapter with these settings:
- Adapter: rank 16, alpha 16, applied only to
q_proj,k_proj,v_proj,o_proj - Trainable parameters: 3.44M out of 35.1B, or about 0.01% of the model
- Optimizer
This story is for Pro members
You've reached the end of the free preview. Upgrade to AlphaSignal Pro to read the full article - and everything else behind the paywall.
Comments
