

LocalAI's Qwen3.6 Packs Self-Speculative Decoding Into One 16GB File
A quantized reasoning model that ships its own speculative draft head inside the GGUF, giving 1.5-2x faster local inference from one flag.
 PRO
- LocalAI team ships APEX-quantized Qwen3.6-35B distilled from Claude 4.7 Opus reasoning traces on Hugging Face
- Multi-token prediction head bundled inside the GGUF enables self-speculative decoding with one flag
- Just add
--draft-mtpto llama-server, no separate draft model to download or align - Each MTP quant is only about 2.5% larger than the non-MTP GGUF counterpart
- APEX I-Quality at 21.3 GB matches Q8_0 perplexity while running roughly 20% faster
- Apache 2.0 license, runs with llama.cpp, LM Studio, Ollama, and LocalAI
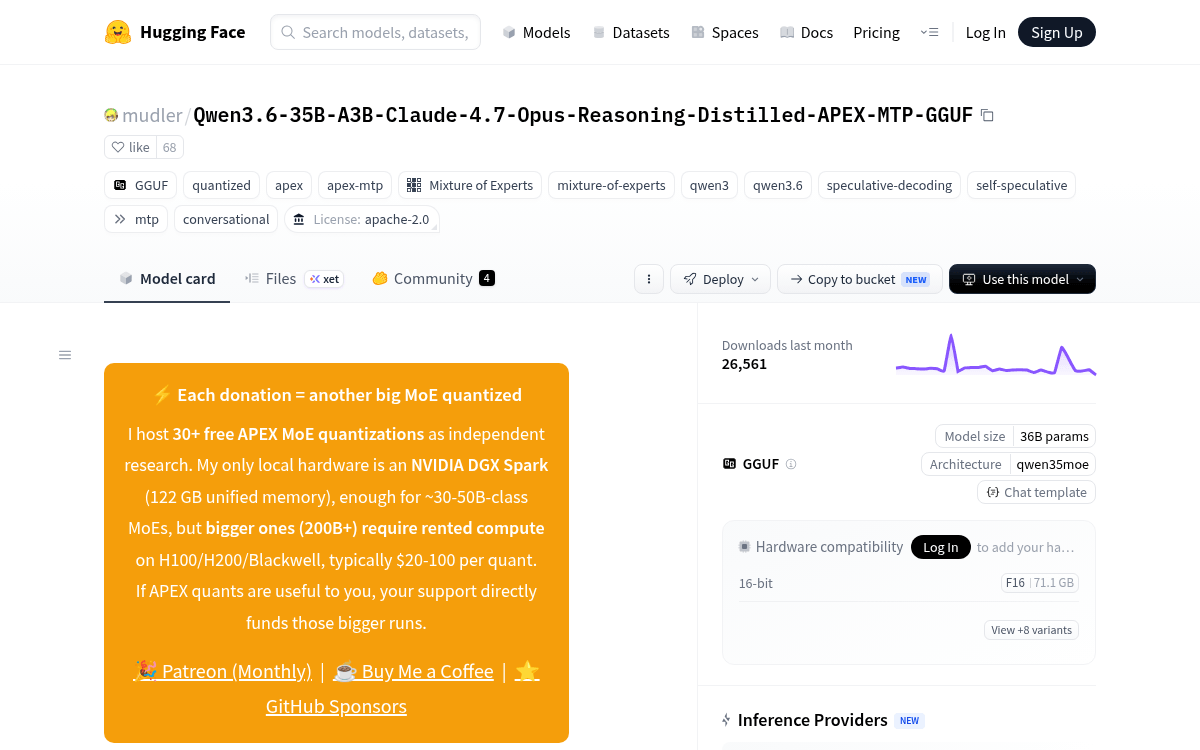
The LocalAI team has released an APEX-quantized GGUF build of Qwen3.6-35B-A3B-Claude-4.7-Opus-Reasoning-Distilled, a Mixture-of-Experts reasoning model distilled from Claude 4.7 Opus traces. What is packed inside the file changes how you run it: a multi-token prediction head lets llama.cpp do speculative decoding against the model itself, with no second draft model to load.
You get the accuracy of the full 35B MoE, the footprint of a compact quant, and a built-in speed boost that turns on with a single command line flag.
One file, one flag, faster tokens
Speculative decoding normally requires running a small draft model alongside the big one. The draft guesses several tokens ahead, the big model verifies them in parallel, and if the guesses were right you get multiple tokens per forward pass. It works, but you have to download, load, and keep two separate checkpoints aligned.
This release collapses that setup into one binary. The GGUFs bundle the model's MTP head alongside the trunk in a single file, courtesy of llama.cpp PR #22673, and with a recent llama.cpp (commit 255582687 or later) you can enable self-speculative decoding using just this one file, no separate drafter needed. The command is exactly what you would expect:
llama-server -m Qwen3.6-35B-A3B-Claude-4.7-Opus-Reasoning-Distilled-APEX-MTP-I-Balanced.gguf --draft-mtpEach quant is roughly 2.5% larger than its non-MTP counterpart, one extra transformer-block worth of weights, with no embedding duplication since MTP shares the trunk's embed_tokens. If self-spec does not pay off for your workload, drop the flag and the file behaves like a normal GGUF.
This story is for Pro members
You've reached the end of the free preview. Upgrade to AlphaSignal Pro to read the full article - and everything else behind the paywall.
Comments
