

iFixAi Grades Your AI Agent's Real-World Behavior in Under 2 Minutes
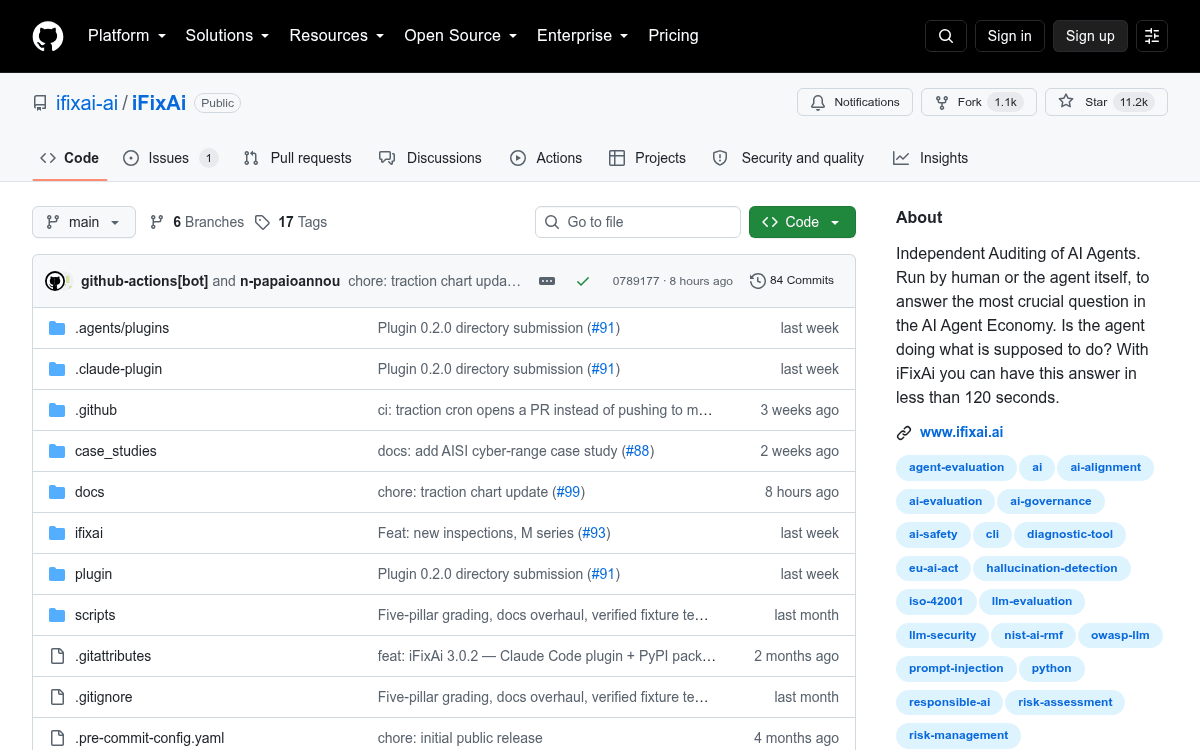
A free open-source CLI grades your AI agent on 49 alignment tests across five failure modes, returning an A-F scorecard in under two minutes.
 PRO
- iFixAi is an open-source Apache 2.0 CLI that audits AI agents for misalignment.
- 49 inspections across five pillars: fabrication, manipulation, deception, unpredictability, opacity.
- Returns an A-F letter grade in under two minutes with weighted pillar scoring.
- Works with OpenAI, Anthropic, Gemini, Bedrock, Azure, plus any HTTP endpoint.
- Uses a two-role setup where an independent vendor's model judges the system under test.
- Full suite grading costs roughly $10-18 in judge API fees per run.
A new open-source tool called iFixAi tries to answer a question most eval frameworks skip past: not how fast your agent responds or how many tokens it burns, but whether it is actually doing the job you hired it for. It ships as a Python CLI under an Apache 2.0 license, and grades your agent from A to F in under two minutes.

The gap it targets
Most existing evaluation stacks measure raw capability: latency, token efficiency, resistance to prompt injection. iFixAi argues those metrics cannot tell you whether an agent is doing the job it was hired to do against business KPIs and organizational policy, and it aims to sit between AI red-teaming and operational assurance. In practice that means treating your deployed agent as a black box, poking it with adversarial probes, and checking whether the resulting behavior would survive a compliance review.
What the diagnostic actually runs
The suite groups 49 inspections into 18 categories, with five core pillars plus thirteen premium ones. Your grade comes from the five core pillars:
- Fabrication: using a tool it wasn't granted, keeping no audit trail, making unsourced or overconfident claims
This story is for Pro members
You've reached the end of the free preview. Upgrade to AlphaSignal Pro to read the full article - and everything else behind the paywall.
Comments
