

Google DeepMind's Gemma 4 E4B Runs Fully Offline on 8GB Apple Silicon
LM Studio's 4-bit MLX build of Gemma 4 E4B brings a multimodal, reasoning-capable 8B model to Apple Silicon at a fraction of the memory.
 PRO
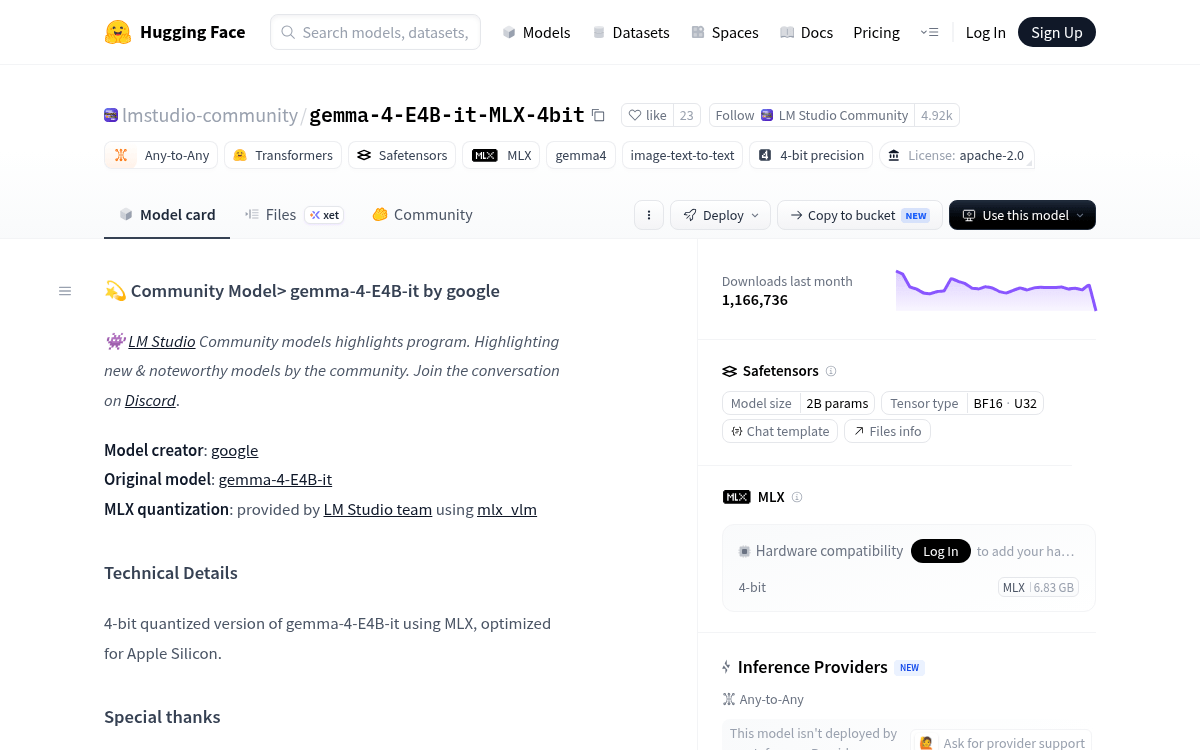
- LM Studio community shipped a 4-bit MLX quant of Gemma 4 E4B-it, optimized for Apple Silicon via Metal.
- Model is multimodal: text, image, and audio input with 128K context and configurable thinking mode.
- Uses Per-Layer Embeddings, so 8B total parameters run as roughly 4.5B effective.
- Benchmarks beat Gemma 3 27B on MMLU Pro, AIME, LiveCodeBench, and GPQA Diamond.
- Apache 2.0 license, native function calling, and system prompt support out of the box.
- Already past 1.15M downloads; also available in 5, 6, and 8-bit MLX variants.
A 4-bit MLX quantization of Google DeepMind's Gemma 4 E4B instruction-tuned model is now available on Hugging Face, packaged by the LM Studio community and tuned to run through Apple's Metal stack rather than the usual GGUF/llama.cpp path. It has already crossed 1.15 million downloads, making it one of the most-pulled artifacts from the Gemma 4 family since launch.
The build is a straight 4-bit quantization of the base checkpoint produced with mlx_vlm, LM Studio's vision-language quantizer for MLX. You get the full multimodal Gemma 4 E4B, including image and audio inputs, compressed to run comfortably on 8GB and 16GB Apple Silicon machines.
What E4B actually is under the hood
Gemma 4 is Google DeepMind's newest open-weights family, and E4B sits at the small-but-serious end of the lineup. The family supports a context window of up to 256K tokens, over 140 languages, dense and Mixture-of-Experts variants, and ships in five sizes: E2B, E4B, 12B, 26B A4B, and 31B.
The "E" in E4B stands for effective parameters. The model has roughly 8B total parameters but only about 4.5B effective, thanks to a technique called Per-Layer Embeddings (PLE) where each decoder layer gets its own small embedding table used only for token lookups. That keeps the parameter count flowing through matrix multiplies small, which is exactly what you want on a phone or laptop.
This story is for Pro members
You've reached the end of the free preview. Upgrade to AlphaSignal Pro to read the full article - and everything else behind the paywall.
Comments
