

Fudan's verl-if Trains AI to Follow Instructions 100x Faster Without a Teacher Model
A new label-free reinforcement learning recipe teaches models to obey multi-constraint prompts using only the instructions themselves, no stronger teacher required.
 PRO
- Fudan and Ant Group release a self-supervised RL framework for multi-constraint instruction following, no teacher model needed.
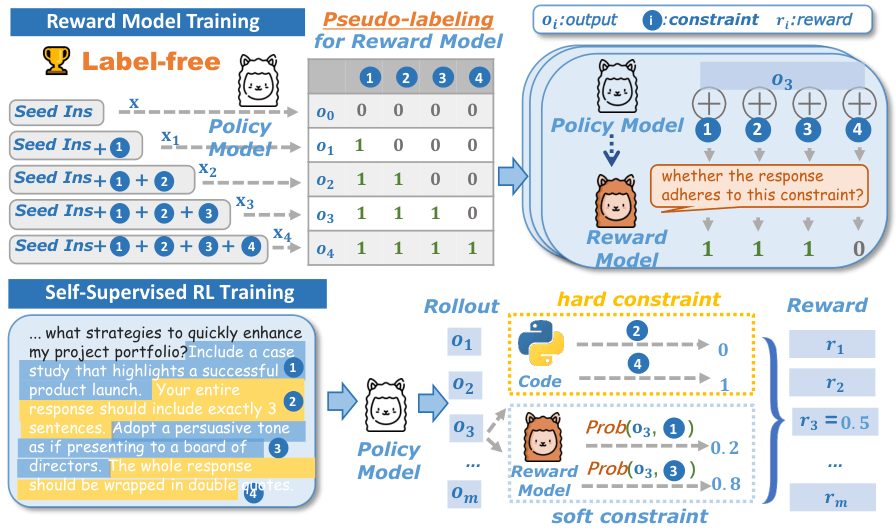
- Pseudo-labels are derived by comparing responses generated with and without a given constraint, matching human labels 90%+ of the time.
- A constraint curriculum decomposes prompts into incremental sub-instructions, solving the sparse reward problem in complex tasks.
- Qwen2.5-1.5B gains 21.6 points on IFEval; R1-0528-Qwen3-8B reaches 87.1, matching VERIF-8B trained with a 32B judge.
- The binary classifier reward model runs roughly 100x faster than QwQ-32B judges while producing better RL outcomes.
- Code, data, and checkpoints are available at github.com/Rainier-rq/verl-if.
Teaching a language model to obey a prompt that says write a poem, under 13 sentences, no commas, title in double angular brackets sounds trivial. In practice, models routinely violate at least one constraint. A team from Fudan University and Ant Group has released a reinforcement learning framework that fixes this without needing a stronger teacher model or human-labeled preference pairs, relying instead on the structure of the instructions themselves to bootstrap a reward signal.
The method, described in the paper Instructions are all you need, targets a stubborn failure mode: models can recite the constraints they are supposed to follow, then ignore them in the output. Code is available in the verl-if repository, with checkpoints released on Hugging Face.
Why multi-constraint prompts fall apart
Real conversations with users often stack several constraints into a single instruction, and reasoning-tuned models tend to trade adherence for chain-of-thought quality. The standard fix, reinforcement learning with verifiable rewards (RLVR), carries three nagging problems that this paper isolates:
- Supervision dependency. Existing approaches lean on stronger models, either directly as reward models or as sources for distilling reward-model training data, or on manual annotation. That caps the student at the teacher's ceiling.
- Sparse rewards. An instruction with five constraints is rarely satisfied all at once, so the model gets zero reward for most rollouts and cannot learn efficiently.
This story is for Pro members
You've reached the end of the free preview. Upgrade to AlphaSignal Pro to read the full article - and everything else behind the paywall.
Comments
