

Frozen Qwen2.5-VL Beats Trained Image Search Models Without a Single Gradient Step
A new paper turns off-the-shelf multimodal LLMs into zero-shot image-to-image re-rankers, beating task-specific models on out-of-domain retrieval.
 PRO
- Frozen Qwen2.5-VL-7B used as a zero-shot re-ranker via binary yes/no next-token probability on image pairs
- Outperforms task-specific AMES and fine-tuned LamRA on ILIAS, INSTRE, and Product1M without any training
- Reaches 54.4 mAP on ILIAS vs 41.9 for AMES and 33.4 for the no-re-rank global baseline
- Product Quantization indexing cuts per-image memory from ~2MB to kilobytes with minor accuracy loss
- Robust to clutter, occlusion, small objects; weak against illumination changes and motion blur
- Code at github.com/gkordo/mllm-ilr, evaluated on ILIAS benchmark
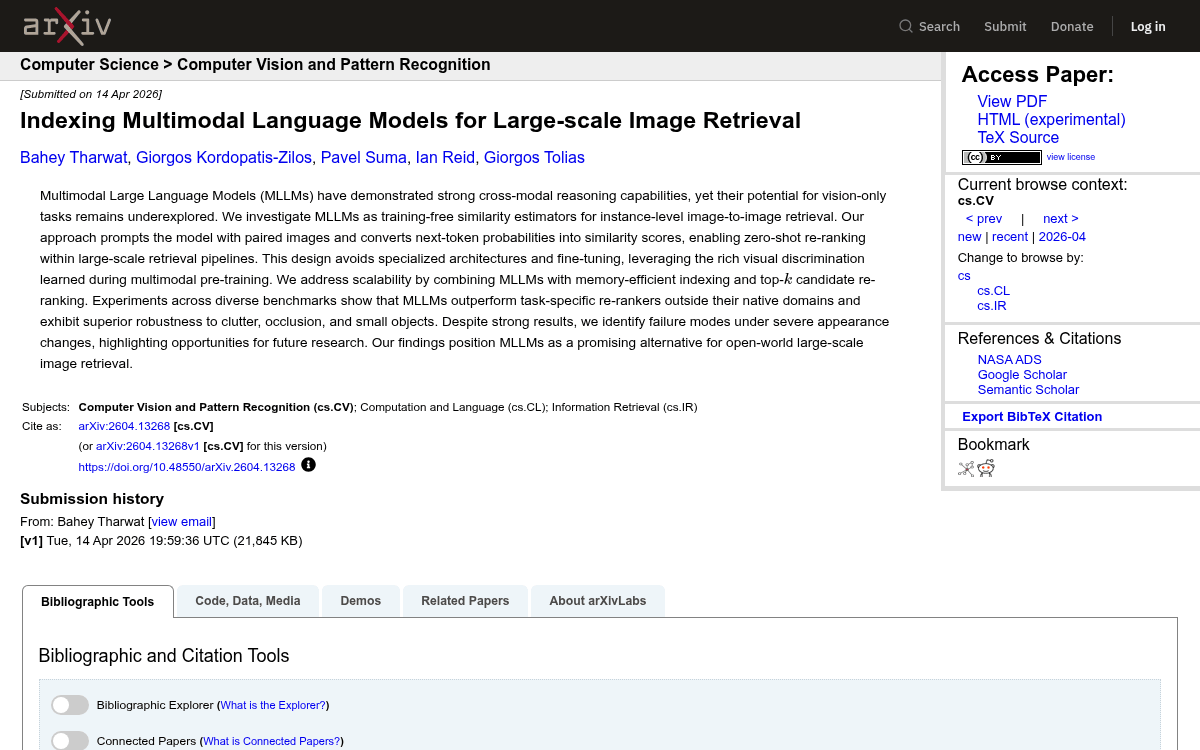
Multimodal LLMs are usually pitched as chat interfaces for images. A new paper from Mohamed bin Zayed University of AI and Czech Technical University in Prague flips that framing: it uses a frozen Qwen2.5-VL-7B as a training-free similarity engine for instance-level image retrieval, and shows it can outperform re-rankers built specifically for the job, without a single gradient step.
The mechanism is disarmingly simple. Prompt the model with paired images, ask whether they show the same object instance, and require a single-digit reply. The softmax probability assigned to the token "1" becomes the similarity score. That is the whole re-ranker.
Why bother with an LLM for pixels?
Instance-level retrieval is the fine-grained variant of image search: not "find another dog," but "find this exact dog." State-of-the-art systems typically bolt a re-ranking stage onto a global-descriptor search, using methods like RRT, CVNet, or AMES that cross-compare local patch features. They work, but they need domain-specific training data and tend to collapse outside their training distribution. AMES, for instance, is trained on the Google Landmarks dataset and excels at buildings while faltering elsewhere.
Foundation models like CLIP and DINOv3 give strong global descriptors, though global vectors lose precision on small objects, occlusion, and clutter. The authors argue that MLLMs already learned rich visual discrimination during pre-training on massive multimodal corpora, so you should be able to elicit that as a similarity function through prompting alone.
This story is for Pro members
You've reached the end of the free preview. Upgrade to AlphaSignal Pro to read the full article - and everything else behind the paywall.
Comments
