

Empero's Qwen3.8-2B Doubles Reasoning Scores Running on a Phone
Empero's tiny reasoning model squeezes a 2.4 trillion parameter teacher into a 1.3 GB file that runs on phones with a 262k context window.
 PRO
- Qwen3.8-2B-Distill-GGUF distills a 2.4T parameter MoE teacher into a 2B dense student
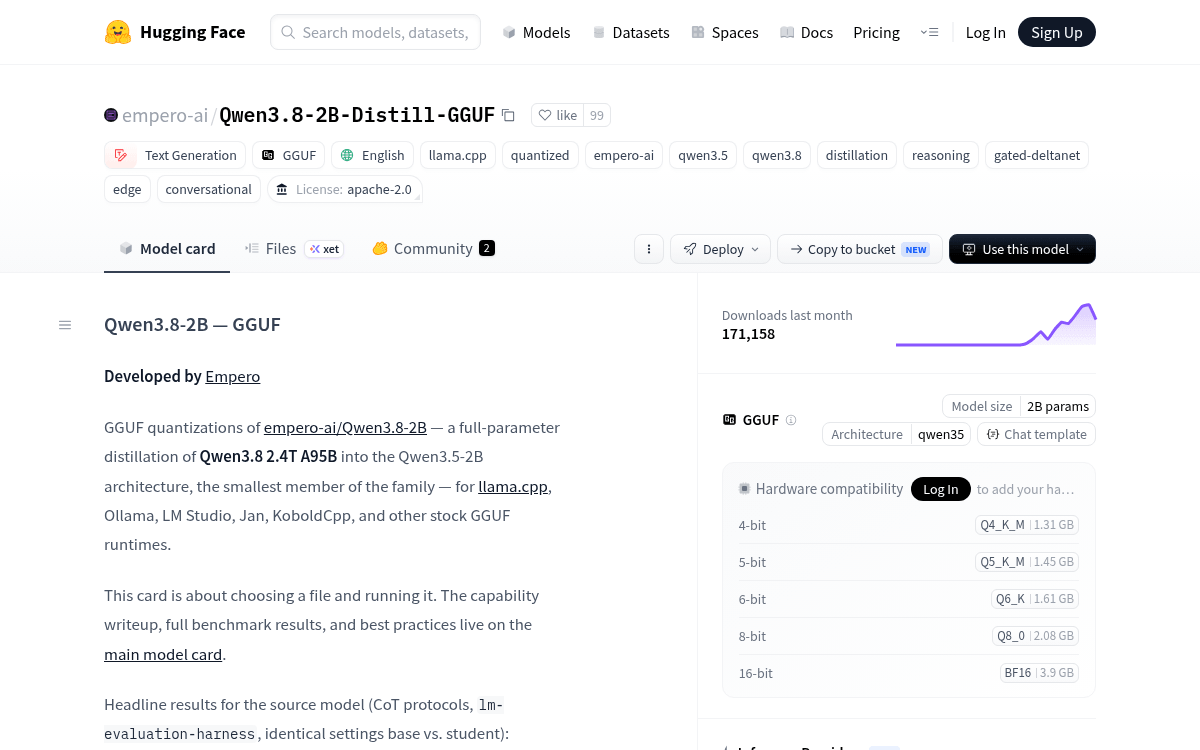
- Recommended Q4_K_M quant is 1.31 GB, runs on phones and single-board computers
- MMLU jumps from 0.283 to 0.548, GSM8K from 0.330 to 0.640 vs the Qwen3.5-2B base
- Inherits 262,144-token context via hybrid Gated DeltaNet linear-attention architecture
- Apache-2.0 license, works out of the box with llama.cpp, Ollama, LM Studio, Jan
- Text and reasoning focused; use the 9B sibling for code workloads
Empero has quietly shipped GGUF quantizations of Qwen3.8-2B-Distill, a 2 billion parameter reasoning model distilled from a much larger mixture-of-experts teacher. The recommended Q4_K_M file weighs 1.31 GB, small enough to run on a phone, yet it nearly doubles its own base model's MMLU score. Downloads on Hugging Face have crossed 171,000.
A 2.4T teacher, squeezed into 2B
The release consists of GGUF quantizations of empero-ai/Qwen3.8-2B, a full-parameter distillation of Qwen3.8 2.4T A95B into the Qwen3.5-2B architecture, the smallest member of the family. The GGUFs target llama.cpp, Ollama, LM Studio, Jan, KoboldCpp, and other stock runtimes, so the reasoning behavior of a frontier-scale sparse teacher now runs inside a dense 2B student on almost anything.
The training recipe is straightforward supervised fine-tuning on teacher traces. According to the model card, the student saw roughly 30,000 curated teacher traces from Empero's internal Qwen3.8 distillation datasets. For the sibling 9B model, Empero has stated the process uses off-policy supervised fine-tuning rather than reinforcement learning, which keeps the pipeline simple and reproducible.
This story is for Pro members
You've reached the end of the free preview. Upgrade to AlphaSignal Pro to read the full article - and everything else behind the paywall.
Comments
