

DeepSeek's V4-Flash-Vision-Exp Adds Image Understanding at Half the Cost of Rivals
DeepSeek gives its Flash model eyes with an experimental multimodal release that matches Claude Opus 4.8 on agent tasks at a fraction of the cost.
 PRO
- DeepSeek released V4-Flash-Vision-Exp, its first multimodal V4 model, under MIT license
- Sparse MoE with 13B active out of 284B params, 1M context, 131K output
- Priced at $0.22/M input and $0.65/M output tokens on OpenRouter
- Each image costs up to 384 tokens; free Files API allows image reuse by file_id
- Matches Claude Opus 4.8 on Toolathlon and ZeroBench, trails on NL2Repo and DSBench-Hard
- Available via DeepSeek API, vLLM, and SGLang with DSpark speculative decoding
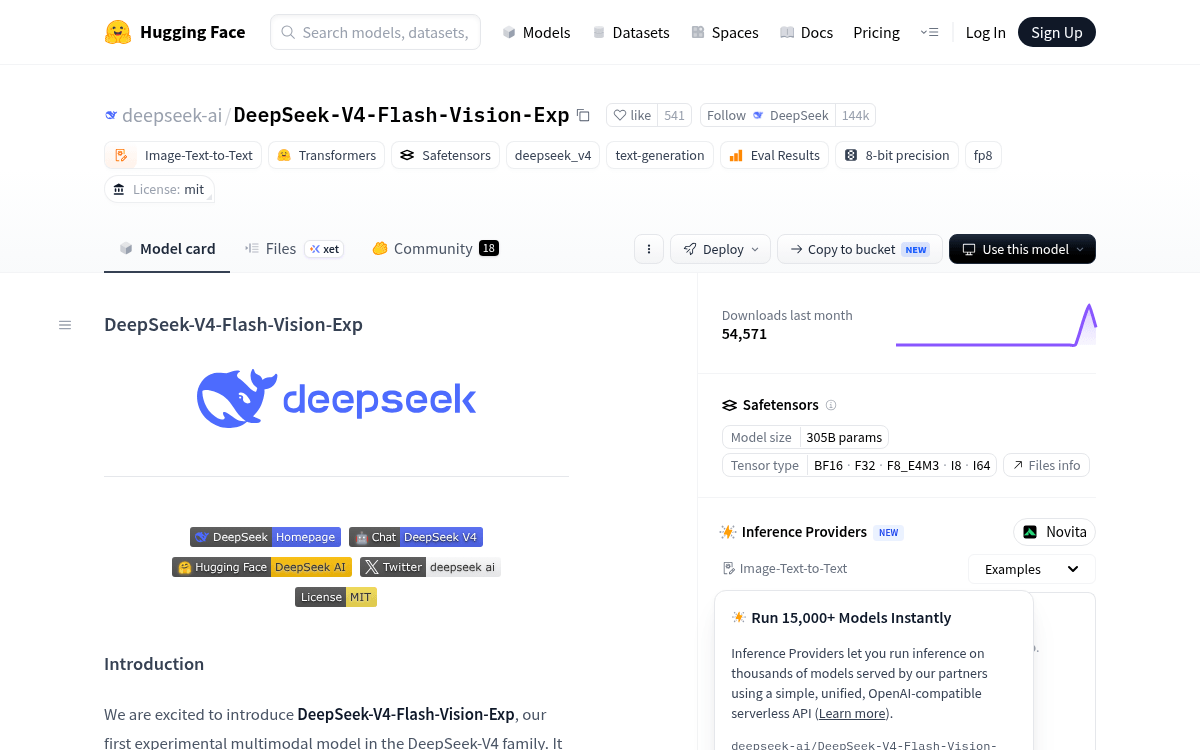
DeepSeek has quietly extended its V4 family with a vision-capable variant, and the pricing is aggressive enough to make it a real option for anyone running screenshot-heavy agents. DeepSeek-V4-Flash-Vision-Exp takes the existing V4-Flash text model, bolts on a visual encoder, and continues training to unlock image understanding without degrading text performance. The weights are on Hugging Face under an MIT license, and the model is live on the DeepSeek API under the identifier deepseek-v4-flash-vision-exp, released August 21, 2026.
What's under the hood
The architecture is a sparse mixture-of-experts model with 13B active parameters out of 284B total, which is why the Flash branding sticks even with visual modules attached. The context window runs to 1,048,576 tokens with a maximum output of 131,072 tokens. The Hugging Face card describes a stack including a vision encoder and aligner, DFlash attention, MoE routing, Hyper-Connections, and a DSpark speculative decoding path, with checkpoints shipping in a mix of BF16, FP8, and INT8 tensor types.
This story is for Pro members
You've reached the end of the free preview. Upgrade to AlphaSignal Pro to read the full article - and everything else behind the paywall.
Comments
