

DeepSeek Releases DeepSeek-LLM-7B-Chat, a Bilingual Open-Source Model Running on One GPU
DeepSeek's open-source 7B chat model, trained on 2 trillion tokens, brings bilingual conversational AI to any GPU with a commercial-friendly license.
 PRO
- Open-source bilingual chat model: DeepSeek-LLM-7B-Chat is a 7B-parameter model trained from scratch on 2 trillion English and Chinese tokens, free for commercial use.
- Trained with SFT + DPO: The chat model was built by fine-tuning the base model with supervised instruction tuning followed by Direct Preference Optimization for helpfulness and safety.
- Fits on a single consumer GPU: Requires ~13.9GB VRAM, making it deployable on an RTX 3090/4090 locally via Hugging Face, Ollama, or vLLM.
- Key benchmark scores: GSM8K 55.6, WinoGrande 74.9, MMLU 44.0 -- competitive for its size but well below frontier models.
- Main limitations: 4K context window, no system prompt support, limited to English and Chinese, and weaker on complex reasoning tasks.
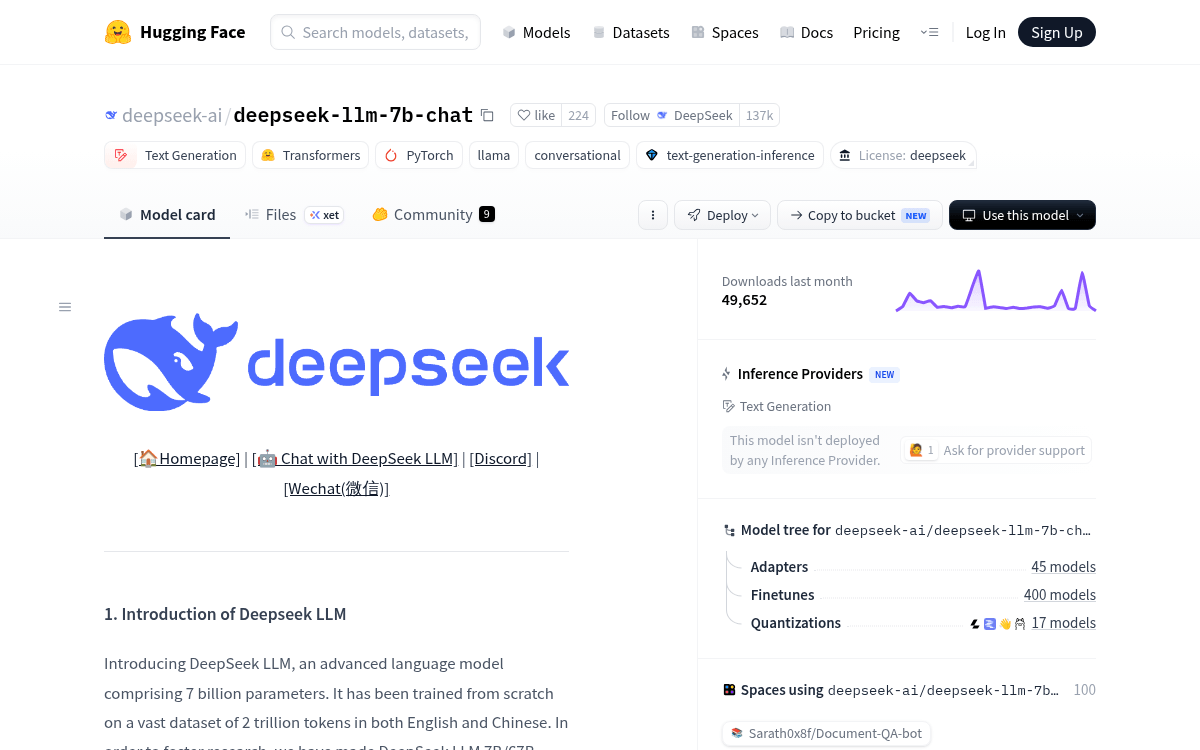
- Strong fine-tuning base: Over 400 fine-tuned derivatives exist on Hugging Face, making it a popular starting point for domain-specific model development.
DeepSeek-LLM-7B-Chat is a 7-billion-parameter instruction-tuned language model from DeepSeek AI, trained entirely from scratch on 2 trillion tokens of English and Chinese text. It sits in a broader model family that also includes a 67B variant, and it is fully open-source with a commercial-use license. With nearly 50,000 downloads and over 3,000 likes on Hugging Face, it has quietly become one of the more adopted small open-source chat models available today.
Built from scratch, not borrowed
DeepSeek-LLM-7B-Chat is initialized from deepseek-llm-7b-base and fine-tuned on extra instruction data. That base model was not a fork of LLaMA or another existing checkpoint. It was trained from scratch on a vast dataset of 2 trillion tokens in both English and Chinese, and released open-source to foster research.
The architecture follows a decoder-only transformer design, but with some deliberate tweaks. Both the 7B and 67B versions use a pre-norm design with the SwiGLU activation, which stabilized training. DeepSeek LLM 7B is a 30-layer network, while DeepSeek LLM 67B has 95 layers. The team also made an unconventional choice on the learning rate schedule: the training process used a multi-step learning rate scheduler instead of the typical cosine scheduler, which maintained performance while enabling continual training by allowing researchers to reuse earlier training phases when scaling up.
The scaling law angle
What makes this release interesting beyond the model itself is the research philosophy behind it. The scaling laws described in previous literature present varying conclusions, which casts a dark cloud over scaling LLMs. DeepSeek delved into the study of scaling laws and presented distinctive findings that facilitate the scaling of large-scale models in two commonly used open-source configurations, 7B and 67B.
This story is for Pro members
You've reached the end of the free preview. Upgrade to AlphaSignal Pro to read the full article - and everything else behind the paywall.
Comments
