

Colibri Runs a 744B Model on a Laptop With No GPU
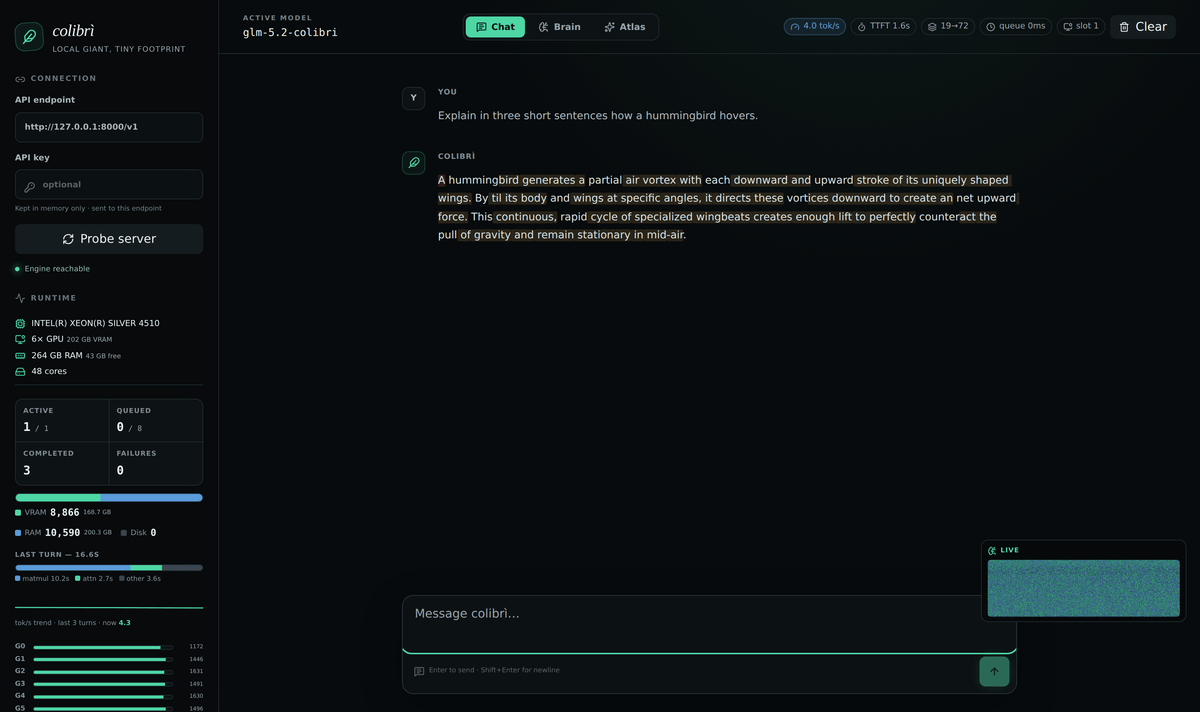
A single-file C engine streams experts from disk to run 744B-parameter MoE models on a 25GB laptop, no GPU required.

 PRO
- Colibri runs a 744B GLM-5.2 MoE model on a 25GB RAM machine with no GPU, streaming experts from disk.
- Pure C, zero dependencies, Apache-2.0 licensed, and already at over 25,000 GitHub stars.
- Also runs Inkling 975B, Kimi K3 2.8T, DeepSeek V4 Flash 284B, and OLMoE 7B through the same CLI.
- Uses learned expert caching, one-layer-ahead prefetch (71.6% hit), and dual-SSD striping for throughput.
- Same engine scales to 6.8 tok/s on 6x RTX 5090s and 1.8 tok/s on a 128GB CPU-only desktop.
- Weights on Hugging Face, code at github.com/JustVugg/colibri.
A hobby project that promised to run a 744-billion-parameter model on a laptop has become one of the most-starred inference engines on GitHub, sitting at over 25,000 stars. Colibri is a pure C inference runtime that treats storage, RAM, and VRAM as a single memory hierarchy, streaming Mixture-of-Experts weights from an SSD on demand so a giant model no longer needs giant hardware.
The pitch is blunt: GLM-5.2 int4, a 744B MoE with 40B active parameters, running on a 25GB RAM machine with no GPU. That configuration produces roughly 0.05 to 0.1 tokens per second, which nobody would call fast, but the same engine also scales up to 5.8 to 6.8 tok/s on six RTX 5090s with the entire expert set resident in VRAM. Same C file, same int4 container, only the placement changes.
Parameters as JIT-compiled code paths
The trick behind Colibri is a re-framing of what parameters are. The README puts it clearly: a 744B MoE only activates ~40B parameters per token, and only about 11 GB of those routed experts actually change between tokens. Rather than loading all 744B into memory, the engine treats them like a JIT compiler treats code paths, staging only the hot ones just in time.
Concretely, this splits the model in two:
- The dense part (attention, shared experts, embeddings, roughly 17B params) stays resident in RAM at int4, about 9.9 GB.
- The 19,456 routed experts (75 MoE layers times 256 experts, plus an MTP head, roughly 19 MB each at int4) live on disk as a ~370 GB blob and are streamed on demand.
This story is for Pro members
You've reached the end of the free preview. Upgrade to AlphaSignal Pro to read the full article - and everything else behind the paywall.
Comments
