

ByteDance Opens SandboxFusion to Run Code LLMs Across 20 Languages
ByteDance open-sources SandboxFusion, a self-hosted code execution sandbox that runs 20+ languages and powers both LLM evaluation and RLVR training pipelines
 PRO
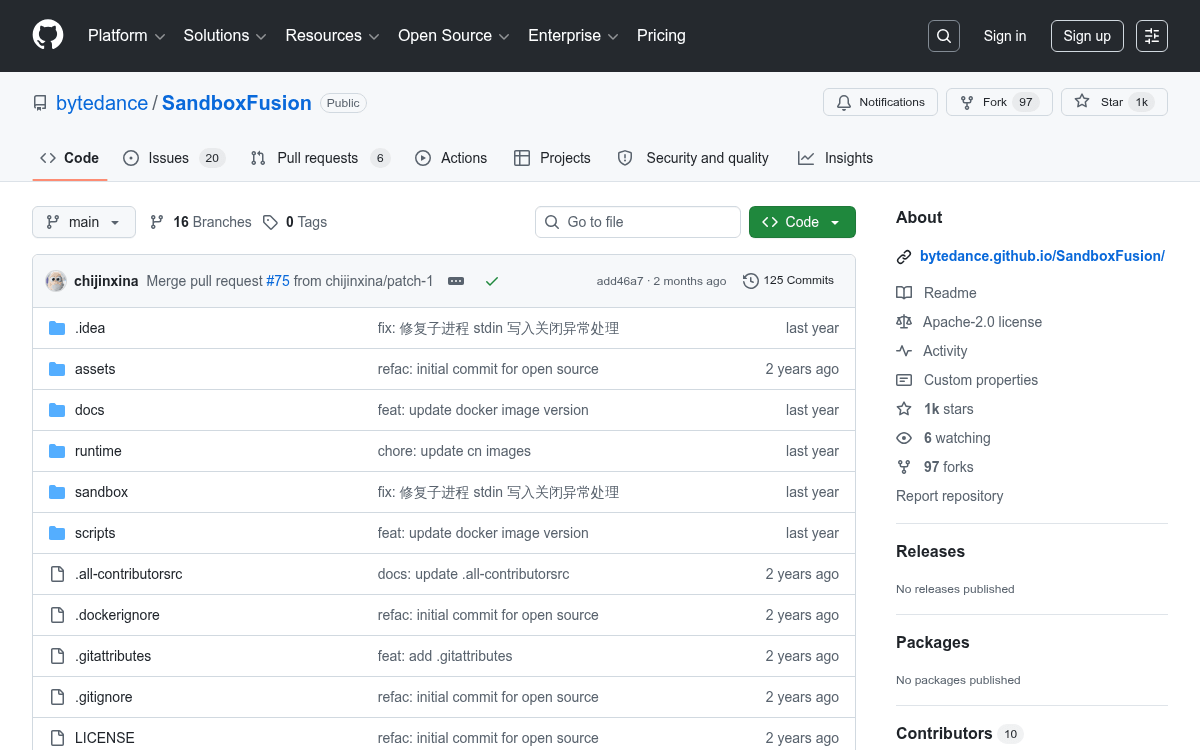
- What it is: ByteDance open-sourced SandboxFusion, a self-hosted HTTP sandbox for safely running and judging LLM-generated code.
- Language coverage: Supports 20+ languages including Python, C++, Go, Rust, Verilog, CUDA, and Lean (formal proofs), plus testing frameworks like pytest and JUnit.
- Evaluation datasets: Ships with 10+ pre-integrated benchmarks (HumanEval, MBPP, CodeContests, miniF2F, etc.) behind a unified
/submitAPI. - RLVR training use: Adopted by the verl RL training framework as the recommended code execution backend for reinforcement learning from verifiable rewards pipelines.
- Deployment: One Docker command to run; supports SLURM and cloud infrastructure; free under Apache 2.0.
- Security tradeoff: Uses Linux namespaces and cgroups for isolation -- suitable for model evaluation pipelines, not for executing arbitrary untrusted user code.
SandboxFusion is ByteDance's open-source answer to a problem every team training or evaluating code LLMs eventually hits: you need a safe, fast, multi-language environment to actually run the code your model generates. Without it, you can't score correctness, and without correctness scores, you can't train or benchmark anything meaningful. ByteDance built this internally and is now sharing it under the Apache 2.0 license.
The problem it solves
Evaluating a code LLM requires more than checking if the output looks plausible. You need to run the code, check it against test cases, and get a pass/fail signal back. This is the foundation of execution-based evaluation, and it's also the reward signal behind RLVR (Reinforcement Learning from Verifiable Rewards) -- the technique that has driven the current generation of reasoning models. RLVR is the recipe that trained the current generation of reasoning models: the sandbox is the verifier -- it executes the code and the tests, and the binary outcome is the reward.
The challenge is doing this safely, at scale, across many languages. Most existing tools cover one or two languages, or require complex per-language service setups. SandboxFusion requires only one Docker image to run, while alternatives like MPLSandbox need to launch a separate service to execute each language.
What it actually does
SandboxFusion is a secure sandbox environment for running and evaluating code generated by LLMs, providing isolated execution environments for multiple programming languages. It exposes a simple HTTP API, so any language or framework can talk to it. There are two core capabilities:
- Code Runner: Submit a snippet in any supported language, get back stdout, stderr, return code, and execution time.
- Online Judge: Submit a model completion against a named dataset (e.g., MBPP, HumanEval), and get back a structured pass/fail result with the extracted code and test details.
SandboxFusion accommodates up to 20 programming languages, enabling comprehensive testing across diverse domains including coding, mathematics, and hardware programming. The sandbox incorporates over 10 coding-related evaluation datasets, featuring a standardized data format and accessible via a uniform HTTP API.
This story is for Pro members
You've reached the end of the free preview. Upgrade to AlphaSignal Pro to read the full article - and everything else behind the paywall.
Comments
