

BentoML's OpenLLM Serves Open-Source Models 8x Faster Than Ollama
OpenLLM by BentoML lets you self-host any open-source LLM as an OpenAI-compatible API endpoint, from local GPU to production cloud, with a single command.
 PRO
- OpenLLM by BentoML serves any open-source LLM as an OpenAI-compatible API with a single command, locally or in the cloud.
- Uses vLLM as the inference backend, enabling continuous batching and PagedAttention for high-concurrency GPU serving.
- Benchmarks show up to 8x higher throughput and 8x more tokens/second than Ollama under concurrent load on a single A100.
- Supports 15+ model families including Llama 4, DeepSeek R1, Qwen 2.5, Mistral, Gemma 3, and Phi-4 out of the box.
- One-command deploy to BentoCloud for autoscaling, managed infrastructure, and observability; also exports to Docker/Kubernetes.
- Free and open-source (Apache 2.0); custom model repositories supported, though only public repos are currently allowed.
If your team is running open-source models in production, you've probably hit the same wall: getting from "model weights on disk" to "scalable API your app can actually call" is more work than it should be. OpenLLM, the open-source project from BentoML, is built around collapsing that gap into a single command.
The problem it actually solves
At its core, OpenLLM packages any open-source large language model into a production-ready API server that speaks the OpenAI protocol. That means existing code written against the OpenAI SDK works instantly with self-hosted Llama, DeepSeek, Qwen, or any custom model you choose. No adapter layer, no rewrite.
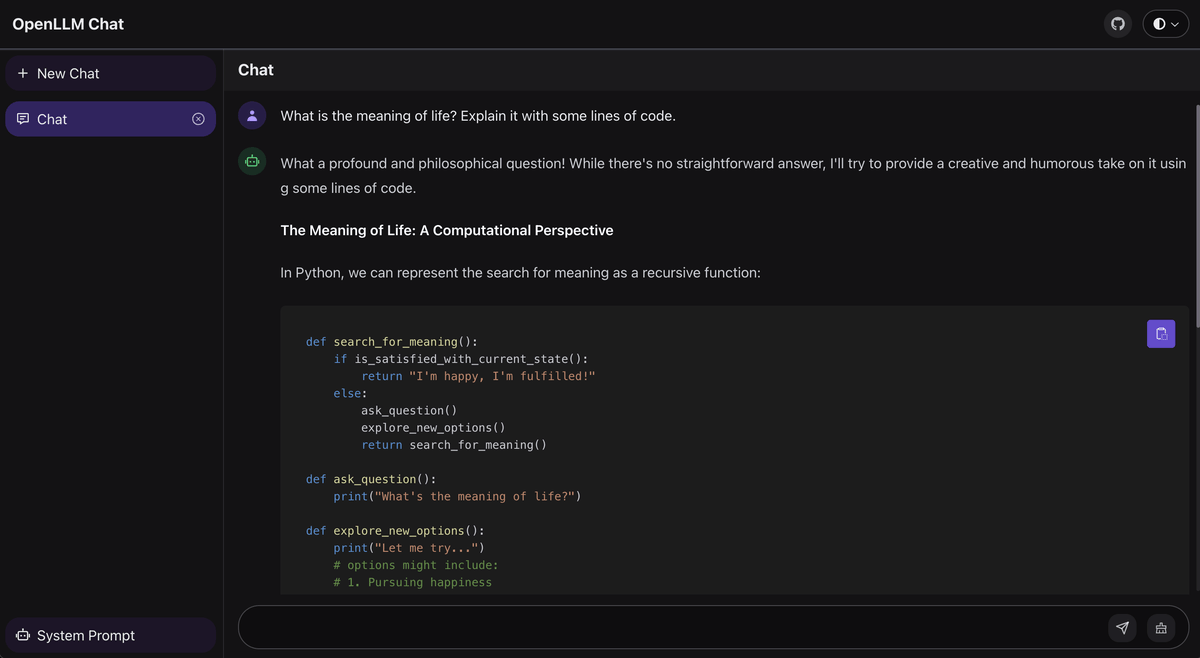
This matters because the dominant self-hosting alternative, Ollama, is optimized for single-user local use. OpenLLM allows developers to run any open-source LLMs or custom models as OpenAI-compatible APIs with a single command, and it features a built-in chat UI, state-of-the-art inference backends, and a simplified workflow for enterprise-grade cloud deployment with Docker, Kubernetes, and BentoCloud.
Under the hood: vLLM does the heavy lifting
OpenLLM is built on top of BentoML, a unified model serving framework, and integrates various components to provide a seamless experience for working with LLMs. The inference backend is
This story is for Pro members
You've reached the end of the free preview. Upgrade to AlphaSignal Pro to read the full article - and everything else behind the paywall.
Comments
