

Baidu's Unlimited-OCR Shrinks to 4-Bit to Fit on One GPU
A W4A16 quantized build of Baidu's 3B Unlimited-OCR shrinks the model for consumer GPUs while preserving one-shot long-document parsing quality.
 PRO
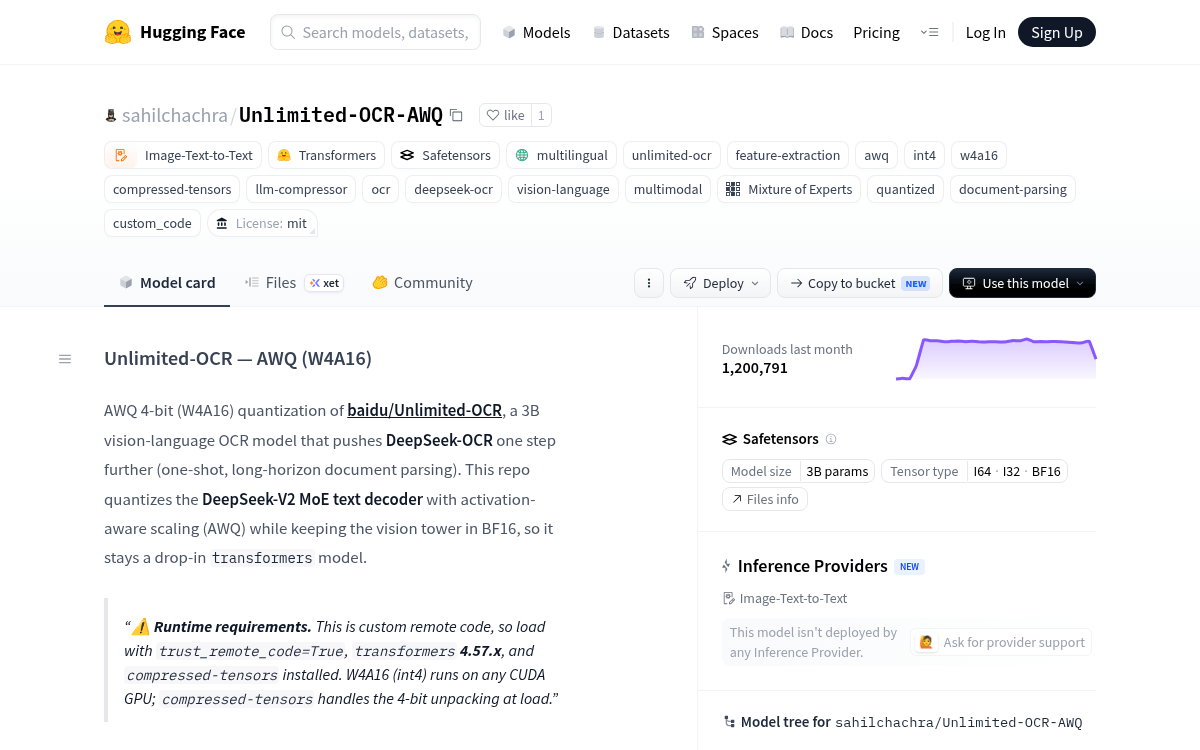
- Unlimited-OCR-AWQ is a W4A16 int4 quantization of Baidu's 3B MoE OCR model.
- Only the DeepSeek-V2 decoder Linears are quantized; the vision tower and MoE router stay BF16.
- Base model uses Reference Sliding Window Attention to keep the KV cache flat across 32K tokens.
- Baidu's original scores 93.23 on OmniDocBench v1.5, beating the DeepSeek OCR baseline by 6.22 points.
- Loads via
transformers, vLLM, or SGLang withtrust_remote_code=Trueandcompressed-tensorsinstalled. - Alternate builds exist in NVFP4, GGUF, and MLX 8-bit under MIT license.
A community quantization of Baidu's Unlimited-OCR just landed on Hugging Face, packaging one of the strongest open document-parsing models into a 4-bit weight format that fits on a single consumer GPU. The release, sahilchachra/Unlimited-OCR-AWQ, uses activation-aware weight quantization on the MoE text decoder while leaving the vision tower in BF16, so it plugs into transformers, vLLM, or SGLang the same way the original does.
The base model, in one paragraph
Unlimited-OCR is Baidu's answer to a long-standing headache in end-to-end OCR: models get slower and hungrier as the output grows, because each generated token adds to the KV cache. Memory rises, generation drags, and parsing dozens of pages becomes impractical. Under the hood, Unlimited-OCR is a 3B-parameter Mixture-of-Experts model with only 500M parameters active, and it replaces decoder attention with Reference Sliding Window Attention (R-SWA) to keep the KV cache constant.
The practical payoff is one-shot long-horizon parsing. The model handles dozens of pages in one forward pass under a 32K maximum length, scores 93.23 on OmniDocBench v1.5 (6.22 points above the DeepSeek OCR baseline), and climbs to 93.92 on v1.6, with gains holding across text, formula, and table recognition.
What the AWQ build actually changes
The quantized repo targets the parts of the network where 4-bit pays off most and leaves the accuracy-sensitive components alone. The scheme is W4A16, int4 symmetric with group size 128, produced with llm-compressor using AWQ (activation-aware scaling calibrated on text). Concretely:
This story is for Pro members
You've reached the end of the free preview. Upgrade to AlphaSignal Pro to read the full article - and everything else behind the paywall.
Comments
